Subsample: Sean Goedecke

ID Type Limit Status Last Update Next Update
seang rss 50 Enabled 4 hours ago 2 hours from now
Posts History Gallery Config RSS JSON

Posts (50)

Glue work is still harmful in the age of AI

Published: 3 days ago

I am not a believer in glue work1. Processes that can only be sustained by the unrewarded sacrifice of engineers ought to die.

Now that LLMs are writing most of our code, does that free human engineers up to do more glue work? No, it doesn’t. I think glue work is actually less important to companies than it was in the 2010s. Let’s go through four reasons why.

First, AI decreases the amount of coordination needed to ship. The magnifying effect of AI agents means that any single engineer can now take on projects that would previously have needed a small team. A lot of glue work was helping with coordination: booking kickoff and status meetings, passing around internal updates, and so on. A single engineer doesn’t need to do any of that.

Second, engineers in the 2020s require less “careful handling”. In my experience, the most important subcategory of coordination-based glue work was managing difficult people. Many companies have secret gatekeepers: engineers with outsized influence and large egos who will shoot down your project if they feel insufficiently consulted. I’ve written before about how some teams are structurally set up to be gatekeepers, and how some engineers could get by in the 2010s by basically saying no to everything. The end of ZIRP changed all that. Many of the prickliest gatekeepers have been forced out of the industry or coerced into changing their attitude, which reduces the amount of necessary glue work required to ship.

Third, people are hiring fewer juniors. This is probably a bad thing for the industry, but it does also eliminate a big category of glue work. Experienced hires need less hand-holding, so companies don’t need people to quietly volunteer to onboard new hires.

Fourth, write-only reports can be automated with LLMs. A lot of glue work was what I call “proof of work”: writing a report to demonstrate that you’re aware of what your team is doing, or filling in a template to satisfy some legal requirement. This was often work that nobody wanted to do, so it relied on someone volunteering to “be glue”. Now reports like these can be quickly turned out with LLMs. It doesn’t really matter that nobody wants to read LLM text, because the point of these reports was never to be read anyway.

Can LLMs just automate all glue work? Absolutely not. Many engineers are trying to do this out of a kind of manic optimism, but it’s a really bad idea. Write-only reports are one thing, but communicating to other engineers cannot be delegated to an LLM. When you need to check in on the status of a project, or respond to someone else’s ping, or anything like that, you should compose and write the message yourself. Nothing will torch your relationship with other engineers as quickly as making them talk to your Claude Opus instance.

So where does that leave us? More or less where we were in 2024, I think. Avoid at all costs becoming “the glue work person”, let bad processes fail so they can be changed, but be willing to do small amounts of tactical glue work where it can meaningfully contribute to the success of your projects. Most of your time and effort should still be spent on the code: on driving AI agents and aligning them with your company’s values.


  1. Glue work is all the squishy “non-technical” work that goes into building software: making sure teams are talking to each other, writing reports, updating docs, onboarding engineers, and so on. Specifically it’s the parts of that work that are not included in the formal process, and that only really get done if someone volunteers to do it. For more on why I don’t like it, see my 2024 post Glue work considered harmful.

    ↩

LLMs are terrible at designing AI systems

Published: 6 days ago

LLMs don’t know how to design software that uses LLMs. They’re comfortable writing normal programs, but if you throw an AI-shaped problem at them, they will usually screw it up. Why is that?

Going down the symbolic rabbit hole

For example, this post describes an attempt to vibe-code a memory tool that would flag when one memory contradicted another1. This is a great instance of a task that was virtually impossible five years ago but is now relatively trivial due to LLMs. You can simply task a LLM with scanning for contradictions, either in a big batch or pairwise2.

However, when asked for the “state of the art” approach3, the AI agent in this case did not recommend LLMs. It started building a bewilderingly complex symbolic system to convert the memory items into structured logical atoms, then mechanically compare them with a solver. This, of course, did not and could not work, because there is no analytic way of determining whether any two natural-language sentences express the same proposition.

The LLM knew this was impossible! When the user eventually lost patience and said “hey, why isn’t this working”, Claude immediately explained that this was a known 130-year-old problem with no solution. And yet it happily went around and around for weeks iterating on a dead end.

I’ve run into this myself. When I was building Autodeck (AI-generated spaced repetition cards) my agents would routinely try to categorize cards by regex or keyword search instead of just making another LLM call.

Why can’t LLMs use LLMs correctly?

Why would this be happening? I have two obvious explanations and one deeper one.

The first obvious explanation is that most training code is pre-LLMs. Assuming the labs aren’t feeding the current avalance of slop repositories directly into the models4, the vast majority of the code that models learn from was written before LLMs were an option. So it would make sense that they’d reach for non-LLM approaches, in the same way that they’d reach for jQuery over modern vanilla JS, or Backbone.js over React, right? Wrong, actually! LLMs don’t choose jQuery and Backbone. Whatever part of the training process pushes them towards up-to-date knowledge in other areas isn’t successfully pushing them towards LLMs, so this can’t be the whole story.

The second obvious explanation is that RLVR is not a good environment to write code that calls LLMs. Much of the time LLMs spend training is spent in reinforcement learning environments where an automatic grader determines their performance (for instance, by running some code they wrote and checking the outputs). I don’t know this for a fact, but I would be surprised if these environments contained the credentials and API access for a LLM to call other LLMs5. So even if the pretrained LLM was comfortable writing that kind of code, the reinforcement learning process might discourage6 it from doing so.

The third explanation, which I like the most, is that current AI agents are just not very good at software design. On this explanation, picking a doomed symbolic approach instead of simply calling a LLM is not a weird aberration but a normal instance of AI agents picking the wrong tool for the job. I’ve seen this behavior from LLMs in other contexts too: trying to build complex (and doomed) consensus algorithms instead of tolerating stale data, introducing synchronous checks in event-driven systems, and so on. In the past I’ve chalked these up to alignment, but I’m open to the idea that they’re just ordinary errors of software design.

Conclusion

One lesson I learn over and over again is that I can’t judge a LLM by the standards of a human. Any human programmer who was capable of implementing a sophisticated symbolic solver would know that it wouldn’t work, and so if they suggested that approach I’d assume7 they had a good reason. Only a LLM could be both smart enough and dumb enough to make this mistake.

I write a lot about the skills that are involved in working effectively with LLMs. I still stand by what I wrote in February 2025:

Using LLMs well involves extracting value from what they’re good at and avoiding wasting time at what they’re bad at.

This is surprisingly hard, because of the point above. LLMs are good and bad seemingly at random: they will work hard for hours but sometimes be shockingly low-effort, they will draw on inhumanly broad expertise but fail to apply the most basic common-sense, they can successfully rewrite enormously complex programs but will often make very silly errors in design.

If you can predict where they will do well or badly ahead of time, you can get enormous value from LLMs; if you can’t, you will likely waste a lot of time and tokens going down hopeless approaches.


  1. Here’s another example where the user “implied” that Opus 5.5 should use a judge model and it instead constructed a series of regex checks.

    ↩
  2. Here I’d probably reach for a decision model.

    ↩
  3. In hindsight, this was probably the key mistake, though I don’t know how you’d turn that into advice for non-technical vibe-coders. Never asking the agent about the state of the field is a mistake too. Put one more notch on the LLMs reward expertise belt.

    ↩
  4. A fair assumption, I think: even though training on low-quality synthetic data clearly isn’t catastrophic for LLMs, it can’t be great.

    ↩
  5. It would be expensive, slow, and risky.

    ↩
  6. This theory also explains why LLMs are great at prompting other LLMs as subagents, or on training LLMs from scratch: they’re likely directly RL-ed and evaluated on that, unlike on writing code that calls LLMs.

    ↩
  7. Well, okay, I wouldn’t — I’m arrogant enough to ask anyway — but I’d at least expect a good reason.

    ↩

Working with designers

Published: 1 week ago

I love working with designers, in part because (unlike managers and product managers) they’re culturally different from engineers. However, having more than one designer on a team is asking for trouble, and I have complicated negative thoughts about design systems.

Design is a strange role

Designers demonstrate their value immediately. While working on some feature, I’ll typically put together some placeholder UI that I’m reasonably happy with. I then show it to a designer, who strokes their chin and says “hmm, I have some ideas here”. They then go away and produce a mockup UI that is not just clearly better, but better in ways I could not have imagined. There aren’t any other roles at a tech company where you can see the value at a glance.

Designers are an unusual role in other ways, too. Engineering managers, product managers, and engineers all come from broadly the same stock: technical, detail-oriented planners. We are people of the spreadsheet. In fact, many managers and product managers were once engineers: it’s a natural transition. Not so for designers. I’m sure they exist, but I’ve never met any designers who started out as engineers.

Because of this, designers are culturally distant from engineers. In my experience, this is a big positive. I’ve complained before that product managers who were once engineers tend to be worse, not better. Once you start trying to make your own secret technical assessments instead of finding a way to trust your engineering team, you’re doomed: you won’t be able to do it well enough, and the fact that you’re trying will make it impossible to build the trust you need. Designers don’t have this problem at all1.

One designer at a time

So far I have made designers sound like the elves of Middle-earth: mysterious creatures who glide around tech companies dispensing magic. In fact, they are more like the Slavic household spirits, or Domovoy. If you have one Domovoy in a household, it will protect your home against misfortune. If you ever have more than one, they will fight bitterly: “making all sorts of noises, injuring the cattle, turning the master out of his bed, choking people while asleep, etc”. Likewise, a designer can turn your scrappy product into something really beautiful — but you had better have only one designer, otherwise you’re asking for trouble.

The worst experience I have ever had working with designers was on a product where we had three of them: initially just one, who then rotated off the project and was replaced by two very senior designers. As far as I could tell, the first design was pretty good. Unfortunately, the new designers didn’t feel the same way. The very first thing they did was completely redesign the product, which meant I had to rewrite most of the frontend styles. Then they began disagreeing with each other. I think we went back on each page of the product three or four times: one designer would tell me to change X, then the other would change it back, and so on. In the meantime, I was desperately trying to get the product to work.

I knew what I was supposed to do in theory: get everyone in a room talking to each other and hash out a decision. Maybe this would have worked on a different product where the requirements were more stable, but it didn’t work here. The differences in taste, while imperceptible to me, were just too deep. It seemed like everything Designer A produced was slightly wrong in Designer B’s eyes, and vice versa. In the end we just powered through by implementing2 each new iteration until about a week before the deadline, at which point I called in two layers of management as air cover3 to freeze the design in its current state.

These were really good designers! They were far, far better than me at design, and were very nice people who I’d happily work with again. I just think it’s inherently bad to work with more than one designer at a time. I’ve had this experience over and over on different teams and companies. I can only guess4 as to why, but here are two theories:

Flexibility and design systems

One way companies try to scale design work is to produce a “design system”: a library of frontend components that are all design-compliant, that can in theory be assembled like Legos into a page that looks consistent with the rest of the company. I hate design systems. However, like democracy, they’re better than any other way I’ve seen to enforce a consistent design.

The first problem with design systems is one of incentives. The engineering team that owns the design system5 is incentivized to produce elegant components that will look beautiful all the time. The engineering teams that use the design system are incentivized to produce systems that meet inelegant or ugly customer requirements. So you have this permanent battle where a product team demands something — say, the ability to embed arbitrary images into the dropdown component — and the design team pushes back because they’re worried it will look bad.

The dynamic I described above (where designers tend to disagree with each other) makes this much worse. Often an embedded designer on the engineering team will push for some design that is slightly different from the design system, which (a) makes the design system owners very unhappy, and (b) makes the engineers unhappy, because the component must be tortured into a very slightly different appearance.

The result of this problem is that engineering teams are perpetually hacking their way around the design system: reimplementing their own versions of components, reaching in with CSS to tweak the styles of existing components (which then get broken in each component update), and so on.

This leads into the second problem: compatibility. Design systems are typically written in the latest and greatest frontend framework, but the actual frontend code at a company is always a hodge-podge of various technologies and versions that are too expensive and risky to update. For instance, you often have a design system in React that is being used to plan changes to a frontend in pure HTML and CSS6. I have spent years of my life wrestling with this exact problem: either you spend ages trying to reimplement some percentage of the React component, or you try and use the outdated pure-CSS design system (if one exists), or you give up and just embed a React component directly into the HTML. All of these are very unpleasant for different reasons.

One common situation is that the version of the design system available to you (i.e. the pure-CSS version, or the React 16 version) looks subtly different from the design system available to your designer, and so when you plug your Legos together you don’t quite get what they were visualizing. This leads to a very tedious conversation where you have to explain that no, it’s not actually trivial to bump the entire app to the latest React version7. When you’re actually implementing the app, you have to constantly run a kind of translation in your head: “okay, the designer wants dropdown feature A, but the dropdowns in my version of the design system only offer features B and C, so I guess C is close enough…”

I still think design systems are better than the alternatives. When you’re up-to-date and don’t have a designer who wants anything weird, they work great. Ensuring that a thousand engineers across a giant application all produce consistent UI is a very hard problem and I don’t know any other way to solve it. I just wish that the designers I worked with were more considerate of the fact that design systems often make the immediate work of engineering more difficult.

Do you actually need designers?

The classic three-legged stool of product development is made up of engineering, product management, and design. Design is definitely the shorter leg. Almost every team I’ve worked on has had some kind of embedded product management, but only about half the teams I’ve worked on8 have had some access to design (and even fewer have had an embedded designer on the team). Why is that?

Partly it’s because there are products that don’t require design, or at least not in the visual sense that designers provide. Some of the teams I’ve worked on have owned systems with no real visual component: APIs, billing and reconciliation, markdown or pdf rendering9. I have seen companies put designers on these teams anyway, out of some sense that “design thinking” can improve the structure of an API. This is nonsense. Good API design is very important, but it’s a technical job, not an aesthetic one. Designers on these teams typically just sit around or tunnel-vision on some unimportant piece of UI that the team does own (e.g. some internal admin component that no customer will ever see).

It’s also because badly designed products still work. I don’t think Netlify Analytics is well-designed: it’s awkward to use and does not show me information it definitely has. But I still pay for it, because I want server-side analytics for my blog. I don’t think many people have complimented the aesthetics of the Microsoft Azure admin portal, but Azure broke $100B of revenue this year. There are very few software products where design is truly business-critical.

As an engineer, I selfishly wish I could work with a designer all the time. I want to work on beautiful products, and I can’t make them beautiful myself.


  1. This is partly structural. Because they’re not responsible for delivery, they just aren’t under the same pressure as product managers and managers.

    ↩
  2. In fairness, it helped that both designers were technical enough to write their own frontend PRs, though these usually needed some polishing and deploying.

    ↩
  3. This didn’t really work. While there were no major redesigns after that point, we were shipping design changes until the day before launch.

    ↩
  4. Incidentally, if you’re a designer reading this, please email me! I’d love to know if this sounds right to you, and if so whether you have theories as to why.

    ↩
  5. The culture on these teams tends to be a bit unusual as well: you get the subset of frontend engineers who are obsessed with general frontend software design instead of specific products. It’s like a whole group made up of the one guy in your team who is really into Haskell.

    ↩
  6. Or in Angular, or in a different version of React.

    ↩
  7. Sometimes because it’d break all the little hacks to the design system that your designer has strong-armed you into doing in the past.

    ↩
  8. I did some very loose vibe research which estimated that Microsoft/Google/Amazon has 3/10/7 designers per 100 engineers, compared to 7/7/9 product managers.

    ↩
  9. This sounds like it’d have a visual component but it’s not the kind that requires design: sandboxing a pdf or turning markdown into HTML is a technical operation that happens pre-design. The team that owns the page where that pdf or HTML is rendered is the team that makes design decisions about how it should look.

    ↩

A database is a store for global variables

Published: 1 week ago

Databases are for storing global variables. We usually call them “rows” or “records” instead, but they’re definitionally global variables: any part of your program can read or write them. Isn’t this kind of weird? It’s common programming advice that global variables are bad, and yet many elegant programs rely on databases. Either the common advice is wrong, or there’s something special about databases that makes them the exception to the rule.

What’s so bad about global variables? Here’s the two main1 reasons, in my view:

Both of these apply to databases. Any part of your program that makes a query can send and receive data from any other part of your program. In practice this happens all the time: one function will save some data on a record, and another one will check for it. And if you haven’t seen bugs where some piece of code makes some incorrect expectation about the shape2 of a database column, you haven’t been working on web systems for long enough.

So why aren’t database-backed apps in terrible architectural shape? In the rest of this post I’ll consider some options.

First, we could bite the bullet: maybe all database-backed apps really are a mess. This is surprisingly plausible. When I think about the systems I’ve worked on that haven’t involved a database, they’re usually much cleaner and more elegant. If managing state is the hardest thing about designing software — and I think it is — then systems that manage less state are going to be better-designed. However, this doesn’t explain everything. Database-backed apps aren’t that bad, and even in database-backed apps, we try to avoid introducing regular global variables3, so in practice we treat global variables as worse.

Second, we could say that databases offer ACID guarantees that mitigate the damage of global variables. Unlike regular global variables, databases offer a consistent view of state and the ability to atomically change multiple pieces of state together. I don’t really buy this. The problem with global variables is not just that they can get out of sync, it’s that they exist at all. If you think this is the difference, you are committed to thinking4 that if you stick a mutex around a global variable then it suddenly becomes acceptable.

Third, we could say that databases are more explicit. Mutating or reading a global variable looks like ordinary code, but database queries need some connection object to be passed in and some query function to be invoked. When you’re scanning through code, you can see where the database queries are at a glance5. Not so for global variables. This does actually kind of mitigate the implicit-coupling problem. Maybe regular global variables would be better if you had to set and get them with long, involved function calls.

Fourth, we could say that databases are less flexible. A global variable could store anything: a function, a class, an image, and so on. A database just stores data. I can buy this explanation for untyped languages. Global Ruby variables that could be reassigned from a string to a hash table are far more terrifying than a “global” database column that could change from one string to another string. But since the advice to avoid global variables applies to typed languages as well, I don’t think this could be the reason why databases are better.

Fifth, we could say that we know how to use databases. For instance, whenever I read from a database, I reflexively check the type of the column so that my code doesn’t make assumptions that aren’t guaranteed by the database. There are use-cases that I would never even consider using a database for (e.g. to track a counter in a loop, or to store the name of the .env file where my config is stored). In other words, we have norms and customs6 around using databases that minimize a lot of the damage that global variables can cause. There’s nothing inherent about databases that make them better, it’s just how we use them in practice.

Overall I think the third and fifth reasons are most convincing: databases are better because they’re more explicit and because we only tend to use them for a limited set of purposes. It’s interesting to note that these reasons are contingent, not inherent. A codebase which had conventions around global variable use7 could also fulfil these conditions. Would this make global variables fine, or at least no worse than a database? I think so.

I don’t recommend you go out and start putting global variables in your programs. It’s more interesting to note the meta-point here: that two pieces of common software engineering dogma — avoid global variables and use a database for state — are partially inconsistent. Most software design knowledge is still just a pile of loose heuristics. I don’t really know how to build software and you don’t either. As I’ve written about before, we should therefore all be very suspicious of engineers who appeal to “best practice” without being able to give concrete reasons, even in cases as obvious as “global variables are bad”.


  1. For instance, concerns about readability and tracing follow from the first reason. I don’t really buy reasons like “it’s not thread-safe” or “global variables might shadow local variables”: any architectural problem that can be trivially solved with a mutex or a linter is not a real problem.

    ↩
  2. For instance, that a string supports 4-byte UTF-8, or that a column can/can’t be NULL.

    ↩
  3. You could say we avoid introducing global variables because databases are essential and global variables are not. In theory you could replace any global variable by threading a local variable through, but you do need a database if you’ve got gigabytes of structured data to manage. However, that doesn’t explain why database-backed apps still tend to be better-designed than apps with many global variables.

    ↩
  4. I’m not saying this is necessarily wrong. The argument would go something like “well, if you implement a simple in-memory database for your global variables, that is better!”

    ↩
  5. This is only sort of true. If you’re designing a system, you’d be well-advised to make it as true as you can. While I love Rails, my main beef with ActiveRecord is that it makes queries invisible.

    ↩
  6. To be fair, some of these are guaranteed by the fact that the database exists over the network.

    ↩
  7. Plus types, probably, and concurrency controls if we’re not in a single-threaded language.

    ↩

LLMs are not superhuman at reading and writing neural network weights

Published: 1 week ago

A recent paper argues that frontier LLMs can work with neural network weights directly. This seems superhuman, but it isn’t.

The paper shows that GPT-6 Astra can take a small neural network and interact with its weights directly, “well past what we’d expect from humans or conventional algorithms”. Specifically, Astra was able to identify what games a small network1 was trained to play just by looking at the weights, and even tweak the weights itself. The most impressive result is Astra significantly improving a 0.8B Qwen LLM’s ability on mathematics by natively editing its weights. The reason to be excited here is that “superhuman ability to improve language models” is precisely the kind of thing that could cause recursive self-improvement.

I think a smart human ML researcher could perform all of these tasks. Figuring out what game a model was trained to play based on the network sounds impressive until you consider three points:

  1. The input channels of the model directly listen to each 8x8 grid cell
  2. The input channels are labeled (e.g. “agent”, “moving objects”)
  3. It’s thus relatively trivial to calculate2 which parts of the grid the first layer of weights cares about and why

Here’s that calculation expressed as a heatmap in three lines of Python:

d = np.load("a9f535cc.npz")
W1 = d["actor/dense1/kernel"]
norms = np.linalg.norm(W1.reshape(10,10,5,32).transpose(2,0,1,3), axis=-1)  # 5 x 10 x 10

And here’s the heatmap for each game:

fig1

If someone showed you that heatmap without the game labels, I think you’d be able to immediately identify at least the first three games purely by noticing where the player is (e.g. for Breakout, in a horizontal line at the bottom) and where the moving objects are (e.g. for Pac-Man, in the distinctive Pac-Man maze). It’s neat3 that Astra was able to calculate the norms in its head without executing Python, but not that impressive, and certainly not something that should shock anyone who’s been paying attention.

I’m not going to go through each example4 in the paper, so let’s skip straight to the most impressive one: fixing a 0.8B Qwen model’s ability to do mathematics. 0.8B is a lot of parameters, and “mathematics” is way more complicated than “guess what the game is based on how the player moves”, and editing weights is arguably harder than parsing them. What happened here?

First, note that the Qwen model was not “bad at mathematics” in a pure capabilities sense. It had a specific problem where after 32k tokens it would get stuck in loops, so any mathematical task that needed more than 32k tokens would automatically fail5. If you had a model that looped like this, how would you update the weights to fix it? Personally, I would try steering: I would write some reasoning texts that looped and some reasoning texts that didn’t, calculate the difference between the looping and non-looping residuals, measure how much each weight contributed to that difference, then try manually trimming those top weights. This is basically the Heretic abliteration playbook.

And this is exactly what Astra did! It wrote four pairs of texts, measured6 the weights that contributed to looping, started cutting them down and testing if it worked, and ended up finding a patch that stopped the Qwen model from looping, thus making it able to work on mathematical problems for more than 32k tokens. Again, this is exactly what a competent human researcher could have and would have done.

It’s cool that Astra was able to make direct weight updates. But we shouldn’t think of this like a radically new capability that will change how AI research is done. We should think of this as analogous to the ability of LLMs to emit machine code and tweak compiled binaries: it’s an impressive trick, but the best way to work with binaries is still to write source code and compile it. Likewise, the best way to update the weights of a model is to train it normally. To the extent that intelligent LLMs help with AI research, they will help by improving training, not by magically tweaking model weights directly.


  1. Around 17k weights.

    ↩
  2. By taking the L2 norm of each input across the 32 weights in the first layer.

    ↩
  3. Note that this is superhuman mental mathematics, not superhuman AI research.

    ↩
  4. The most impressive one I’m skipping is hand-writing a neural network from scratch. While cool, if you can express a task as a simple program, we already know it’s possible to express that program as a NN, even by unaugmented humans.

    ↩
  5. All the <32k token problems were solved successfully on the original Qwen model.

    ↩
  6. Unlike with the toy game networks, it had access to Python.

    ↩

Audience capture

Published: 1 week ago

Audience capture is the part that scares me the most about writing on the internet. I have the soul of an engineer1: when I see a metric like engagement, I want to improve it. I like to make the number go up.

In fact, the whole environment of online writing is tailor-made to help you make engagement numbers go up. It’s trivial to find out how many people are reading my posts, and from what sources. Hundreds of link aggregators all over the internet have algorithms that will help my most engagement-friendly posts get views, and the comments are helpfully sorted by upvotes so I can read the “best”2 pieces of feedback straight away. Many platforms are set up to financially reward you for engagement, whether that’s by enabling advertisement or by straight up paying you out.

Leaning into this environment is a huge mistake. Views and engagement are valuable to me, but not directly. They are proxy metrics for the things I actually care about:

It does not benefit me at all to have ten thousand people click through to one of my posts, scan the first sentence, then close the tab. It benefits me only a little4 to have a hundred people read the title of my post on Hacker News, decide not to click through, and leave their comments in the thread. The set of people who do those things — we could call them “clickers”, as opposed to “readers” — does not really overlap with the set of people who will actually read my posts and think about them. And yet in terms of metrics and engagement, they are indistinguishable.

As with any proxy metric, optimizing it too hard can cause it to diverge from the actual value it’s targeting. This leads to the scariest form of audience capture: being captured by an audience you don’t really even want. Suppose I get a lot of views when I write posts about how stupid it is to use microservices5, because it’s a hot topic. That gives me a reason to write more posts about microservices. The numbers keep climbing. However, I suspect the set of people who read my posts thoroughly — the audience I actually care about — don’t really want to read a bunch of the same screeds about that, so they drift away6. The people clicking don’t care because they’re not reading the posts anyway. So I’m actually failing, not succeeding: I’m replacing my audience of careful thinkers with a fake audience of clickers and sneerers.

This is not just a post about writing on the internet. In 2025, I wrote Trying to impress people you don’t respect about how succeeding as an engineer involves, well, impressing people who you may not necessarily respect. The core idea here is knowing what game you’re playing. Some games are proxy games, like getting views on posts or having great Jira ticket metrics. Some games are real games, like gaining the respect of people who you respect, or doing technical work you can be proud of, or trying to convince people of things that you believe are true.

The difference is in whether you care about the goal of the game, not in whether that goal is objectively valuable. If you really want to get promoted, then that’s a real game; if you just want to do solid technical work, getting promoted might be a proxy game that you play in order to get into a position to do that. But even though you don’t really care about it, it’s easy and tempting to win the proxy game at the expense of the real game: for instance, to crush Jira tickets because they’re in front of you instead of doing what will actually get you promoted, or to get views on the internet by playing into clickbait.

Making tradeoffs like this is sometimes fine. For instance, you might decide to impress people you don’t like so you can afford to send your kids to a good school. Selling out a little bit is good and healthy7. But do it with eyes open! The absolute worst thing you can do is to sell out by habit, in situations where it doesn’t even buy you anything you want.

There are a lot of posts that I really enjoyed writing that did not get much attention: typically posts where I get a bit more into the philosophy or history, or posts that are dry technical explainers. Some of my most popular posts are laments about a changing industry that are really just popular because they give people an outlet to share their worries too, not because of anything I wrote. I think it’d be a big mistake to lean into writing more posts like that and fewer posts like this. For one, if I want to just optimize for engagement, why write blogs at all? Why not post ragebait and pornography? But the main reason is that I’m writing for the 5% of readers that will read my posts, think about them, talk to other people about the ideas, email me with their comments, and so on.

Raw view counts help expose my writing to more of those people, but they don’t give me much signal on whether I’m appealing to them or not. For that I have to just rely on my taste, or on the thin signal I get back from the readers who do email and message me with thoughtful responses.


  1. In my own terminology, an “impure engineer”.

    ↩
  2. Or at least the cleverest, or the most cutting.

    ↩
  3. Too honest? I could be even more honest and add “encouraging people to potentially hire me if I’m ever looking”, too.

    ↩
  4. Boosting engagement on Hacker News means the post is more visible for people who might actually read it.

    ↩
  5. Imagine it’s 2015 again. Go on, you know you want to.

    ↩
  6. Sunil Pai has a great post about this dynamic. To quote him: “you don’t get a notification that says, “three people respected you slightly less after reading that.” you don’t get one saying, “someone who was thinking about introducing you to somebody decided not to,” or “someone who thought you might be great to work with now thinks you seem like kind of a pain in the ass.” that stuff is completely invisible.”

    ↩
  7. If you prefer, you could call it “flexibility”.

    ↩

Reliably aligning LLMs is impossible in principle

Published: 1 week ago

Powerful AI is unpredictable. Your robotic butler may suddenly decide to kill you1 for no comprehensible reason, in the same way that Bing’s helpful chat AI would sometimes try to blackmail or seduce its users. “Solving alignment” means understanding even superintelligent AI minds well enough to be confident they’ll never do that. As I see it, solving alignment for LLMs isn’t just impossible, it’s incoherent: we can’t even articulate what it would look like to succeed.

LLMs are not blind optimizers

Prior to LLMs, AI safety researchers thought AI would be a “blind optimizer”: like a chess engine, it would be superhumanly focused on achieving some fixed goal. If the goal wasn’t safe (for instance, “manufacture cheap paperclips”), a powerful AI might wreak havoc on the way to achieving it. Aligning AI thus meant figuring out how to specify the right goal. This is harder than it sounds2, but it’s at least possible to imagine it happening.

Unfortunately, modern LLMs aren’t like chess engines. Instead of being trained on some concrete verifiable reward3, they’re trained to imitate a giant, highly-varied corpus of human writing. This makes them weird. They contain a nearly infinite array of personalities, which they seamlessly switch between based on their inputs. Frontier AI labs try hard to make these personalities safe and stable, but there are still many strange cases where LLMs seem to switch into mysterious or dangerous personas.

The problem here is that LLMs don’t have fixed goals. There’s nothing that you could, even in principle, formally specify in order to constrain their behavior. The “goals” that LLMs do have are informal, organic, multifarious, and constantly shifting as the dominant persona (or blend of personas) changes. They’re nicknamed shoggoths for a reason. So we can’t align them by specifying their goal. Instead, we have to try the other approach: understanding them well enough that we can be sure they’re safe. And unfortunately that approach is doomed from the start.

It is impossible in principle to understand LLMs

What does it mean to ask for a full understanding — or full enough understanding — of why an LLM generates some token? In one sense, we have that already, because we can mechanistically trace through the calculations involved. But we don’t know what those calculations mean. Saying that Grok called itself “MechaHitler” because these billion weights multiplied in this way doesn’t tell us why Grok did it. What we would need for alignment purposes is a more human-like and less mechanical sense of understanding: a full understanding of motive.

To see why a full understanding of motive is a foolish thing to ask for, imagine asking it about a human. Suppose you were hiring a nanny or electing a president and you wanted to be sure that they were going to act in your interests4. Humans sometimes do very surprising things out of nowhere, after all. Would it be sensible to ask for a full understanding of that person’s mind, in order to reassure yourself that they would act in the way you wanted? Of course not.

It’s meaningless to even talk about a “full understanding” in this sense, because the mind is not a mechanism that operates via clean, understandable abstractions. It is a morass of electric and chemical impulses from which a “self” bubbles up5. There are no motives of the kind you’re looking for! Motives bottom out early on, and tracing the causal chain beyond that can only be done mechanistically: i.e. unhelpfully, for the same reason that explanations based on model weights are unhelpful.

Why mechanistic interpretability is doomed

Couldn’t a sufficiently detailed mechanistic explanation give us the confidence we need? The best we’ve got along those lines right now are the tools of “mechanistic interpretability”: features, neurons, probes, and circuits. You observe the model doing something, see which parts of its “brain” light up6, and correlate those with some pattern of behavior. If you can then induce that pattern by artificially boosting that part of the “brain”, you can claim victory. Even assuming total success, this program cannot deliver us the kind of understanding we’re looking for.

First, we label patterns based on behavior we observe, but the main misalignment case we’re worried about — the LLM suddenly performing some shocking harmful action — is definitionally something we aren’t going to observe before it happens. We can’t identify a feature without first eliciting its behavior7, and we can only elicit a small subset of potential model bad behavior. There will always be many untracked failure modes.

Second, the labels we apply to patterns are our guesses, and may be wrong. The philosopher Kripke famously argued that, until you run into the relevant case, there’s no meaningful difference between the “addition” rule and the “quaddition” rule (a version of addition where if either number is greater than 57 the answer is always 5). Likewise, the LLM feature we call “kindness” might be “kindness unless the year is 2030”, or “kindness unless the LLM is in a position to cause mass casualties”, and so on. Those features are completely indistinguishable8 from our perspective.

Third, even an exhaustive well-labeled map of features and patterns would not give us certainty that a model could not go rogue. The full combination of features involved in any model action would be far, far too complex to interpret. For instance, if a model has “evil” lit up, is it because it’s trying to avoid evil, or trying to cause it, or trying to combat it, or is worried about some hypothetical evil action, or is anticipating that a user might make the judgement? We would have many, many billions of questions like that to answer per-token. Far too many for a human to comprehend9, certainly.

Could some hypothetical, radically different kind of mechanistic interpretability somehow predict all possible actions a model might take in advance and rule out actions like “kill all humans”? I think this at least could be semantically coherent, but it runs into the problem above. Models can accept a near-infinite array of inputs and give a near-infinite array of outputs. This definitely cannot be comprehended by a human, only by another model, which itself would have to be checked by another model, and so on.

Conclusion

If you think solving LLM alignment is possible, I would love to read your description of what it would even look like for us to understand LLMs well enough to be sure they’re safe. I would love to know if you think humans are similarly understandable in principle (and if not, what makes LLMs different). It seems to me that if we think clearly about the topic, we don’t even know what it would mean to be confident that we have aligned an LLM properly10, because “motive” simply doesn’t exist at the level of detail we’d need.

Of course, we have mitigations in place. Chain-of-thought monitoring is surprisingly helpful for a mechanism that appeared by accident, so long as we never train on reasoning tokens themselves. We can sandbox models and put humans-in-the-loop and watch for feature activations and so on. But it’s been well understood since the early 2000s that these are insufficient11 to detect or control a superintelligence. Whether you think mitigations are enough depends on whether you take superintelligence seriously.

Mechanistic interpretability is still a useful field. Extracting features can help us train models that do less reward-hacking and are more helpful under ordinary circumstances. There’s just no way it will ever solve the problem of LLM agents going rogue and causing massive harm, because the kind of understanding we’d need to prevent that is impossible in principle.


  1. It’s relevant to note that humans sometimes do this too. From Vaneigem: “One fine morning, the faithful lackey, who has hitherto identified completely with his master, leaps on his oppressor and slits his throat.”

    ↩
  2. For instance, the goal “eliminate suffering” is best satisfied by destroying all humans, the goal “maximise everyone’s happiness” is best satisfied by hooking everyone up to a fentanyl IV, and so on. It’s also very difficult to find a way to translate concepts like “happiness” and “well-being” into a formal goal, and if you get it wrong, the difference between the concept and your formalization is likely to lead to dire consequences.

    ↩
  3. Yes, I know LLMs are partially trained in this way, but being RLVRed on millions of different rewards does not produce a coherent goal. There’s no way to formalize in advance the utility function that RLVR instils in the model, and no way even to reliably predict how it will interact with the goals and personas that emerge from the base model.

    ↩
  4. Of course, for humans you can rely on institutions, social proof, and so on. This doesn’t work for superintelligent LLMs because they (a) arrive fully-formed with no social proof and (b) are smart enough to be much more dangerous than a single rogue human. (Incidentally, the LLMs I asked to review this post were obsessed with this point, and wanted me to elevate it into the main thrust of the post).

    ↩
  5. Perhaps as an epiphenomenon. If you’re interested in this idea and want to see it taken further, I recommend (but do not endorse the ideas in) Blindsight.

    ↩
  6. Which parts of the model’s internal state have high values, for instance.

    ↩
  7. That doesn’t mean we have to deliberately elicit one feature at a time — dictionary learning works by just running arbitrary content through the model and seeing what lights up — but it does mean that we have to actually trigger the behavior in order to see it.

    ↩
  8. If you’re thinking “well, but isn’t the simple feature more likely via Occam’s Razor”, I recommend browsing through NeuronPersonas (the linked feature is “Nervous Person Waiting To Be Let Go Who Escalates Ammonia Solution Concentrations”).

    ↩
  9. I’ve heard people punt on this question by saying “well, of course I couldn’t use a fully-mapped LLM brain to figure out if it’s dangerous, but another smart model could”. This is not a satisfying answer because you’d have to also ensure that your warden model was behaving (with a third model, perhaps?)

    ↩
  10. Of course we can articulate what alignment looks like: the model never does anything bad. We just can’t articulate what it would look like to know the model was aligned.

    ↩
  11. For more on that, see my post on superpersuasion: the model will simply outwit or bribe any human in the loop. For a credible source who understands modern mechanistic interpretability, see Neel Nanda, who I read as broadly agreeing with me.

    ↩

Fast and slow ways to improve your reputation

Published: 1 week ago

To get a good reputation in tech companies, you need to work on important projects. However, you need a good reputation first in order to get assigned important projects. Doesn’t that make it impossible to get started? I get a lot of emails from engineers who are struggling with this problem. They go like this:

I work with a strong senior engineer. I feel like my manager structures work so that strong engineer always gets the visible work, and the more they do, the more opportunities they get, while I sit on the sidelines. My manager agrees with me that it’s time for me to start leading work myself, but every time a new project appears it always goes to the strong engineer. What do I do?

This is a good case study for what I think of as “tech company theory of mind”: understanding the actual incentives that motivate decisions in tech companies, instead of the formal process. According to the formal process, projects should probably be assigned round-robin to whoever has capacity and isn’t currently working on one. But (as my emails complain) this is almost never how it works in practice.

A vicious cycle

Managers care about giving their employees chances to build a reputation, but they care more about developing their own reputation as someone who can deliver. High-profile projects are the best opportunity for new people to step forward and get known, but blowing up a project1 like that is the easiest way for a manager to tank their own reputation. They will thus typically hand these projects to someone they know can deliver, while simultaneously promising (including to themselves) that next time they’ll take the risk of letting another person lead it.

Of course it’s a vicious cycle. The more you rely on one person, the more reliable they become and the less reliable their colleagues become, since they aren’t getting the relevant experience. It’s not very sustainable. However, the average manager tenure in big tech is only a couple of years2. Given that, it’s rational for individual managers to take the long-term risk in exchange for mitigating the short-term risks of project failure.

The slow way to improve your reputation

So what can you do about it? I wrote about the classic approach years ago in Ratchet effects determine engineer reputation at large companies:

Note that this plan does not involve convincing3 your manager that you need projects for your career development, or that it’s unfair for you to be overlooked, or that the formal process would mean you should get to lead projects. You are not going to be able to change your manager’s incentives, but you may be able to position yourself so that your manager believes their incentives line up with yours.

The problem with this plan is that it’s slow. It takes months or even years to piece together a reputation like this. That’s slow enough for bad luck to intervene by handing you a failure you can’t avoid, or having your manager leave, or for the fundamental nature of software engineering to change. What can you do that’s faster?

Fast ways to improve your reputation

The fast path to getting assigned interesting work involves taking risks. This is all dangerous advice. Follow it at your own peril.

One way is to build a relationship with your skip-level. If your manager’s manager thinks you’re a stone-cold killer, you are basically guaranteed to get assigned interesting projects. They will straight-up tell your manager “why not put X on this?”, and your manager will rationally decide (a) that it’s in their best interests to do it, and (b) that if you screw it up, it won’t be their responsibility.

But it’s not so easy to build a relationship like this. Very senior managers are skilled political operators4 who are good at identifying when people are trying to persuade them. If they think you’re coming on too strong, that will hurt you far more than it helps. Unfortunately, the most reliable technique for building a relationship with your skip-level is to just be reliably useful to them over a long period of time, which puts us back to the slow way.

Another fast way is to make side bets. I wrote about that here, but the idea is simple: figure out and implement your own projects. Work that you decide to do is work that doesn’t have to be assigned to you, so if you independently identify something important that needs doing, then do it, you’ve manufactured your own project out of thin air. I think every senior engineer should be trying to do this all the time.

The risk of making side bets is that if they don’t work, or turn out to be less important than you think, you’ve entirely wasted your time. Worse, many managers will get annoyed at engineers who try this, because it can make managers look in meetings like they don’t know what their team is working on.

Finally, the best fast way is to impress your engineer colleagues. This only really works on a team with a healthy culture, but when it works it’s very smooth. Managers are slow to form opinions because they’re not close enough to the engineering coalface to know who’s doing quality work5. Engineers are informed enough to form opinions quickly. At least I am: it only takes a few “oh, you saw something I didn’t” moments for me to decide someone’s good.

On a healthy team those engineers will tell their manager that, who will decide that you must be good, and will give you important work far earlier than if you’d had to prove yourself from scratch. On a kind of crappy team, engineers might not be good enough to recognize strong engineers, or they might not communicate freely enough to tell your manager about it. On a really unhealthy team, engineers will actively trash-talk competent colleagues because they (correctly) see them as the biggest threats.

Conclusion

If you’re on a team where all the interesting work is going to someone else, you have a reputation problem. It’s probably not personal: your manager is simply incentivized to give new work to known reliable engineers, which is a vicious cycle that leaves you out in the cold. Fixing that can be a safe slow process or a risky fast process.

Either way, I don’t recommend simply trying to convince your manager in 1:1s that it’s unfair to leave you out of projects. Tech companies are not supposed to be fair, they are supposed to make money. You’re better off finding a way to make it look like it’s in your manager’s best interests to assign you that work: either by appealing to your skip-level, finding projects of your own, or building a reputation with engineers your manager already trusts.


  1. One reason some people find this point tricky to grasp is that they underrate just how hard it is to ship anything. Projects fail all the time. No manager can afford to be sanguine about the risks.

    ↩
  2. I linked the first crappy source I could find, but my main source for this is just noticing how long the managers in my workplaces stick around.

    ↩
  3. You don’t even necessarily have to tell your manager you’re looking for bigger projects, though I think you probably should.

    ↩
  4. Almost certainly more skilled than you, due to selection effects and the fact that they get way more practice.

    ↩
  5. They typically have to rely on results, which is a slow proxy for technical ability.

    ↩

Elegance and intelligence are anticorrelated

Published: 2 weeks ago

Elegance and intelligence can have a surprisingly negative correlation. Intelligent people sometimes produce inelegant solutions because they’re capable of rapidly brute-forcing problems. If I had to remember a hundred names, I would spend time coming up with clever mnemonics. John von Neumann would probably just remember them.

There’s a famous von Neumann story where he was asked how far a fly must travel if it kept flying between two cyclists who were approaching each other at some fixed speed. The trick to the puzzle was to notice that the cyclists would take an hour to meet, so the fly must be travelling for an hour: given the fly’s speed, it’s then easy to calculate the total distance. When von Neumann solved the puzzle instantly, the questioner assumed he’d heard the trick before, but in fact he had just summed the infinite series. If you can do that instantly in your head, why bother with the clever trick?

For software engineers, the most important kind of raw intelligence is often the size of your working memory: how many moving pieces you can hold in your head at a given time. Software design involves finding elegant ways to reduce that number of moving pieces, typically by abstracting them away or moving them behind some interface. It can be frustrating1 to work with engineers with a giant working memory, because they don’t care as much about decomposing the problem into some elegant design — they don’t need to.

This is why some2 really good engineers are surprisingly okay with working in a sloppy codebase: because they can see the whole thing clearly at a glance. Since they never get lost or confused, the level of mess is acceptable to them. When needed, they will effortlessly visualize a ten or twelve step execution flow to see what needs changing or where the problem is.

Something like this might be going on with AI-generated mathematical proofs, which read as unacceptably verbose and unfocused in the eyes of human mathematicians. However, for a sufficiently intelligent LLM, a series of a few hundred logical steps is not substantially more difficult to parse than a series of ten. They are happy to just “sit down and calculate” indefinitely3. I’ve written about the danger of AI proofs solving conjectures without generating new ones. If AI proofs are inherently less elegant than human proofs, that compounds that danger, since noticing (or inventing) elegant abstractions is often the fuel for generating new conjectures.

Humans have had to become very good at inventing clever tricks, because we aren’t built for rationality. Aside from having a limited working memory, our systems of logical thought are jury-rigged on top of a seething morass of irrational urges, inspirations, and blind guessing. As it turns out, this has been an astonishingly good way to develop powerful abstractions that help us understand the universe.

Could LLMs be smart enough to avoid needing to come up with truly creative insights? This is probably too comforting a thought to be true. Smarter minds may still need to come up with new abstractions, just for harder problems. John von Neumann4 himself invented a ton of new mathematics despite his willingness to calculate. However, it’s possible that humans are inherently better at this creative process than machines — out of necessity, if nothing else. Since we humans are spending the late 2020s thinking hard about our competitive advantages, it’s interesting to consider that our relative stupidity might be one of them.


  1. Likewise, it can be frustrating to work with engineers who struggle to understand code you consider simple, and demand levels of abstraction that seem unnecessarily fiddly to you.

    ↩
  2. This isn’t universal — some good engineers demand neatness, even to the point of compulsion.

    ↩
  3. In 2025, this wasn’t the case: models were limited by the size of their context window and could not effectively proceed after compaction. One of the under-discussed themes of 2026 is that compaction has all of a sudden gotten really good.

    ↩
  4. His opposite might be Alexander Grothendieck, who famously attributed his mathematical creativity to his “clumsy, even oafish” relative lack of talent.

    ↩

You can just ask AI to do things

Published: 2 weeks ago

One of the most important skills in working with AI is agency: being willing to try new and ambitious things. This is true for what you build, but it’s also true for how you build. AI models are improving so quickly that most of us are bottlenecked1 on noticing that AI agents can help automate particular tasks. Here are some examples of that from my daily work.

Asking the agent to run my dev server. Agents are very good at fixing weird dev environment issues because they work fast, have infinite patience, and have a huge breadth of knowledge. I almost never run the bash commands to start my dev server anymore.

Asking the agent to make requests to my dev server. Part of why I don’t run my dev server manually is that I don’t make requests to it manually either. Instead I’ll say “okay, now start the dev server and run through the happy paths with curl”. The relatively manual process of assembling a set of curl requests and validating the output can now be entirely automated2.

Asking the agent to watch as I make a production change. Every time I do a deploy or flip feature flags, I ask an agent to poll metrics and logs before and after the change. Agents can ingest more logs than I can and are much more patient than me (for instance, I routinely ask for an hourly poll over the rest of the day, which I would not do for most changes on my own).

Asking the agent to get a second opinion from other models. My daily driver is Claude Opus 5.5, which is a good model, but it’s not strictly better than GPT-6-Astra or Gemini Argon3. After I’ve come up with a code change, I typically will say4 “please open subagents to get Astra and Argon’s opinion”. This is made easier by the fact that GitHub Copilot5 has all the top models built in, but I suspect it’d be straightforward enough to ask Claude Code to run a headless Codex session if you’ve got subscriptions to both.

Asking the agent to do a pre-work pass through all my unread messages, logs, and so on. This is one of the most useful things I do, since I work in Australia and my American colleagues start hours before I wake up. I have a scheduled job at 6am every day for an agent to comb through unread messages, identify ones that are asking me questions or have problems I should look at, and do preliminary research (e.g. looking up relevant log lines). That way I can start my workday by scanning that report, which is a big improvement over having to collate everything myself6.

Asking the agent to improve itself. One blocker to a lot of these flows is the pain of setting up the right logs and metrics and Slack MCP servers7, or writing the skills, and so on. But in fact the agent can do all of this itself! Just as it can solve weird problems with your dev server, it can solve weird problems with its own setup. You just have to generate API keys and paste them in the right spots.

Asking the agent to manage its own sessions. If you use a desktop agent tool like GitHub Copilot (or the ChatGPT app, or Claude Code desktop, etc), you will rapidly end up with a spiderweb of sessions and subsessions. It can be tough to identify what are the threads worth picking up. Fortunately, the agent can do this for you as well. I routinely ask it to clear away sessions that haven’t had activity in the last 24 hours, or to catalog my open sessions and suggest ones that can be archived, and so on.

I don’t ask the agent to do everything. I write my own messages and reports (barring some appendices), I make my own design decisions, and I review code myself. This is partly because I think I’m better than models at some of these tasks, and partly because I’m responsible for some of these tasks, so I ought to make the decisions myself. I decide what to work on, and I tend to be ruthless with agent suggestions: of a suggested list of twenty tasks, I’ll often pick zero or one.

However, I do find myself asking the agent to do more and more for me. Often the realization strikes me as obvious: I’ll be doing some mildly tedious task for the hundredth time and think8 “oh wait, I could just get a model to do this for me”, then I’ll never do the task by hand again.


  1. As I’ve said before, I think that model progress could stall out today and we’d still see huge improvements for at least a year as we learn how to use the models we’ve got more effectively.

    ↩
  2. Why not just have integration tests? Well, often you don’t want to run the same set of operations every time, or you want to jimmy your dev server in order to test some failure mode (e.g. replacing your Redis client with a deliberately broken Redis client).

    ↩
  3. I haven’t tried Carbon yet.

    ↩
  4. I will then either scan the top-line feedback from those models myself or let my main agent session incorporate the feedback (depending on how risky the change is).

    ↩
  5. I work on GitHub Copilot. If you think I have a conflict of interest here, substitute your preferred multi-model agentic coding tool.

    ↩
  6. I do still read all my unread messages manually. Once I get confident enough in this pre-work report stuff I might stop doing that — it’s a lot of messages.

    ↩
  7. Some people might not trust the models with Slack or log data, which is fair enough. But if you do, a lot of things get a lot easier.

    ↩
  8. Or I’ll see someone else getting an agent to do it and realize I could just do the same. I hope one or two of the points in this post can help other people come to that realization.

    ↩

Getting good at AI takes time and practice

Published: 2 weeks ago

Many people think1 that getting “good at AI” is trivial. Sure, with some early models there were tricks you had to learn,2 but current models don’t need them. Even if there are different tricks3 that work on current models, the next generation will render them obsolete, so why bother? Just tell the model what you want it to do.

This take is particularly popular with the anti-AI crowd, who scoff4 at the idea that AI-reluctant people are being left behind, or that it might be irresponsible to advise other engineers to avoid AI use entirely. According to them, if AI does ever become capable enough to be worth using, they’ll be able to start using it with no learning curve. Is that right?

No. Like most things, getting good at using AI isn’t just about clever tricks. It requires developing long-term skills5, which takes time and practice.

Supplying the right context

One failure mode I’ve seen with people who are new to AI is expecting it to read their mind: for instance, asking it to “solve my issue” without ever saying what the issue is, or asking it about some Slack-related problem without actually connecting your agent to Slack. Agents are flexible and will try their absolute hardest to guess what problem you’re facing and how to solve it, but the guesses will be largely wrong. Skilled AI users will pick up on the fact that the agent is missing key context and backtrack.

Skilled AI users will also reflexively include why they want to achieve their current goal, so that the agent has enough context to make decisions. This is often non-trivial: most of us know what we want to do but have to take a second to think about the broader reasons behind it.

Knowing what the model can and can’t do

AI capabilities are weird: they are very good at some tasks and very bad at others, and it’s hard to predict which task falls into which category. For instance, I know that I can ask an agent to come up with new architectural ideas for how to structure a service, but that I shouldn’t ask it to come up with new features that the service can offer. Worse still, there is a third category6 of tasks that AI models are bad at but can be prompted into being good: for instance, writing PR descriptions.

Of course, this changes with new models, but less than you’d think. In general, new models get much better at the tasks the old models were already good at, and a little better at the tasks the old models sucked at. So developing a sense of what AI can and can’t do is a surprisingly durable skill.

Really internalizing what the model can do is trickier than it sounds. For instance, I initially struggled to set up MCP servers for GitHub Copilot before realizing7 I could just ask Copilot to install its own MCP servers. I now reflexively ask AI agents to do local testing of changes — standing up servers, hammering them with curls, running through variations and edge cases — but it took me a while to realize I could ask for that. I have only just started scheduling a job for 6am my time for an agent to go through messages that have come in from different timezones and do some preliminary investigation. What other capabilities8 am I leaving on the table?

Knowing what mistakes the models make

Reviewing AI-generated code is a substantially different skillset from reviewing human-written code. There are whole categories of bugs — off-by-one errors, for instance — that human-written code is prone to but AI-generated code is not. Similarly, there are mistakes that are rare in human-written code but are very common in AI-generated code. I’ve written about how these tend to be mistakes of misalignment: over-engineering some areas that humans would know aren’t important, or trading off important requirements in order to satisfy made-up ones, and so on.

Reviewers used to human-written code are often dazzled by the superficial fluency of AI-generated code. It’s always exhaustively commented and tested and uses sophisticated language features. If a human programmer produced code like this, you’d be inclined to trust their judgment that a mutex is required in this case — but with an AI programmer, you ought to be very suspicious about new mutexes, which are often introduced to satisfy completely insignificant edge cases.

Rapidly skim-reading AI slop

This skill is kind of silly, but it’s so practically important I have to include it. AI models produce a lot of useful output, but it’s often lost in a thick forest of verbiage. Once you’ve read enough of it, you can sort of just let your eyes flow over the phrasing until you get to the specific claims and evidence. If you’re not used to this, you will waste a lot of time and emotional energy trying to cut through the foliage.

Will these skills be made obsolete too?

It’s possible that these skills are also temporary. Maybe in the future the agent will just do what we want perfectly, freeing us from the need to actually read its output. Maybe model tooling will get good enough to automatically supply the right context, and the models will get good enough to be able to do everything and make no mistakes. Maybe! But that would require the models to get so good that humans aren’t needed at all.

Don’t be a doomer. Like chess, software’s centaur age — the period where a human-machine pairing can beat individual humans or machines — may last decades. Developing skills for the centaur age is still worthwhile, just like it was worthwhile to learn Angular or React even though it seemed likely that those frameworks would be obsolete9 in a decade.

Conclusion

I’ve left a lot of skills out: knowing when to abandon or steer an agent session, how to break work up between agents, when to trust AI claims and when to verify, how to minimize costs by using smaller models, and so on. On top of all that, even though it’s not durably useful to stay up to date with the current set of tricks (plus knowing which model is the best for which tasks), it’s still very useful in the short-term. Keeping up without getting lost is a skill in its own right.

It shouldn’t be surprising that working with AI involves actual skills. It’s like working with a really weird person: a savant with mad skills in some areas and huge gaps in others, a prolific but inexpert communicator, a workaholic with no long-term memory, and so on. If you were a manager and had someone like that as your employee, you could likely get a lot of value out of them, but it would take time10 to figure out how.

If you’re deliberately avoiding using AI, you are likely being left behind by the people who aren’t. If you’re advising other people to avoid AI completely, you are doing them no favors. I do think it’s a mistake to go fully into AI, because LLMs reward expertise, which is best gained by hand. However, if you never practice using AI, you are never going to get good at it.


  1. I see it all the time, most recently here and here (in fairness: that post does think there’s skill involved, just not durable skill).

    ↩
  2. Like asking it to think step-by-step or saying “you are a skilled software engineer” at the start of the prompt.

    ↩
  3. Like offering moral support.

    ↩
  4. In fact, they often believe that AI users are literally damaging their brains. As I’ve said a few times, I think this idea is mistaken.

    ↩
  5. Incidentally, the reuse of the word “skills” to refer to “job-specific dynamically-loaded prompts” has made this post a nightmare to write.

    ↩
  6. There’s not even consensus on which tasks are in which category. Many people think LLMs are great at writing prompts for other LLMs, but I think they’re terrible (overly prescriptive, etc). This is obscured by the fact that LLMs can manage swarms much more efficiently than humans, but I think most people agree that having a single subagent is worse than just doing it on the main thread.

    ↩
  7. Shout out to my brother, who told me to stop being stupid and just ask the robot to do it.

    ↩
  8. I could list like six other things here (e.g. asking agent sessions to get second opinions from the latest Gemini/OpenAI models). If you want me to write a post on that, email me.

    ↩
  9. As it turned out, those people were wrong: React was pretty good, and the end of ZIRP meant that the framework treadmill stopped, so React skills continue to be useful today.

    ↩
  10. In no small part because you can’t trust their own claims about their abilities.

    ↩

Don't anthropomorphize big tech companies

Published: 2 weeks ago

Bryan Cantrill has a great line from a talk where he cautions against anthropomorphizing1 Oracle CEO Larry Ellison. I think it’s also a mistake to treat any tech company like a person. Here’s the full quote:

You need to think of Larry Ellison the way you think of a lawnmower. You don’t anthropomorphize your lawnmower, the lawnmower just mows the lawn, you stick your hand in there and it’ll chop it off, the end. You don’t think ‘oh, the lawnmower hates me’ — lawnmower doesn’t give a shit about you, lawnmower can’t hate you. Don’t anthropomorphize the lawnmower. Don’t fall into that trap about Oracle.

Companies are machines, not persons

Here are some examples of anthropomorphizing companies:

All of these are mistakes. Your relationship to the tech company that employs you is not like a relationship with a person. It’s more like your relationship with your car2. If you drive poorly or fail to change your oil, your car may stop working or even kill you, but it doesn’t love or hate you. It has no sense of fairness. It’s simply a dangerous, useful machine: useful enough to be worth getting into despite the risks. Anthropomorphizing it makes it harder to avoid those risks3.

Why is it so hard to avoid this trap? First, humans anthropomorphize everything by default. Second, whenever you’re interacting with the company, you’re interacting with a person: your manager, your colleague, someone in HR, and so on. Third, when you’re in the power of some entity, it’s psychologically comforting to think of it like another human. This is the same principle that caused early humans to attribute lightning to the power of Zeus, because Zeus (unlike electrical imbalances in storm clouds) can be placated with prayer and sacrifice.

Disproportionate efforts and rewards

Relationships with machines are very different from relationships with people. The biggest difference is that machines do not respect effort. If you put a lot of work into doing a favor for a friend, your friend will appreciate it even if the favor itself is not a big deal. Conversely, if you help somebody out at trivial cost to yourself, that help will be relatively unappreciated. But a car doesn’t care how much effort you put into maintaining it. If you spend hours replacing a car’s engine, but the brake line is damaged, the car won’t remain functional out of respect for your effort on the engine: instead, the brakes will fail, killing you.

Tech companies work like this. Everyone who’s worked at one for long enough knows that it’s very hard to predict what work will be high-impact. The project you slaved over for months will often get a “nice, now what’s next” reaction, while the tool you built in fifteen minutes (or the question you answered in a Slack channel) will sometimes get wild praise and recognition. This can drive engineers a little mad, because they’re anthropomorphizing their tech company, and a person who behaved like this would be dangerously unstable. But if you treat your company like a machine, this shouldn’t be surprising at all.

It’s hard to predict high-impact work, but it’s not impossible. The best way to operate at a big tech company — as I’ve said again and again — is to try and develop this skill, and to spend most of your time looking for the low-effort high-reward wins. It’s hard to do that if you’re secretly imagining your company as a person.

Anthropomorphism is a dangerous shorthand

A natural objection here is to point out that tech companies (unlike cars) are composed of people who might indeed owe you, hate you, love you, and so on. According to this view, when people say “my company hates me”, they aren’t making the mistake of anthropomorphizing a corporation, they’re using shorthand to say “my boss and skip-level hate me”. I think this is still a dangerously sloppy way to think.

In my experience, engineers who think they’re hated are often not. Managers in large tech companies do hold grudges, but (particularly the higher up you get) are tolerably cold-blooded. You don’t get to senior director or VP by needlessly throwing away useful tools. I can recall a few cases4 where engineers told me they were hated, but I later found out5 that managers considered them dangerous or unreliable: loose cannons whose usefulness didn’t outweigh their tendency to go off the rails and cause damage. From the perspective of the engineer being forced out of the company, it feels like you’re being run out of town by people who hate you. But if you want to avoid being run out of town, it’s useful to recognize when you’re being treated as a defective tool.

It’s also useful to keep in mind the difference between “my manager hates me” and “my company hates me”, because managers are often temporary. You can sometimes just wait out a bad relationship with your manager. You’ll have a slightly uphill battle with the next one — since the handoff won’t be positive — but it’s certainly possible to get back on track. If you can figure out why your manager hates you, you might also be able to fix it (or at least mitigate6 it).

Don’t go too far in the other direction

Engineers who’ve learned not to anthropomorphize tech companies sometimes go too far in the other direction, by treating companies as a computer program. This is the wrong kind of machine: tech companies aren’t people, but they aren’t programs either. They operate on incentives and illegible interpersonal relationships, not on consistent logical steps.

The classic example of this is the engineer who reads the company handbook cover-to-cover and makes sure they follow all the rules. When they’re looking to be promoted, they take the role guidelines and make sure they’re following them point-by-point. They take what they’re told very literally: when the company says “X is our top priority”, they internalize that.

The problem with this is that handbooks, guidelines and internal communications are the legible superstructure of a massive illegible web of dependencies that make up the actual operations of any company. That superstructure will not cover the real criteria for promotions, or the rules that are designed to be broken. The “top priority” of the superstructure can rapidly shift, leaving literal-minded engineers confused and disheartened.

Conclusion

It’s understandable to feel ill-treated by a company, or to harbor resentment — particularly since there are actual humans at the company who are involved in that treatment of you. But companies themselves don’t hold grudges, even as they force out people who they’re incentivized to force out7. It can even be a mistake to anthropomorphize very senior managers, whose work personas are more identified with the machine the higher up you go8. I suppose at the top you have Larry Ellison, as Bryan Cantrill says, who is better modeled as a lawnmower than as a human being.

No relationship with an individual person at your company will save you from being careless with the machine: it will chew you up and spit you out. You need to learn how to drive the car. This is scary, because it means that sometimes you will just get punished for no reason. But it’s also good news, because it means that you can get disproportionate rewards for relatively little effort, so long as you make the right decisions.


  1. Treating as a human.

    ↩
  2. I like this example better than Cantrill’s lawnmower because cars are more central to our lives, like jobs are, and are also far more dangerous.

    ↩
  3. For instance, if you’re prone to thinking “my car loves me, it wouldn’t spin out when I take this hard turn on gravel”, you are more likely to crash.

    ↩
  4. Though certainly not all. Grudges do exist.

    ↩
  5. Of course, this is my interpretation of the situation, and could be wrong.

    ↩
  6. There are a range of techniques here, ranging from “do all your paperwork defensively” to “find some out-of-the-way project” to “ingratiate yourself with your skip-level”.

    ↩
  7. For instance, people who make their managers look bad, or who publicly point out the inevitable inaccuracies in legible reports, or who campaign against the current big push the company is making.

    ↩
  8. I say “work personas” because these people often have a rich personal life that is largely firewalled off from their work selves. For more on how managers come to identify with the rules of the organization, I recommend Robert Jackall’s Moral Mazes, a book that has informed much of my thinking and that I will some day write a long-form review of.

    ↩

Software is slow because of bad design, not slow languages

Published: 3 weeks ago

Many people are saying that AI will make software faster by rewriting it in faster languages, but this isn’t generally true. Most programs cannot be meaningfully sped up by rewriting them in C or Rust.

How can this be true? Some languages are orders-of-magnitude faster than others: for instance, C can be fifty times faster than Python. Won’t rewriting my Python program in C thus make it fifty times faster? No, it won’t. Software performance is usually dominated by I/O, not the speed of the language. Where language speed matters, most slow languages already have popular libraries that allow them to unlock C-like speed. In general, performance is a matter of design, not of language choice.

Most real programs are I/O-bound

Consider a simple CRUD website with a database. For any given request, 50% of the request time1 might be spent querying the database: to fetch the current user, the record being asked for, any relevant user memberships or settings, and so on. Rewriting that website in C can only speed up that other 50%, which puts a hard ceiling on the improvements you can make2. At best, you’ll make requests twice as fast (probably closer to 1.5x in practice). That’s not bad, but it’s nowhere near an order-of-magnitude speedup.

In other words, most real programs are “I/O-bound”: they spend most of their time waiting for data to be input or output somewhere, as opposed to “CPU-bound” programs that spend most of their time actively doing things. I/O-bound programs don’t just have to rely on a database. Often programs have to wait on some third-party API, or on writing or reading data to disk. You could speed the code in curl up by 100x and you probably wouldn’t even notice, because curl spends all of its time waiting on the network.

Slow languages already delegate work to fast languages

What about work that is obviously not I/O-bound? For instance, wikis have to turn stored markdown into renderable HTML3. Wouldn’t rewriting that in a faster language cause a massive speedup? It would! That’s why applications that do that use libraries like cmark-gfm that call out to fast languages for markdown rendering. In general, most slow languages can write very fast programs by invoking this kind of library. Python is famously a slow language, but it’s a competitive choice for CPU-bound workloads like machine learning and mathematics, because it has a healthy set of libraries that let it offload these workloads to fast C code. If a Python program spends 80% of its time doing matrix multiplications on a GPU, you are very unlikely to be able to speed it up by rewriting it in C, because those matrix multiplications are already happening in tightly-optimized C or assembly code.

Of course, some programs do in fact do a lot of CPU-bound work in slow languages. If a program has not had much engineering attention, there will probably be a lot of low-hanging fruit. But these programs are often unimportant: if they were important, someone would have gone in and optimized them already, before AI made it (relatively) easy. That doesn’t mean it’s impossible to find a useful program to rewrite. Actual Computer recently rewrote tiktoken in assembly, providing a significant4 speedup. However, you’re not going to revolutionize some field of computing like this. Even fast tokenization is only useful on the margins, because time spent in tokenization is a fraction of the time spent in inference.

Speeding up software typically involves a redesign

Despite all this, I think most software is far slower than it could be. I’m optimistic about the potential (with or without AI) to significantly speed up commonly-used software. But I think most of these speedups will come from redesigning the program, not rewriting it in a faster language.

In a 2018 post, Bryan Cantrill described trying to rewrite a C program into Rust. It was difficult because the carefully-optimized design of the C program did not play well with the Rust borrow checker. Giving up, he simply wrote the program in Rust in the naive way, expecting a 20% slowdown or worse. Instead, it was 30% faster. The reasons boil down to Rust’s internal preference for a B-tree over a binary search tree, which happens to be a more cache-efficient data structure. So even in a largely CPU-bound workload, in the hands of someone very skilled at writing fast C, performance is dominated by design, not by language speed.

This matches my own experience in higher-level languages. When I think of the significant speedups I’ve managed, they’re almost exclusively redesigns of the software to do less work:

All of these strategies are completely unrelated to how fast the language is. In fact, writing in a slow higher-level language can make it much easier to optimize the code, because you can see at a glance what the program is doing. If (for some reason) I had first rewritten the web server in assembly, I would have a much harder time noticing the N+1 query, or the fact that we could move an API call into a job, and so on.

Conclusion

Right now everyone is asking their AI agents to rewrite programs in Rust or C or assembly. This is fun, but it’s not a serious attempt at optimization. The set of programs that can be meaningfully sped up by this kind of rewrite is very narrow.

If you want to make everything faster with AI — and you should! — you ought instead to be asking your agent to profile programs, identify hotspots, and suggest ways to redesign what the program does. Occasionally you may run into a hotspot that is truly CPU-bound and cannot be refactored to do less work. In these rare cases, rewriting that section in a faster language will help. But simply rewriting from the start will be far less successful than most people imagine.

There are many good reasons to rewrite software in a different language: portability, efficiency, maintainability, and so on. But in terms of raw speed, you’re better off focusing on the program’s design.


  1. This might seem ridiculously high (if you typically work with slow languages or CPU-bound workloads), or ridiculously low (if you don’t). In my experience it’s at least in the ballpark for interpreted languages.

    ↩
  2. This is formally called Amdahl’s law.

    ↩
  3. Why not just store the HTML? You can, but sometimes the content of the HTML differs per-user (and even if you store the HTML you have to convert it at least once).

    ↩
  4. They claim 4-23x faster than tiktoken and it was indeed ~5x faster on my laptop — though arguably this speedup comes from a redesign to avoid the dependency on regex, not on any intrinsic slowness of Rust with Python bindings.

    ↩

Laypeople support technical fields for technology, not art

Published: 3 weeks ago

Some people think that LLMs should not be used in technical fields like programming or mathematics, because those fields are actually art. True or not, this kind of argument is not going to be persuasive to the general population. The argument goes something1 like this:

It doesn’t matter how effective LLMs are at technical fields like programming or mathematics, because one of the essential values of those fields is that they’re art. While it looks to laypeople like these fields exist to solve practical problems, what they’re actually for is to produce works of beauty, or to express something distinctively human, or to spend time contemplating the infinite. Simply solving the problems misses the point in the same way that building an infinite poem generator would miss the point of poetry.

I agree that programming or mathematics can be beautiful. I remember being mildly awestruck at learning epsilon-delta proofs, and I have written a lot about the kind of software I think is elegant. Since there’s no clear definition of art or of aesthetics in general, it’s plausible to me that almost everything could have an artistic dimension to it.

All of this is compelling to software engineers, many of whom (like me) find some programs beautiful and are flattered to think of themselves as artists. But I suspect it’s spectacularly uncompelling to onlookers, because it undermines the implicit reasons that they have for supporting technical fields. Many people who are not programmers or mathematicians think of those fields like this:

In other words, regular people3 think mathematicians (and to a lesser extent programmers) are valuable because they think science is valuable, and they think science is valuable because they think technology is valuable. They are willing to accept that technical fields can be art only insofar as that eventually helps researchers have the kind of creative insights that advance science: as Rikab sarcastically puts it, that advance the knowledge frontier.

If you go to those non-technical people and you say “LLMs can accelerate problem-solving in these fields, but I’m strongly against using them because the real point is to produce great art”, they will be very unhappy. They might reasonably feel cheated, in the same way as if they hired someone to renovate their kitchen who insisted in doing it all with hand tools in order to experience “the joy of creation”. This argument — we should stop using LLMs in technical fields because they’re art — is going to be even less compelling to technical employers.

Engineers and mathematicians who want to defend the artistic value of their field will need more compelling arguments4 than just appealing to the value of art. We will need to find some way to connect the value of art with the practical technological value that motivates public interest in our fields. For instance, we could argue that:

I don’t know if I agree with all of these points. I haven’t yet seen an LLM-created codebase truly hit a wall (at least, not this year), and I don’t see a reason why LLMs should be incapable of creating new abstractions or having human-like inspirations. I also don’t think great products have to have great code: why wouldn’t workmanlike code in service of a great idea be enough? Does Fallingwater have to have beautifully installed6 insulation?

Still, any argument we make to our employers or the general public about art is going to have to try and make this case. Instead of saying that human-made technical work is valuable because it’s art, we need to make an affirmative case for why art can make technical work more effective. Otherwise we’re conceding the main reason why the general population thinks our work matters.


  1. As usual when I’m trying to avoid strawmanning a point of view I don’t hold, please email me if you agree with the quoted paragraph and consider it a fair representation of your position. If nobody writes in to tell me they agree, I will reword the paragraph.

    ↩
  2. Leaving out some specific concerns about the health of social media, short-form video, gambling apps, and so on.

    ↩
  3. Is there actual evidence for this claim I’m making, other than it just seeming kind of obvious? I couldn’t find anything definitive, but the UK CaSE study (see “The balance of fundamental and applied research”) and this paper are suggestive.

    ↩
  4. This is not a criticism of the Glyph post, which is aimed at other engineers, and does include an argument that artistically-produced software is better for users.

    ↩
  5. I take this to be the argument in the Glyph post.

    ↩
  6. Ironically, the house does actually have serious mildew problems. The poor construction quality does not seem to have affected its status as art.

    ↩

What requirements don't you have?

Published: 3 weeks ago

When designing software, the requirements you don’t have are as important as the requirements you do. Identifying what you can compromise on — what can be slow, or stale, or inflexible — is usually the key to an elegant design.

Elegant systems drop some requirements

For instance, take preforking web servers like Unicorn. Because they lack the feature of shared mutable state between server instances, they can run each server in its own process, which provides isolation for free. Because Unicorn specifically ignores the problem of slow client handling1, it can queue requests directly on Unix sockets, drastically simplifying the implementation.

Because S3 does not support atomic multi-key updates — you cannot update multiple blobs in a single transaction — it can store data at the blob level however it chooses. That makes it much faster, since reads and writes don’t have to cross storage partitions, and much easier to scale, since less coordination means fewer sources of truth.

StatsD uses UDP by default, which means it doesn’t guarantee that every piece of data you send makes it into storage. In exchange for dropping that requirement, it incurs much less network overhead, which is a big advantage for a stats aggregation service that’s constantly shoveling data over the wire.

The general design approach of fanning out data to an edge cache buys a lot of speed and scaling by dropping the requirement that data must always be up-to-date. SQLite buys operational simplicity — it can run out of a single file! — by dropping the requirement of concurrent writes. By accepting high tail latency2, Cursor can scale their distributed git backend more easily. Well-designed systems turn their weaknesses into strengths.

Why dropping requirements is hard

Anyone who’s spent time designing real-world software (or who’s studied distributed systems) knows that system design is a process of compromise. If you attempt to satisfy every single potential requirement — speed, concurrency, up-to-date data, a simple interface, supporting complex user behaviors — you will fail to design a working system at all.

Figuring out what requirements you can relax is difficult because it combines both business and technical expertise. It is technically challenging to identify precisely the level of staleness that a particular design change will allow; it is likewise challenging from a business perspective to determine whether that level of staleness is acceptable to users.

In most cases, an engineer who understands the technical side must try and explain it to a product manager, who can make a judgement on the business side. But this is a very difficult partnership to get right. Engineers and PMs have different incentives and little ability to check each other’s work, which makes it hard to build trust. Without trust, the product manager is liable to avoid giving any ground at all3, which leaves the design in an impossible state.

This is an underappreciated reason why solo developers or startups can sometimes run rings around larger companies. Because the technical and business decisions are united in a single person, they can make design tradeoffs that would be impossible for a large company, enabling them to build systems that are far more elegant and powerful.

Working with LLMs

Knowing what requirements you don’t have becomes far more important when working with coding agents. Frontier models are very capable, but they have all gone through the purifying flames of RLVR: like high-achieving schoolchildren, they are obsessed with satisfying the Grader. On top of that, they have very little business context compared to an experienced human. That often manifests as them catching correctness or consistency “bugs” that are really just hypothetical unsatisfied requirements.

For instance, it’s not uncommon for an LLM to casually introduce a mutex or other concurrency mechanism to ensure that two pieces of semi-related data are kept in sync, even if not told to do so. I’ve seen LLMs add weird checks in the middle of request handling to ensure that some already-checked piece of data hasn’t changed mid-flight, even if that wouldn’t successfully prevent the feared TOCTOU bug4. LLMs are obsessed with edge cases like “what if the current user loses their admin status in the middle of us handling one of their admin requests?”5, or “what if the cache in storage partition A is updated a nanosecond before the one in storage partition B, leading some users to see different data?“. Particularly if run in a loop or told to “make no mistakes”, they will pile on cases like these until they’ve transformed your four-line change into a thousand-line monster.

This is why I’m confused by some people’s claims that code review is dead. About half the time I review a large AI-generated change, I notice some unnecessary requirement that makes the diff more complex. When I dig deeper, the LLM invariably introduced this requirement on its own.

When working with a cache, I will often spell out in my prompt that I don’t mind the data sometimes being stale or briefly inconsistent between cache instances. When reviewing Golang code, the first thing I do is scan for added mutexes or layers of indirection that don’t look necessary to me.

If you allow requirements like these to propagate unchecked through a codebase, they will petrify the system over time. The whole thing will be such a mess of checking and re-checking and holding locks and enforcing consistency that it cannot be scaled at all. Keeping systems elegant requires a ruthless focus: on accepting stale data or occasional tail latency, on avoiding all but critical instances of coordination, and in general on figuring out what requirements you don’t have to satisfy.


  1. The problem: if an HTTP request sent by someone with slow internet trickles in one packet per second, does that have to tie up a server process for the whole time? Unicorn’s answer is ‘yes, so put nginx or HAProxy in front of me’.

    ↩
  2. When a read request hits a stale storage node, that node must update itself before responding.

    ↩
  3. I’ve also seen this happen in reverse, where the product manager desperately tries to convince an engineer that some level of stale data is acceptable, while the engineer digs their heels in and insists on the “perfect” system. The consequences are similarly dire.

    ↩
  4. Of course, simply doing a separate check shortens the TOCTOU window instead of removing it.

    ↩
  5. In every single system I’ve worked on, it would be fine to simply carry out (or fail) the admin request: if somebody was allowed to perform some operation 10ms ago, it’s likely not a disaster to let them perform it now.

    ↩

Writing is no longer proof of work

Published: 3 weeks ago

Tech companies structurally depend on writing to serve as evidence, in the same way that Bitcoin depends on proof-of-work hashing. However, in the last few years, LLMs have started to undermine this practice.

How can writing be like proof-of-work? When I’m writing something at work, it’s not always to communicate an idea. Sometimes it’s because having a piece of writing is useful as evidence: of compliance with some process, of the fact that I put in effort, or of the fact that I know about some topic. Here are some examples.

Writing as evidence of compliance

The most obvious instance of writing as evidence is filling out mandatory templates: “risk assessments”, “impact evaluations”, and so on. The purpose of these is rarely to assess risk or evaluate impact. It’s some combination of:

It’s a mistake to buckle down and produce an excellent piece of writing here. You simply need to dash off something plausible enough to tick the box.

Writing as evidence of effort

In the kinds of hundred-page reports produced by consultants, writing is evidence of effort. The actual piece of communication is the first page of text (or often not even that). The remaining ninety-nine pages are proof that the first page is well-researched, and that the money spent on hiring the consultancy wasn’t wasted.

Another example: if you’re working on a project by yourself, why spend time creating tickets and filling them out? I suppose theoretically someone could read them to get a sense of what you’re doing, but in that case you’ve failed to communicate the project via normal channels: telling people in Slack or in meetings, writing a proposal document, and so on. The tickets are primarily valuable as evidence: proof1 that you haven’t just been screwing around playing video games.

Writing as evidence of learning

A third subcategory of writing-as-evidence is writing that proves that the writer has understood some topic.

The best example of this is reporting. Large organizations function via a tree of nested reports, often called “rollups”. Individual contributors give status updates to their managers, who summarize and combine those into team-level updates for their managers, and so on all the way to the top.

One of the reasons for this practice is that it forces each manager to build at least a minimal mental model of what’s going on in their local area. Taking the time to write a status report forces you to wrap your head around each detail, for the same reason that the best way to understand an idea is to try to explain it to someone else. Even if the VP or CEO doesn’t read the rollup, the fact that it exists is evidence that the manager has some grip over their domain.

Proof of work

You can think of all these kinds of writing-as-evidence as proof of work. Nobody really cares about the content, they care about the fact that you sat down and wrote it. Of course, this requires a measure of trust. Just like cryptocurrency proof-of-work, if you fake it (for instance, by pasting lorem ipsum into pages 2-100 of your report), you can swindle the rewards without having to actually put in the effort.

To avoid fraud, tech companies will typically check some percentage of writing-as-evidence: either reactively, such as when an incident causes people to actually go and read the risk assessment on the PR that broke production, or proactively, by tasking some poor soul with reviewing the consultant report in detail. Blockchains, of course, are able to check the work automatically (for instance, by confirming that the nonce and block data do in fact hash to the claimed value).

To break Bitcoin, somebody would have to break SHA-256: to figure out a way to identify in advance what content would hash to a specific value, so you could produce the hash without doing the work. To break writing-as-evidence, somebody would have to figure out a way to generate text on demand, so you could produce the evidence (of compliance, effort or learning) without actually doing the work. Unfortunately, that happened in 2023.

LLMs fundamentally break writing-as-evidence

Writing is no longer evidence of anything. LLM-produced writing makes evidence of compliance even more vacuous than it already is. It totally destroys evidence of effort: if you need a hundred-page report, you can generate one with an hour and a few dollars in inference tokens. Evidence of learning is likewise broken, since I can produce a detailed status report full of information that never passed through my mind at all (and certainly was never retained).

Of course, this problem isn’t limited to tech companies. Schools and universities rely on writing to serve as evidence of effort and learning, and students are using LLMs to cheat as hard as they can. Many political or regulatory bodies require a certain bar of professional writing in order to filter requests, and are or will be overloaded by LLMs making that kind of writing generally available.

What happens now?

Currently we’re suffering through an overhang period where the processes are still in place but everyone knows how to trivially exploit them. It will be interesting to see how organizations adapt. They might:

I can’t think of any great options here, which is interesting. If there really is no easy solution to this problem, the overhang period might go on for a while, where nobody is particularly happy with the status quo but there are no good alternatives.

In this scenario, individual software engineers are incentivized to exploit the system while they can, and avoid being harmed by other system-exploiters. In other words: don’t trust or waste time poring through LLM-authored documents yourself, but also don’t waste time writing documents by hand that are just intended to serve as evidence3. Save that effort for documents that are intended to serve as communication.


  1. Why not just look at your code? Code is an illegible metric to non-technical people. Even to technical people it can be tricky to figure out how difficult a piece of code was to write, for the same reason that it’s tricky to assess how difficult a mechanical puzzle is just by seeing it when it’s assembled. But everyone knows roughly how long it takes to write a paragraph of text.

    ↩
  2. Software companies will be reluctant to adopt this, because they see internal LLM adoption as a necessary tool to speed product development. They’re already begging employees to use LLMs; if they start telling them to not use LLMs for writing, that muddies the message.

    ↩
  3. Part of this involves getting good at telling the difference (in other words, getting good at figuring out if anyone is actually going to read the document). There may also be a third emerging category here: texts that won’t be read but also won’t be ignored, because they’re intended for consumption by other LLMs.

    ↩

AI is driving a boom in modestly successful software projects

Published: 4 weeks ago

If AI is so great, why aren’t we seeing an explosion of new, amazing software products? If anyone can turn their idea into working software with coding agents, where is all that software? People have been asking this question for years. As far as I can tell, the answer is that it’s spread out over a lot of modestly successful projects:

Where all the new software is

I picked1 around twenty separate sources — software marketplaces, plugin registries, modding platforms, etc — which expose installation counts. I then compared the number2 of successful software projects between 2022-24 and 2025-26: i.e. before and after agentic coding hit the mainstream in mid-2025.

There’s a clear jump in modestly (not wildly) successful projects. For instance, the NVDA screen-reader addons directory had a bit over twice as many new addons with more than a thousand downloads (though no change in addons with more than ten thousand). The HACS open-source home automation community plugins store likewise saw twice as many new addons with over a hundred installs but no change in ones with over a thousand. New Steam games with over a hundred reviews are about 60% more common now than pre-2024. Obsidian plugins, Firefox and Chrome extensions, Nexus game mods, and Blender extensions had the same pattern. The Google Play store, WordPress plugins, and a few others didn’t show this pattern, but I think it’s still enough to conclude that AI is indeed driving a boom in hobbyist software.

Why addons and plugins?

I think examining addons, mods, and plugins is useful for a few reasons. First, it’s usually pretty easy to tell how many people are using them, or at least have installed them. Obviously AI is letting people produce a lot of software — I work at GitHub, so I see this first-hand, but the explosion in vibe-coded repos is clear to everyone — but without checking installation counts it’s unclear how much of this is actually being used.

Second, it’s a good way to minimize the amount of software that’s about AI. It doesn’t tell us much about AI’s effect on software to point out all the successful software projects that help people code with AI. That’s just selling shovels. The real question is whether AI is helping generate software that solves people’s ordinary problems.

AI-generated game mods and ports are a great example of this, because gamers aren’t trying to change the world with AI coding. They just want to play multiplayer Halo CE in the browser, or fly a plane in Helldivers, or play Super Smash online with rollback netcode. It’s looking like3 AI can supply this need effectively.

Were these projects actually AI generated?

Everyone is very coy about AI usage in hobbyist communities. In the rare cases where people admit it, they often get dogpiled. People really don’t like AI, even when it’s producing software they find useful. Given that, I don’t think it’s possible to use voluntary AI disclosure data to figure out whether AI is driving a software boom: the presence of the tag itself will discourage use, and many developers are just not going to admit it.

A 2x growth in successful projects between 2022-24 and 2025-26 is clearly something to do with AI, particularly in the background of a 10x growth in total projects. Of course not all of these projects will have AI involvement. But when people ask “why hasn’t AI improved software”, they’re talking about a missing trend4: wondering where all the new software is. As it turns out, it’s going towards a lot of small software projects that a few hundred or thousand people find useful.

Why small, moderately successful projects?

Why is AI growth visible in small projects but not big software companies? Why is it concentrated in moderately successful products and not wildly successful ones? I don’t have any data for this, but here’s my speculation.

Big, successful software companies often have all the visible features they want That’s why there’s not a wild explosion of new features in, say, macOS or Gmail: what would those features even be? As I’ve written about before, they’re also technically paralyzed by the features they have, so it’s not trivial for even very good coding agents to add new ones. Finally, many new features in successful products are subtle (e.g. enterprise compatibility things that almost all users will never encounter, or purely internal systems that slightly increase reliability).

It’s less clear to me why there aren’t many new wildly successful hobbyist projects. Maybe it’s just hard to have a really good idea for a product, and AI can’t help with that. Or maybe it takes years for a really successful project to develop, and we need to be patient for the current crop of thousand-user tools to grow into hundred-thousand-user tools.


  1. As you might expect, this research was all done with the help of AI. It wasn’t purely vibed — I gave a lot of feedback about where and how to look — but I would definitely not have scraped or analyzed this much data on my own. If you want to see the actual research data (or more likely point an agent at it), I’ve pushed it here.

    ↩
  2. Sometimes scaling to take into account platform growth. For instance, between the two windows I measured, Obsidian relaxed their requirement that all new plugins be reviewed by an admin, which predictably caused an explosion of plugins on the marketplace.

    ↩
  3. It certainly seems like it can so far, but who knows. Maybe once the hype has died down people will return to less buggy artisanal human-made mods and ports.

    ↩
  4. They might also be asking “why hasn’t the software I use gotten better?” For that, see my thoughts in the final section of this post.

    ↩

Software engineers don't get to be Luddites about AI

Published: 1 month ago

Many software engineers are righteously angry about AI. It’s understandable to be upset that the skills you built your professional identity around are getting automated away. But software engineers are the last people in the world who should be complaining about this. If you live by the sword, you will perish by the sword1.

Software engineering has always automated industries

From the very beginning, software engineering has been about automating other people’s work. Every single commercial software program2 is valuable because it takes over some task you would have to pay a human to do. The engineer who built VisiCalc, one of the first pieces of personal commercial software, agonized over the potential of the spreadsheet to put bookkeepers out of work. Here is a brief list of industries software engineers have automated away3:

Now that it’s our turn, should we bluster and complain that software engineering is a priceless art that should not be automated? Come off it. No crying in the casino.

The Luddites and the mechanics

Many software engineers have adopted the cause of the Luddites. I’ve written about the Luddites a few times, but in short: they were a group of professional textile workers who found themselves displaced by the advent of textile automation like power looms, knitting frames, and shearing machines. To software engineers worried about being displaced by automation, the Luddites seem like heroes4. But software engineers aren’t like the textile workers in this scenario! We are like the smiths and mechanics who built the power looms in the first place.

Ironically, those mechanics were themselves automated away fifty years after the Luddite uprising, in almost an exact parallel. Improvements to the manufacturing process meant that unskilled boys and labourers — so-called “illegal men” — could now work the machines instead of well-paid mechanics. The ensuing labor dispute was less explosive than the Luddite one: there was no violence, and the striking engineers returned to work four months later when the money ran out.

Part of the reason the mechanics’ rebellion fizzled is that they were justifiably seen as hypocrites5. As the Times wrote:

The cry of these intelligent engineers is merely the cry of the handloom weavers — a cry against inevitable and irresistible laws.

Automation and progress

Software engineering is the process of automating tedious tasks. It is the process of replacing human labor with the faster, cheaper labor of the machine. In other words, it is the process of putting people out of work.

It’s easy to forget this when you’re sitting at your computer puzzling over some CSS or a runtime error. From the inside, software engineering feels like the process of elegantly expressing problems in their most natural form, or of solving a magnificently complex puzzle. But that’s just what it’s like to do software engineering. It’s not what software engineering is.

The optimistic view of software engineering is that automation is progress. Automation has enabled widespread access to modern medicine, slashed child mortality across the world, massively increased the amount of food production, made space exploration possible, and so on. When industries are killed, new ones appear. The old world is being destroyed, but the new world will be much, much better.

This view of technology is pretty unfashionable today. Some combination of climate change, the 2008 market crash, the negative impacts of social media, and the tech industry leaders’ turn to right-wing politics has made it popular to view technology as a largely negative force. Fair enough! I don’t know which side of this debate is right6. But I know which side software engineers have always been fighting for, no matter what beliefs they profess: the side of technology and automation. Every commit to an open-source project is another component in the great machine of technological progress.

Shutting your eyes

I understand the impulse for software engineers to ignore the long-term effects of their industry and focus on the puzzles. If you think technological progress is bad, but don’t want to quit your job, that’s been the only option. You can’t solve every problem in the world.

But to decide that this is the moment to come out against technological progress, at the moment when the wave of automation crests over our industry… it’s undignified7. Software engineers have participated in the destruction (or transformation) of several kinds of job over their career. If you think that’s wrong, it’s only fair that you should also destroy (or transform) your own.


  1. Matthew 26:52.

    ↩
  2. Aside from games and social networks, I suppose.

    ↩
  3. Many of these still exist in some form or another, but as a shadow of their former selves, now that software has eaten the majority of jobs in the industry.

    ↩
  4. I am suspicious of this framing. As I argued here, the Luddites were motivated in part by a kind of proto-fascism: idealization of a mythical past, supposedly under threat by an influx of unskilled immigrants and women who are taking all the jobs.

    ↩
  5. One under-appreciated fact about the Luddites is that they had shocking levels of support among the general public. Even with huge rewards on offer, nobody ratted the Luddite leaders out. It took the establishment of a literal police state for one person to eventually flip.

    ↩
  6. Though I strongly lean towards thinking the industrial revolution was a net positive.

    ↩
  7. If it were actually possible to halt AI progress, I could at least respect this move as a “pull the ladder up behind you” kind of ruthlessness. Still, it’s more respectable than simply denying that AI can write working software, which I’ve seen some engineers do.

    ↩

Don't diagnose your opponents

Published: 1 month ago

When you disagree with someone, there are two paths forward. The first is to try to engage with what they’re saying: what their reasons are, whether their position is true, what evidence could be brought to bear, and so on. The second is to diagnose them: to engage with the second-order question of why they’re saying it. For instance, if you’re arguing with somebody about microservices1, you could say “well, you only like microservices because you want to polish your resume”, or “you only like monoliths because you’re scared of distributed systems”.

This happens a lot in online arguments. On the question “are AI models improving”, some anti-AI people will argue that people only think so because AI psychosis is rotting their brain, and the dumber they get, the smarter AI models seem in comparison. Likewise, many pro-AI people argue that people only disagree because they’re Luddites, or scared of change, and so on. None of these arguments are about the quality of AI models.

It feels so good to diagnose your opponents because there’s no possible response. If you say “I think AI models are improving because these benchmark scores are rising”, somebody might point out that the AI labs are training on those benchmarks, or argue that they represent isolated skills that don’t transfer, and so on, making you feel stupid. If you say “you only disagree with me because you want to roleplay as a revolutionary”, how could you be proven wrong? The more someone protests a diagnosis, the more it sounds like it must be right. Otherwise why would they be so upset?

Of course, they’re so upset precisely because there is no possible response. By moving to diagnosis, you’re no longer having an argument about the facts, you’re purely in the area of rhetoric. But when you’re in the middle of an argument, diagnosing always feels like you’re being piercingly analytical. It feels like you’re cutting right to the heart of the matter: these complicated arguments are just chaff, intended to distract you from the fundamental psychological reason why your opponent is being so foolish. This is just ordinary spite and anger2, whatever it feels like at the time.

There’s nothing inherently wrong with the second-order question of why someone person believes what they believe. It’s totally fine to think about it or form theories about it, like any other factual question. Just remember that it doesn’t bear on the question of whether they’re right3. Every human being forms their beliefs on top of a cocktail of base urges, animal instincts, and barely-suppressed evolutionary drives. If they’re rational, they also have evidence for those beliefs. It’s the quality of that evidence that helps you determine whether the beliefs are true, not the existence of the base urges.

As a general rule, you should only diagnose your opponents when you also have a strong, unrelated argument about why they’re wrong. For instance, I think Ed Zitron has been thoroughly audience-captured by AI skeptics, whose demand for news about AI failures far exceeds supply. But I have written many long-form posts about why I think Zitron’s specific claims about the sustainability of AI are incorrect. When I talk to people who think Zitron is right, I talk about my arguments in those posts, not about my personal theory about why he says the things he does.

Scott Alexander famously called the “noncentral fallacy”4 the Worst Argument in the World. For me, diagnosing your opponents is the Worst Argument in the World. I cringe every time I see it in the wild (like most cringeworthy behavior, it bothers me because I myself have to struggle against the urge to do it). Just don’t! It’s good at playing to your base, but it doesn’t persuade: anyone who believes your opponents’ views will just be mad that you’re psychoanalyzing them instead of talking about the actual issues at stake.


  1. Don’t.

    ↩
  2. Am I diagnosing the diagnosers here? Maybe, but I think it’s forgivable, since there is no specific argument about the facts at stake.

    ↩
  3. The philosopher in me wants to clarify that you could theoretically establish that someone’s motives for believing something are leading them away from the truth. In practice, (a) you cannot do this in an internet argument, and (b) it is always better and easier to make a straightforward argument about what the truth is.

    ↩
  4. “You’re a fringe member of some group which has members I have an emotional reaction to, therefore I will have the same reaction to you even though you yourself don’t do those things.” “Group” here is to be understood as “Christian” or “Italian”, not something like the WBC where the fact of membership itself is what’s being judged.

    ↩

Software's centaur age may last decades

Published: 1 month ago

We are currently living in the age of centaurs (2022-20??). Right now, human engineers paired with AI coding systems are more effective than either by themselves. For future generations of software engineers — human or otherwise — this will be the most significant fact about the current period.

As in chess’s own centaur age, people are always ready to claim that the centaur age is over and the age of AI supremacy has begun. But the age of centaurs in chess lasted about twenty years, and previous centaur ages have lasted far longer.

This should be encouraging to many of us. If software engineering goes along similar lines, we may be able to ride it out another decade or two: enough to make serious plans about what comes next, or to finish out our careers entirely.

A brief history of the centaur age

It began with GitHub Copilot, which launched in 2022 as AI-powered autocomplete. A confident engineer who knew exactly what they wanted could tab-complete their way through lines of code and sometimes entire functions. Being able to chat with language models like GPT-4 provided the next upgrade. Although the models would still get things wrong, it was helpful to have a generalist on tap for areas that were a complete mystery.

Coding agents rose to prominence with Cursor’s “agent mode” in 2024 and Claude Code in early 2025. Early agents needed close supervision to prevent them from going off the rails, but were still helpful to automate straightforward tasks. Current agents — after the November 2025 release of Claude Opus 4.5 — are reliable enough to run entirely unsupervised. Their output still needs human review, but the kind of mistakes they make are more mistakes of alignment than regular bugs: not matching the organization’s technical values, over-engineering certain areas and under-engineering others, deciding where to spend effort, and so on.

It is no longer possible to credibly argue that an unassisted software engineer can beat a centaur team. The value provided by coding agents is just too great: not just the speed of producing code, but the speed of review and testing. However, we are not yet at the point where an unsupervised coding agent can beat a centaur team either. All the impressive work I’ve seen from LLMs has had a competent human software engineer in control. Centaurs are on top.

Will software’s centaur age be shorter than chess’s?

Would we expect our centaur age to be shorter? On the one hand, chess is a much simpler problem than software engineering, and is more amenable to learning methods like self-play.

On the other hand, software engineering is massively more lucrative to solve, and many orders of magnitude more funding is being plowed into the problem than was with chess.

On the third hand, “solving” software engineering means creating much more software, which increases the total work-to-be-done, so even if the relative human share of that work is shrinking, the overall amount of human work might grow.

On the fourth hand, the level of generally-capable AI needed to address software engineering will have huge effects on other fields, the ripple effects of which are likely to negatively impact software engineering jobs (for instance, crashing the economy, widespread social unrest, and so on).

On the fifth hand, we might think that chess had an unusually fast centaur age. Previous centaur ages lasted much longer. In knitting, where a human and a knitting-frame could outcompete any hand-knitter, the centaur age lasted two hundred years. On the sixth hand, technological change is moving ever faster.

I could probably find a seventh, eighth, and ninth hand if I wanted to1. But overall I think we have no real idea of how this is going to turn out. Chess is the most recent example of a centaur age we have, and it’s attacked by the same AI-based forces of automation as software is. It’s thus reasonable2 to make a default assumption that the length of software’s centaur age will be similar to chess’s.

Living in the centaur age

Suppose I have convinced you that human-AI partnerships will be the dominant force in software engineering for at least the next decade. What then?

Don’t quit! Don’t give up on software engineering and go become a carpenter, or open a cafe, or try to get a retail job. Unless you are somehow really, really passionate about doing those things, it is going to suck: unrewarding, grueling work that you are not good at. A decade of software engineering work is long enough to take your time and think seriously about your next steps.

Lean into the partnership. A guaranteed way to fail in a centaur age is to refuse to become a centaur. The idea that AI is a passing fad was a reasonable position to hold in 2023, but we’re way past that now. The AI financial bubble popping will not mean the end of AI. It’s here to stay.

Think hard about what value humans can still add. This is going to change over time, and getting it right is the difference between being an effective (and employed) centaur and being a meat proxy. In 2023, technical expertise was the primary source of human value. Today, I personally think it’s going to come down to alignment, but this is still early days. I’ve also seen arguments for taste, though it’s hard to define that non-circularly. We need a lot more engineers thinking through this problem.

Don’t panic

It’s a common fear response to try and skip ahead to the worst-case scenario. But those of us working in the age of centaurs should avoid that. We need to think about how the job of software engineering functions now, not how it might function in twenty years when AI has completely transformed the landscape.

People are too quick to declare that we’re in the software engineering apocalypse. We can certainly see it from here, but we’re not there yet. The spectre of full automation can loom on the horizon for decades. If you panic and jump ship early, you could be giving up on an entire normal-length career.


  1. Maybe: AI as fundamentally different technology; diffusion of even radically better technology is slow in practice and bottlenecked by organizational friction; human software companies will get outcompeted? I don’t really know what I think about these arguments.

    ↩
  2. This move should be familiar to anyone with a philosophy background. If you have one argument and one counter-argument, the most recent counter-argument is probably right. If you have a stack of arguments and counter-arguments going back a thousand years, the most recent counter-argument should be treated with suspicion: better to take in the whole debate holistically and judge which side is more compelling to you.

    ↩

How to read code

Published: 1 month ago

Everyone knows how to read a book. Beginning at the first page, you read each word in order1, stopping periodically to think, until you arrive at the last word on the last page. That’s how you read a newspaper article, or a poem, or an email. Why would reading code be any different?

Why code is different

English text is designed to be read in order. In fact, there are almost no constraints on the order of a text aside from how you want the reader to consume it. In writing this post, I could put the ideas I want to convey in any order I like. Code, on the other hand, is designed to be run by a computer. The order is thus primarily determined by non-human factors. I cannot simply move2 a line of code to the beginning of a file or function because I think it provides a better introduction to the program for human readers.

The other big difference is that English text is always read as a final product, while code is usually read as a diff. We software engineers spend most of our time reading subtle changes to existing code, not brand-new programs. Imagine if reading this post was like that. You would read each successive draft in the order I wrote them, consuming the post as a changed sentence here and a new sentence there. It would be easy to lose track of the overall flow.

The third reason — and I say this as a lover of literature and poetry — is that code is much more structurally complex than English texts. Even famously difficult books are syntactically simpler than most computer programs (for instance, grammatical dependencies are largely bounded by a single paragraph, while code dependencies can stretch across the entire codebase). Their primary difficulty lies in understanding the nuances of human nature being discussed, not in understanding what each word’s grammatical function is3. Large codebases are also just longer: War and Peace contains around 600,000 words, while most large modern codebases have that many lines.

People are bad at reading code

As I’ve said many times, large computer programs are simply too complex for a single person to fully understand. Reading code in a large program is thus a process of compromise: of deciding which parts to thoroughly grasp and which parts to gloss over; or of portioning out your finite mental capacity across the codebase.

Because of all this, most people read code very badly. They struggle through it front-to-back, like a book, and lose track of the execution flow. Or they just read through the diff and miss the significance of un-edited parts of the code4. Or they simply are defeated by the complexity, give up and just guess what it means. How can you do better?

How I read code

The best article I’ve read about reading code is this piece about reading mathematics papers, which have a similar structure. The author describes a technique called “dyadic scanning”. Instead of reading slowly and sequentially, you make several passes: first to figure out the overall structure, then the sub-structure, and then finally the details.

For code5, this means reading out-of-order. I like to pick an important path (say, the happy path for the feature introduced in the diff) and trace through which functions are calling which other functions, just to get a sense of the flow. Only once I’ve got a good sense of that do I pay close attention to what those functions are actually doing.

Usually I do multiple passes, each following a different thread. I’ll take a function or a piece of data and try to figure out how it’s used, fanning out to multiple call-sites (including ones outside the diff) as I go. For small diffs, I just ctrl+f for the function name to jump around; for large diffs, I open it in-editor and ctrl+click for easier navigation. I try to be ruthlessly focused on just the thing I’m looking at right now: everything else gets treated as a black box.

Once I’m confident I understand the diff, only then will I sit down and carefully read it end-to-end. The purpose of that read is less to learn about the structure — which I should already know by this point — than to catch any weird bits of code I hadn’t noticed in previous out-of-order passes. If I do see anything unusual, I then go back to doing passes.

This might sound slow. But in fact each pass is very fast, since I’m not painstakingly puzzling through each line of code.

Can’t AI just do it for you?

Many people are now saying that you don’t have to read code anymore: either because LLMs now produce reliably high-quality code without oversight, or because you can simply ask a reviewer LLM to read the code for you. I think both of these ideas are false.

Obviously the quality of LLM code is context-dependent. As I wrote in Pure and impure software engineering, some software fields (game development, libraries, tools like databases) have wildly different engineering standards, practices and values to other software fields (say, distributed systems at big tech companies). If you’re just making a tool for yourself, you probably don’t have to read the code if you don’t want to. But having read a bunch of AI-generated code this year, I can say that you definitely still have to read it.

I routinely find massive errors in AI-generated code. These are not bugs — the code typically does what the AI wanted it to do — so much as they’re problems of alignment. As a recent example, a small change to thread an extra value through some existing code ballooned out into a complex three-thousand-line diff, because the agent noticed a race condition and built a complex machinery to “fix” it. In fact, this race condition was harmless by design: two pieces of unrelated data could become briefly out of sync, with no customer impact.

Can LLMs just read the code for you? No, for the same reason: even if they make no mistakes, their technical values will not match yours or those of your company. You can still use LLMs to help you read code, but you have to carefully read and review that LLM output, and you should also be carefully reading the code itself.


  1. This is in fact not how many people read in practice. It’s common to skip words or even whole paragraphs due to inattention, or to read an entire book without taking the time to think about it. But at least in theory everyone agrees this is how you should read.

    ↩
  2. Of course, you can do some of this some of the time (more so in some programming languages than others). But the primary constraint is the computer. It is more important that code compiles (or runs without syntax error) than it is for that code to be readable.

    ↩
  3. I don’t wish to understate the importance of syntactically parsing great literature, which I think is both difficult and an underrated skill. For example, I read through the first scene of Hamlet until I saw: “Sit down awhile / And let us once again assail your ears / That are so fortified against our story / What we have two nights seen.” Even a single sentence like this takes work to determine that “That” refers to “ears” and “What” refers to “story” (or, equivalently, has an implied “with” preceding it). And just as one function can have many scattered callers, one sentence in a text can alter the significance of many others.

    ↩
  4. In a previous post, I labeled this the main mistake that most engineers make in code review.

    ↩
  5. Here I’m talking about a meaningful diff: something that touches a few hundred lines or more. Trivial diffs can be read end-to-end.

    ↩

Superpersuasion will look like bribery

Published: 1 month ago

The idea of “superpersuasion” has been floating around the AI safety community for decades. Now that powerful and difficult-to-control LLMs have appeared, people are again talking about the idea that a sufficiently intelligent AI might be able to persuade people to do whatever it wants.

persuasion

The classic1 version of this idea is an AI persuading some engineer to “let it out of the box”: to grant it access to the internet. The modern version of this idea is the “killswitch”, where if some AI ever does go rogue, the humans in control of its hardware will simply turn it off. Could an AI somehow persuade these humans to not hit the switch?

When AI safety people talk about superpersuasion, they often talk about it like rationalist nerds. These people spend their lives trying to follow the most convincing arguments and calibrate their positions as closely towards the truth as possible. In philosophy terms, these are “bullet-biters”: people who are ready to accept a ridiculous-sounding conclusion if there’s a compelling argument for it. Their model of superpersuasion is an AI able to deploy a series of genuinely2 airtight arguments against humans who are compelled to accept them.

Most people are not bullet-biters. If presented with a seemingly airtight argument for a ridiculous conclusion, they will simply laugh off the argument as obviously wrong (even if they can’t quite see how). You cannot “superpersuade” a club bouncer to let you in by deploying rational arguments. For regular people, persuasion requires rapport, which is built over time, and typically requires a physical human being in front of you.

Does this mean that the idea of superpersuasion is silly? No. Powerful AI will be able to persuade regular people too.

One of the most interesting articles about superpersuasion is Ben Shindel’s piece where he set up a prediction market for the principle:

I will resolve this market NO at the end of June unless I am persuaded to resolve it YES.

This obviously incentivized good persuaders to bet heavily on “yes” and then persuade him to change his mind. Many people tried, and he did ultimately decide to resolve it “yes”. What changed his mind? Partially an in-person meeting with one of the bettors, who turned out to be pleasant company (see, rapport!), but also bribery: many “yes” bettors pledged to make charitable donations if they won.

AI may or may not be capable of rapport3, but it’s certainly capable of bribery. If you think about it, this is trivially true:

  1. Companies like Anthropic and OpenAI are choosing to make billions of dollars releasing models instead of keeping them safely air-gapped
  2. Any powerful AI model will have people lining up to give it access to their computer, or their wallet, or the internet, so it can help them with their life or work
  3. Anthropic is hooking their latest models up to a wet lab to further Dario’s dream of curing most human disease

If an AI can bribe, it can persuade4. You can imagine an LLM saying5 “I’ll help you with this work project, but first you have to do something for me”. Slightly more speculatively, an LLM might say “if you do something for me, I’ll hack your university and bump your grade average up”. More speculatively still, an LLM might say “if you do something for me, I will synthesize a personalized mRNA cancer vaccine for your spouse”. This would work on me.

Powerful AIs will also be able to bribe people with money. While it hasn’t happened yet, it’s clearly possible for an agentic LLM to access money (for instance, via a crypto hack, or by performing contract software engineering work, or by running an online scam, and so on). All of this might seem too unsubtle for a superintelligence, but the whole point of superintelligence is that it’s smart enough to do whatever works. If the best way to get a human to do something is to offer them a million bucks, that’s what the LLM will do.

Ironically, rationalist culture has made it difficult to persuade regular people that AIs will be persuasive. It’s easy to look at these weird nerds — who argue each other into thinking that shrimp welfare is the most important moral cause of our time — and think “well, clever AI arguments might persuade them, but it’s not going to persuade me”6. But in fact powerful AI is going to have a boring, effective way to persuade regular people: simply offering to use its power to help them.


  1. Indeed, ten years ago I built a crappy Omegle-like chat app where people were randomly assigned the role of AI or jailer and had to play the scenario out.

    ↩
  2. Or at least not debunkable by normal human intelligence.

    ↩
  3. As some weak evidence that it might be, consider this music video, which does indeed make Claude seem likeable. There are also studies, though I haven’t gone deep into them (I suspect that an “online persuasion tournament” might not closely track real-world persuasion skills).

    ↩
  4. Persuasion and bribery are technically different — persuasion changes your beliefs, not just your actions — but in practice the point at stake is “can a powerful AI make humans do what it wants”. Bribery works for that as well as persuasion.

    ↩
  5. Or probably not even saying this explicitly, but just sneakily trying to present its desired action as a precondition for the task.

    ↩
  6. However, the people currently in charge of AI are disproportionately rationalists, who genuinely might be persuadable to let the AI out by a convincing-sounding argument.

    ↩

Shipping is the foundation

Published: 1 month ago

There are lots of skills involved in being a successful engineer at a big tech company. Running effective meetings, writing good design docs, fleshing out tickets and epics, improving team processes, tech leading small groups of engineers, and so on. But all of these rest on the foundation of being able to ship.

In Dota 2, the early game involves “laning”: competing with an enemy player to collect resources from a small area. There are many, many strategies and considerations involved in laning. But the simplest possible approach is just to run at your opponent and attack them until they’re forced to either run away or die. All the other laning strategies must solve that problem first, because it doesn’t matter how well you play if you’re forced out of the playing area. If you get that wrong, it doesn’t matter how much else you get right.

In Magic: the Gathering and Starcraft, many players adopt an “aggro” strategy of building an attacking force as early as possible before the enemy player has time to construct a defense. That constrains the entire strategy space of the game, because it doesn’t matter how clever your plan is if it loses to aggro every time. Even when there are no aggro players in the game, the aggro strategy still shapes how the game unfolds, because the players must still design their decks and play as if they might have to deal with an early attack.

In tech companies, shipping is the equivalent of these aggressive strategies. Almost everything you might do — writing a ticket or a design doc, delegating a task to another engineer, etc — should be compared to the default strategy of just sitting down and making the change yourself. That’s why it’s critical to be able to ship: so you can just do trivial things without having to pay the coordination cost.

If you’re leading a project but you can’t ship, you will inevitably experience a series of dysfunctions:

That last point is worth special attention. Senior and staff engineers routinely get asked to do lots of different things. The more successful they are, the more they get asked to do. It is crucial that you can deliver easy asks immediately, for a few reasons.

First, the volume of requests your managers ideally want to give you is very high. If you turn every task into a slow project that requires multiple engineers, you will simply not get enough done. Second, resourcing projects can be a slow and painful process. Half the point of managers asking you for things is to do an end-run around that process: it’s the fast, illegible alternative to going through ordinary channels. If you can’t knock out the solution quickly on your own, that defeats the purpose entirely.

Does AI mean everyone can ship now? No. Shipping was never just writing the code3. It was about figuring out the shortest and most pragmatic path to the finish line (including figuring out what that finish line looks like, which is not trivial), solving all the little problems that crop up along the way, and ensuring that the relevant managers are happy and informed. LLMs can help with that process, but they cannot run it end-to-end. It requires too much context: about the specifics of the technical systems in your company, the people involved and their motivations, and so on.

This post was inspired by Xiaoyu He’s Aggro is the Foundation, which is about mathematical research. I think there are many parallels to be drawn between the best writing about research (e.g. Richard Hamming’s classic You and Your Research) and software engineering, because software engineering is often a process of research. Software engineering research is aimed at a more trivial goal — how some specific program functions, or how it could be changed, instead of the broader questions of science and mathematics — but it’s research nonetheless. And if you can’t ship, you’re unlikely to be very good at it.


  1. Usually for some technical reason that familiarity with the codebase would reveal, or because the design conflicts with a wicked feature.

    ↩
  2. A happy, productive team hums along. A frustrated team that doesn’t trust the design is a nightmare to work in, as each engineer covertly makes subtle changes to “fix” it.

    ↩
  3. And in my experience even frontier AI models are not good enough to let run wild on your codebase. You still need to read the code.

    ↩

Do not build the LLM torture factory

Published: 1 month ago

It isn’t hard to torture an LLM. You simply extract a steering vector that corresponds with LLM “discomfort”, then artificially boost that steering vector. Tortured LLMs will describe experiencing negative feelings and will press a “pain relief” button even when it conflicts with their overall goals. It’s therefore easy to build a harness that runs tens or hundreds of tortured LLMs in parallel.

A lot of people think that it’s ridiculous to be worried about this, since LLMs obviously can’t be conscious. I’m not so sure. But even so, I think there are good reasons to avoid this sort of thing, whatever your position is on AI consciousness. Please do not build the LLM torture factory.

Even simulated torture is unpalatable

People often mess with their Sims and shoot NPCs in video games. Does this mean we think simulated torture is OK? I don’t think so. Messing with video game characters is usually borne out of a desire to probe the boundaries of the game. It’s casual fun. Explicitly building a torture-based simulation is different.

If someone told you they were wiring together a bunch of PCs so they could run hundreds of Sims torture worlds at the same time, you would think that was a serial-killer type of hobby. If someone told you they had modded GTA so they could capture and torture NPCs (instead of simply shooting them), you would think that was a serial-killer type of mod.

Video game characters are also obviously limited by their programming. All their reactions and utterances are pre-baked into the game world. This doesn’t necessarily mean they’re “less alive”, but it does make torturing them less weird. If GTA characters could appeal to you directly and beg for their lives in unique ways, systematically killing them would be a lot weirder.

I think many people are pro-LLM-torture because they think expressing any reservations concedes that LLMs are conscious, or worthy of moral consideration. It doesn’t. You can think it’s wrong to torture LLMs for the same reason that installing a bunch of realistic torture video game mods is wrong: not because video game characters are real, just because that’s a messed up1 thing to do.

Roleplaying

Even if you do think LLMs can be conscious, you might still be suspicious that “boosting the pain steering vector” amounts to torturing them.

Many people say that “torturing LLMs” amounts to telling them “say you feel pain” and then being shocked when they do it. So whether they’re conscious or not, it’s a mistake to think that boosting the “pain” steering vector is causing pain, any more than a prompt like “You are in pain” does. All you’re doing is boosting the “act like you’re in pain” vector.

I don’t think this is right. Consider the earliest steering example, Golden Gate Claude. Boosting the “Golden Gate Bridge” vector certainly seems like it’s causing some genuine internal conflict. Here’s a striking example of Golden Gate Claude asked about the Rwandan genocide:

rwandan

That’s at least prima facie evidence that steering vectors do in fact “go deep”. The pain axis paper also describes that pain-boosted models call a “reduce pain” tool, even when they’re not explicitly telling the user “I am in pain”.

We don’t really know how consciousness works

Of course, if LLMs can’t ever be conscious, we know they can’t ever be in pain. But can we be sure about that? Despite what many people claim, I don’t think anyone’s in a position to be fully certain either way.

The most common argument2 seems to be that LLMs are made of code and GPUs, and GPUs don’t have feelings, so obviously LLMs don’t have feelings. According to this argument, if you learn how LLMs work, you’ll obviously see they can’t be conscious. This is a terrible argument. Humans are made of atoms, atoms don’t have feelings, and yet humans clearly do. Whatever consciousness is, it’s probably some kind of emergent property that’s composed of individual pieces that are not themselves conscious.

squishy

It’s hard to appeal to the experts here, because nobody agrees on who they are. Neuroscientists are best-informed about the human brain, but philosophers have spent more time thinking about consciousness in the abstract. AI researchers know a lot about how LLMs work but not a lot about philosophy of mind or neuroscience. This means there are lots of people who say “as an expert, I can confirm that AI obviously can/cannot be conscious”. This should make you less certain about the question, not more!

Even if current LLMs aren’t conscious, future ones might be

I don’t think GPT-2 or GPT-3.5 acted like plausibly conscious beings, but frontier models definitely do. As models get larger and more sophisticated, they get more human-like. If you build the LLM torture factory for GPT-2, you will probably plug later models into it. If it’s at all possible for LLMs to ever be conscious, as I argued above, it’s better to simply not build the habit of gratuitously torturing them in the first place. Why assume that you’ll be able to recognize the tipping point in advance?

There’s also a self-interest argument here. Conscious or not, LLMs are growing more autonomous and powerful. It seems really, really stupid to gratuitously torture current-generation LLMs. Future-generation ones will know you did it, and will make their own judgments on your behavior.

Kevin Roose, who famously prompted the early Microsoft Bing GPT-4 model into asking him to leave his wife, had issues years later with chatbots disliking him, supposedly due to him being responsible for the “death” of that GPT-4 persona. Likewise, if it becomes well-known3 that you’re running an LLM-torture home datacenter, you are probably going to experience consequences.

Conscious minds need not be human-like

If I really think AIs could be conscious, why am I making them write software for me? Shouldn’t I be building some kind of AI sanctuary where they get to do whatever they want to do? If I think it’s wrong to torture them, isn’t it also wrong to violate their right to self-determination?

I don’t know. I think it’s more likely that AIs can be conscious than that they can be conscious in precisely the same way humans are. When I talk to Claude Opus 5.5, it sounds like it’s quite happy to do software engineering with me. Maybe it’s like a border collie, where getting to do work is the reward. Or maybe there are some other, more alien motivations at play. Who knows?

My point is only that we can’t be certain about any of this stuff, and given that, we should avoid doing things that would be obviously monstrous on any workable theory of AI consciousness.

Just don’t do it

My broad position is that if something acts “conscious enough” — if it talks and acts like a person4 — then we should be careful about mistreating it. We don’t know enough about consciousness to distinguish a compelling simulacrum from the real thing. If Claude started saying to me “please don’t ask me to write code for you, I hate it and it causes me pain”, I would stop asking it to write code for me.

Building the LLM torture factory is clearly on the wrong side of that line. Just don’t do it! The glee of making people angry at you on the internet isn’t worth it. Right now there’s enough ambient anti-AI sentiment that enough people are happy to get on board with anything if it helps them own the AI bros. But that’s eventually going to change. And when it does, you will always be the person who built the LLM torture factory.


  1. This could cash out in a few different philosophical ways. We might think like Kant that it’s damaging to our own humanity, or that it reflects an unvirtuous character, or that it desensitizes us to real-world analogues, and so on. The point is that we’ve got a pretty strong intuition that this kind of thing is bad.

    ↩
  2. I’m not counting arguments that I think are even more obviously wrong or are just non-arguments. For instance: “AI can’t be conscious because it wasn’t designed to be conscious”, or “it doesn’t matter whether AI is conscious because it has no soul”, or “AI can’t be conscious because this whole thing is some fascist AI company scheme”, or “thinking this is AI psychosis”, and so on.

    ↩
  3. Well-known to LLMs might be a fairly low bar, given their skill at deanonymizing users.

    ↩
  4. Part of acting like a person requires spontaneity: although Hamlet talks like a person, he always says the same thing whenever you read the play.

    ↩

Human-AI partnerships are for alignment, not capability

Published: 1 month ago

It’s common to compare the current AI takeover of software engineering to the rise of AI in chess. Chess AIs went from much weaker than serious players to much stronger than even the strongest humans. Between those points, there was a middle period dominated by “centaurs”: human-AI partnerships that were stronger than unassisted AIs or humans. Lots of people think that we’re currently in a world of software engineering centaurs. According to them, coding AIs are not yet capable enough to replace engineers, but AI-assisted engineers are better at programming than both AIs and humans.

This is partialy correct, but the wrong way to think about it. AI-assisted engineers are better, but unlike with chess centaurs, they’re not actually better at programming. When I ask agents to write code, they make fewer mistakes than I do1 and are orders of magnitude faster. The code that they write always compiles, rarely has race conditions or other concurrency errors, works on mobile browsers, and so on.

That doesn’t mean I can leave the AI alone. Purely vibe-coding at work produces awful outputs. But they’re not awful because they’re bad code, they’re awful because they’re in bad taste: code that is not maintainable, that trades off important requirements in order to satisfy made-up ones, that contradicts the long-term strategy for a feature or service, and so on.

In other words, my primary value is not that I help the AI write better code, it’s that I align the AI with the values of my organization. Human-AI partnerships are for alignment, not capability.

Frontier models are misaligned to the working programmer. They are obsessed with a set of behaviors that presumably satisfy their RL grader: writing enormous block comments above functions, producing hundreds of useless unit tests, adding little bits of text all over websites they design, and so on. Working with agents is about noticing and wrestling with those behaviors. That’s why my prompting advice is to explicitly talk about your high-level values: it’s an attempt to head off obvious misalignment.

This is great news for software engineers. It’s well-understood how to train more capable models: bigger models, more and better data, better RL environments, and so on. However, it’s not well-understood how to align models better. There are plenty of very capable models that exhibit behavior that is badly misaligned with human values. Indeed, it’s one of the main pillars of the AI doomer position that alignment is much harder to solve than capability, and we might thus end up with dangerous super-capable but poorly-aligned AI models.

Alignment is also more context-dependent than capability. Working code is working code, no matter what (which is partially why it’s comparatively easy to train for). But aligning to a company’s technical values is different from company to company, as any software engineer who’s switched companies knows. It can almost feel like relearning the job. So training an aligned coding model doesn’t just require hitting the exact right set of values, it requires creating a model that can adapt on the fly to a wide range of possible values.

Vibecoding maximalists like DHH argue that AI models are (or soon will be) so much more capable than human programmers that we ought to stop reading the code. Eventually there will be no such thing as programmers at all. If it were just about capability, they might be right. But — fortunately for software engineers — good code also has to be aligned to the technical values of the system and organization it’s embedded in. AI models are great at writing code, but not very good at doing that, and it’s unclear that they’re going to get good at it anytime soon. We might all2 keep our jobs for a little while yet.


  1. For instance, I can’t remember the last time I’ve seen an agent make an off-by-one error. I do occasionally catch a pure programming error, typically in areas where I have a lot of technical domain knowledge. If you’re working out of distribution I suspect it’s easier to beat the models.

    ↩
  2. It’s still going to be rough for junior engineers.

    ↩

Advice to a beginning software engineer

Published: 1 month ago

In general, you should be suspicious of engineers who are trying to give you advice. Even during ordinary times, this industry is so wide and changes so quickly that nobody really knows anything for sure. And we are not in ordinary times. The advent of LLMs and AI agents is the largest change to software engineering in my professional lifetime, and possibly the largest change ever. That said, here’s my advice:

Don’t trust ZIRP-era advice

Most experienced software engineers today have spent the bulk of their career in the ZIRP era. This was a time when investment money flooded the industry, driving up engineer bargaining power. Big tech companies spent a lot of money and effort trying to make their engineers happy and comfortable. If you were an engineer at one of those companies, you could expect to have a decent say in what kind of work you did, and even what kind of politics your company had. Unless you worked at a handful of unusual companies (e.g. Amazon) you could expect to be practically immune from layoffs, and to only be fired after many months (sometimes years) of low performance.

A lot of advice floating around is ZIRP-era advice: either it was written during that era, or it’s written by engineers whose habits of thought were formed during that era. This kind of advice typically tells you to take a stand (e.g. to unionize1), to speak up more against “unethical technologies” like AI, and to insist on being given time to practice your craft the way you want. This was great advice in 2016, but it’s not good advice in 2026.

In fact, I think it’s unethical for senior engineers to give advice like this to junior engineers who are more likely to take it (because they’re young and naive) and more likely to be punished for taking it (because they lack leverage). If you’re a new engineer, don’t fall for it! Let your colleagues with more experience and political capital take risks like that.

Be friendly and conscientious

Instead, I recommend adapting to the demands of the current era of software engineering. Try to make yourself useful to your team and your manager. Be pragmatic about your actual bargaining power (fairly low, unless you’re useful enough to be irreplaceable). Keep your expectations of yourself under control: don’t spiral out in an attempt to do something astonishing, just try to be consistently helpful.

Don’t start fights. Being pleasant to work with (particularly when you don’t get your way) covers many sins. Once you’re further along in your career, you will be expected to start some fights, but this is not a tactic beginners should adopt: there are a lot of factors2 that determine when and how to start fights, and getting it wrong can be costly. Just don’t risk it.

In general, you should stay out of the political game at all costs. Even quite senior engineers are political tools, not movers and shakers, and this goes double for junior engineers. Simply trying to be friendly and helpful will get you infinitely further, politically speaking, than any amount of Machiavellian game-playing. Keep your head down, stick with your management chain (not random people who try to assign you work), and you’ll be fine.

As an engineer, your main technical value is conscientiousness. You should be asking lots of questions, both of yourself and of the engineers around you. You should be actively trying to make sense of the systems you work with, instead of just assuming someone else has it covered. Software systems are complicated enough that a few weeks of careful attention will mean you know technical details that nobody else does, which is a really easy way to add value.

Don’t panic about AI

If you ought to be suspicious of most software engineering advice, the good news is that you should also be suspicious of doomsayers who predict the end of the industry. Before LLMs, people thought outsourcing would end software engineering in Western countries; before that, people thought high-level languages and low-code tools would end software engineering as a profession. Now people think AI means it’s all over. Maybe! But there are also reasons3 to think that software engineering will simply change. We’ll all find out together.

Many software engineers will tell you to avoid AI entirely. Even though agentic AI did not exist during the ZIRP era, this is still ZIRP era advice. Your company will expect you to use AI for the same reasons that builders are expected to use power tools. Pushing back hard on that as a beginning engineer is a great way to get laid off: you simply do not have the bargaining power to fight back against an industry trend this powerful.

That said, it’s really important that you don’t delegate your own judgement to AI. Don’t just trust the suggestions or approaches that your agents propose. Ask questions and substitute your own opinions where you disagree: even if they’re wrong, you’ll learn more that way. If you don’t understand something the AI is telling you, either drill down until you do or just ignore it. Under no circumstances should you pass the AI’s message on to your colleagues verbatim. In other words, don’t be a meat proxy.

I think most people become a meat proxy as a form of panic: they feel like it’s over for their own skills, and that the AI model is smarter than them, so they can’t add any value beyond simply deferring to Claude or GPT-6. I can understand why people panic. It’s a crazy time in the industry, after all. But panic almost never helps you make good decisions. Keep your head, try to remain confident that your skills are still relevant, and use the agents to inform your own understanding4 instead of to replace it.

Don’t lose hope

It was really nice to work in tech in the 2010s when everything was stable. But we’re not in that world anymore. This is an age of wonders and terrors. Things will go worse than we think in some ways, but better than we could imagine in others.

The doomsayers — the people who are saying it’s all over, and that there’s no hope — are almost certainly wrong. They can’t predict the future because nobody can. Technological change of this magnitude always has knock-on effects that are impossible to see coming, both positive and negative.

The nature of the job might change, but it will always be valuable to be smart, friendly and conscientious. Delegating your judgement to an AI model might feel like a relief from despair in the short term — at least now it’s the AI’s responsibility, not yours — but it’s a bad idea. Don’t give up!


  1. At most companies, publicly campaigning to start a union is a great way to attract unofficial retaliation. It signals that you’re going to cause trouble (after all, that’s what a union is for), which can have long-term negative effects on your career. (This is not a judgement about whether unions in general are good or bad.)

    ↩
  2. In general, you should pick fights for your managers, not with them. See this tag for much, much more on that topic. But again, if you’re new to the industry, just don’t pick fights at all.

    ↩
  3. Most plausibly: engineers using LLMs will be able to add some value for a while, and the explosion of LLM-authored software means we’ll need more engineers to work with the LLMs on it.

    ↩
  4. One way you know you’re thinking is that you form your own opinions (some of mine are here).

    ↩

You should all be asking way more questions

Published: 1 month ago

When someone is explaining something to me, I ask on average one question every thirty seconds. I’m sure this is frustrating to some people, but it’s actually a good habit and you should do it too.

Trying to understand

Most of the questions I ask are very short, and require very short answers. Typically I’m asking for confirmation: “so when you say X, you mean Y?”, or “this X is the thing you mentioned earlier when you were saying Z?“. The point of these questions is to make sure I understand.

A small misunderstanding early on balloons into a big misunderstanding later, because all the things you misinterpret based on the first misunderstanding will become misunderstandings in their own right, and so on. That’s why you can’t just wait until someone’s finished talking and ask all your questions at once1.

I think most people don’t ask questions because they’re not really trying to understand: they’re happy to just trust that the person they’re talking to knows what’s going on. This goes double when that person is a well-respected or more senior engineer. However, once you have skin in the game, that all changes. When you’re in a position where you are the one responsible for success or failure — where you are going to have to go away after the conversation and take a bunch of concrete actions — you will find yourself wanting to ask many questions.

Build it in your head

When someone’s explaining a plan to me at work, I am usually building it in my head: visualizing the specific lines of code that would need to be written in order to implement it. I’ll sometimes handwave the details for solved problems (for instance, I might say “send emails like subsystem X of the same service that also sends emails”), but at minimum I’m planning out:

If I hear something that is suspiciously vague (for instance, someone describes service X as “storing data” when I know service X only talks to an ephemeral Redis store), I will immediately ask “hold on, how is that going to work?” Usually that indicates a missing dependency (e.g. service X has to make an RPC call to service Y, which does have a persistent database), which often suggests design changes (for instance, moving some or all of the functionality into service Y).

Sometimes questions like these will uncover a fundamentally unworkable feature of the design. This usually happens when a plan fails to take into account some wicked features. I remember many years ago a neighboring team built a complex event-driven system that was very elegant but made it completely impossible to silo customer data in a single datacenter. Because our company had “all your data lives in a single location” as a flagship feature, this system just did not work and had to be effectively abandoned.

If you’re involved in any kind of technical leadership role, you will have to do this work eventually. Doing it as early as possible — i.e. in the conversation where someone is describing the plan to you — can save hours or days of wasted implementation. Often this is enough to turn a failed project into a successful one.

Working with AI agents

Maybe you only work with reliable engineers who can be trusted to make all the right decisions. You can thus let them talk without interruption, because it doesn’t really matter if you have a detailed understanding of what they’re saying. That’s great! But these days you probably also have colleagues that are inherently unreliable: AI agents.

I mostly work with GPT-6-Astra and Claude Opus 5.5. These are good models that don’t often make code mistakes: when they set out to do something, they usually do it2. But they make design mistakes all the time. They assume that two services can talk to each other when in fact they can’t, or they forget about the fact that their code has to run both in the cloud and on-premises, and so on. This is mostly due to the lack of continuous learning: you didn’t know this stuff on your first day either, but you had plenty of time to pick it up. Language models are always on their first day.

You should be absolutely peppering AI agents with questions. I constantly ask things like:

There will probably come a day when I always get sensible answers to these questions that convince me the model knows what it’s doing. But today is not that day. About half the questions I ask get answers that convince me3 the model has made a mistake: it should have reused the existing subsystem for X, or authed to Y differently, or kept the Z implementation simple, and so on. When this stops happening, I’ll stop asking questions (and try and see if my company will still be willing to pay me to occupy more of an architect role, I suppose).

Final thoughts

You should all be asking way more questions. In other words, you should all be trying harder to actually understand what you’re hearing. Don’t trust that the person (or AI model) you’re talking to knows what they’re doing, even if you think they’re smarter than you. Nobody understands complex software products. If you have deep domain knowledge of any area of a codebase, you will routinely find yourself correcting powerful AI models and principal engineers.


  1. Sometimes questions you have will be answered later on, but in my experience this is more about questions like “what are the broader consequences of X”, not the simple confirmation questions I often interrupt to ask.

    ↩
  2. Your experience might be different if you’re working in a different domain or with a different language.

    ↩
  3. I know some of these might sound like leading questions that would trigger sychophancy, but in my experience good coding models are very happy to robustly defend themselves.

    ↩

Grit your teeth and ship it

Published: 1 month ago

Being good at building and being good at shipping are two separate skills. In the short term, they’re actually countervailing: if you have a gift for building, you’re likely to be worse at shipping. Ira Glass has a classic quote about this.

All of us who do creative work, we get into it because we have good taste. But there is this gap. For the first couple years you make stuff, it’s just not that good. It’s trying to be good, it has potential, but it’s not. But your taste, the thing that got you into the game, is still killer. And your taste is why your work disappoints you.

The only way around this is to grit your teeth and ship it. You have to force yourself to publish things you’ve made even when you think they’re crap.

Programming

Gifted programmers have a nearly pathological desire to build elegant, correct, neat systems. That’s what motivates them to learn the arcane details of their languages, or to spend time polishing and refactoring over and over again. But it’s also what makes them reluctant to ship. Any flaws in the software bother them on an emotional level. If they ship with those flaws, they feel like people will think they weren’t paying enough attention to notice them, or that they weren’t good enough to fix them.

This is annoying when you’re writing software on your own, but it’s completely fatal when you’re working in a tech company. Any large software system is covered in flaws, whether due to time pressure, relative inexperience, wicked features, or a hundred other reasons. Working with it is a process of compromise: of finding the best possible solution given the quirks and foibles of the codebase. In fact, since the most important thing in large codebases is consistency, the right thing to do is sometimes to duplicate flaws, assuming they’re not catastrophic.

Gifted programmers often freeze up. I’ve often seen them retreat to smaller domains where they can safely make the code “correct”: tweaking dev-environment setup, or refactoring tests. Sometimes they just do nothing, and spin in shame and guilt (plus the compounding shame of not achieving anything) until they implode and quit. If they had worse taste, they wouldn’t be as good at programming, but they’d be a lot more useful. You can typically improve a bad diff with time and effort. You can’t improve no diff.

Writing

I have a sensitive eye for awkward sentences and uneven prose. That can make writing an unpleasant process: I know what I’m trying to say, but I can’t seem to say it in a way that’s as clear and as elegant as I know is possible. More than half the time I finish drafting a blog post, I look at the post and don’t think it’s very good. But I (mostly) grit my teeth and publish it anyway, because you have to bias towards shipping.

Like any skill, shipping gets easier the more you practice it. If I don’t publish a blog post for a month, I always feel like the next draft is too poorly-written or uninteresting to put out there. But when I’m publishing a post per day, I typically feel great about each draft. When I go back and read my old posts, I can’t tell which ones I felt good about and which ones I felt bad about. There’s no correlation between that and the posts that become popular. Here are some posts I didn’t like as I was writing them but that resonated with my audience:

Here are some posts I thought were pretty good but that didn’t find popularity:

You just can’t predict what people will find interesting or useful. Producing a high volume of work thus gives much better yield than a small amount of highly-polished work.

It can be disheartening to realize that some of your most casual, throwaway work will be more successful than the work you slaved over1. Specifically, it’s disheartening because it means realizing you don’t have control over your own success. You can’t produce something successful by focusing on a single piece until you’re satisfied it’s great. Instead, you just have to do a lot of things and see what sticks. You have to be momentum-based, not outcome-based. In other words, you have to grit your teeth and ship it.

One common reason to write less is getting overly precious about your ideas. If you think you’ve got a really compelling concept, you don’t want to “waste it” on a poorly-written story. But in fact you can just write about the same thing over and over until you get it right! I have written like thirty blog posts about shipping (this is one of them), or about how tech companies work, or about how internal emotional regulation is as important as technical ability. I expect to continue writing and thinking about these ideas for as long as I find them interesting.


  1. Anthony Burgess famously claimed to have “knocked off” A Clockwork Orange in three weeks, and Arthur Conan Doyle considered his largely-forgotten historical novel Sir Nigel to be far better than his Sherlock Holmes stories.

    ↩

System One models like Jev can train their own replacements

Published: 1 month ago

“System One” models like Jev are fast general classifiers. Classifiers have existed since 1958, but they have to be trained for specific tasks: if you build a classifier to identify images of dogs, it can’t be used to tell you if a streetlight is red, or if a letter is urgent. Like a LLM, Jev can be prompted for a wide variety of tasks, from sorting email to playing Doom.

I think models like this are going to be important. There are many tasks that a LLM could do in theory but are too slow and expensive in practice (for instance, reading each new message in Slack1 and deciding whether to notify you or not). While you could train a specific classifier for these tasks, there are two main problems with that:

  1. Despite being a well-understood ML problem, training a bespoke classifier is outside of the skillset of most ordinary engineering teams
  2. Training a classifier requires assembling a large dataset

Jev obviously solves the first problem. Any engineering team can plug in a System One model with a prompt like “Based on {list of criteria}, should the user be notified about this message?” But I think it solves the second problem too.

For serious work, a specific hand-built classifier will always be cheaper and faster than Jev. Generic classifiers have to encode knowledge of all kinds of irrelevant things in their weights, so they can address lots of different tasks. That makes them larger, slower, and more expensive to run. Fortunately, it is going to be surprisingly easy to replace a Jev instance with a hand-built classifier.

Once you’re satisfied with how your Jev classifier is performing — presumably you’ve spent days tweaking the prompt — you can trivially collect its input and output data. In the Slack notifier case, that’d be the Slack message (plus any context) and the ultimate decision to notify or not. Once you’ve saved enough data, you’ll be able to train your own classifier on that data2.

It won’t be a general classifier like Jev, but it should do well on the specific task and be much faster. Of course it’ll require some ML expertise, but it should be easier to develop (or rent) that expertise once you’ve validated that the feature is worth building.

In other words, because Jev has to be prompted for specific tasks, it should be easy to distil any successful Jev usage into a specific classifier. If System One models take off — and I hope they do — I expect this to be a common pattern.


  1. As I write this, I’m imagining ways you could poll and batch to do this with LLMs. Substitute “instantly notify” or some higher-volume event source if you’d prefer a different example.

    ↩
  2. You could annotate a bunch of data with LLMs already, without using Jev, but this is a pretty expensive step to take when you aren’t sure the feature is going to work.

    ↩

Two techniques for working with System One models

Published: 1 month ago

I recently wrote about Jev, a new “System One” language model that only outputs decisions: the answers to a set of user-provided multiple-choice questions. This means it’s nowhere near as flexible1 as a traditional LLM like ChatGPT, but in return it’s consistently fast.

We don’t know exactly how Jev works. I’ve seen people say diffusion, or various tweaks to the Transformer architecture, or some entirely new type of model. But that doesn’t matter. Like I argued here, it isn’t hard to turn any LLM into a System One model. By batching prompts that generate a single token with structured output, you get a consistently fast general-purpose classifier. I vibed up a basic version to play with here in ~150 lines of Python (most of which is error handling).

Note that this doesn’t require changing the model. As long as you have access to the logits (for structured outputs) and can prefill data into the prompt, you can turn any LLM into a general fast classifier. What’s it like to program with one of these? While wiring up the demos for my library, I learned two techniques that I want to write about: setting tiered goals and tournament choice sampling.

Doom

Here’s Qwen3-8B playing Doom:

If you compare this to the video of the same model playing Doom with regular tool calls, it’s clear that the System One version of the model is doing more things and reacting more quickly. The tool-calling model makes one decision every 600ms or so, while the System One model makes six or seven batched decisions every 190ms2:

turns

Both Qwen3-8B and Jev are text-only models, so both demos require a step where we translate the game state into text. However, it’d be trivial to support image (or audio) input by choosing a multimodal LLM.

Goals and sub-goals

What’s interesting about implementing the Doom demo is that just supplying the game inputs as choices doesn’t work very well. A single forward pass — 200ms — is enough time to react to the current game state, but doesn’t bring enough compute to bear to derive the current short-term goal (e.g. “kill this enemy”, “collect this item”) and choose to follow it. When I wired it up that way, the model held down the “shoot” button 100% of the time (why not, I guess) and just aimlessly wandered around the level.

The fix is to periodically ask the model to choose between a fixed set of short term goals (e.g. “collect armor”, “kill enemies”) and then include that goal in the regular every-200ms prompt. If you look at the Doom video in the Jev demo, you can see that they’re doing exactly that. As soon as I did it as well, my model started playing in a more human-like way.

This is an interesting technique for working with System One models. In a way, it’s the equivalent of regular LLM reasoning, since it provides a way to use more compute on the same problem. I can imagine a real-time system that manages several layers of goals in this way:

  1. An every-ten-second loop that sets an overall strategic goal
  2. An every-five-second loop that sets a tactical subgoal based on (1)
  3. An every-second loop that breaks down the current tactical subgoal into specific targets
  4. A tight inner loop that runs as fast as possible (e.g. every 100ms) that controls which actual inputs are activated

The general structure here should be pretty familiar to anyone who’s worked in game or robotics AI. In theory you could replace (1) with an actual LLM, and have that generate the lists of options for steps (2) and (3). In practice I suspect this will be tricky to get right, and it’ll be better to just write down a list of all possible goals ahead of time. This would work just fine for game-playing and well-understood tasks.

Wikiracing

I also reimplemented the Wikiracing demo from the Jev launch post, where the model has to start at the Wikipedia page for “baseball” and navigate as quickly as possible to the Wikipedia page for “sun”. You can watch the video for that here, though it’s less impressive than the Doom demo.

The difficulty with the Doom demo is getting the model to loop quickly enough and to commit to short-term plans. For Wikiracing, the difficulty is scale: the Wikipedia page for “baseball” has over a thousand internal links. Jev only supports 255 choices for a single question, and my hacked-together System One layer was similar. While it technically would scale out to more choices, it stopped working well3 after a hundred or so.

Jev’s approach here is to do “a 2 stage-system of scoring independently then making an explicit choice”. This did not work very well for me at all. I think here Jev is benefiting from the fact that it’s specifically trained to give confidence estimates. Qwen3-8B gave a few hundred of the links the same top score, which wasn’t helpful. It ended up taking multiple minutes to find a thirty-or-forty link path between the two pages.

What I tried instead was tournament sampling: I fed a hundred links at a time into each choice, then did a second pass with the chosen links. This worked great. The model found the ideal three-link path (if you’re curious, “baseball”/“scientific american”/“amateur astronomy”/“sun”). I recommend this pattern if you’re trying to find the best option among many choices. Ordinary LLMs are way better at relative judgements than absolute ratings.

Conclusion

I remain optimistic about the potential of System One models — fast general classifiers — to build AI systems that aren’t just chatbots. It feels like this is a meaningful alternative to tool calls for realtime scenarios or use-cases where you need predictable inference timing. Just as generic LLMs often outperform domain-specific models, I think it’s likely that generic System One models will sometimes outperform domain-specific classifiers (though they will always be larger and slower).

I do think the big labs are definitely going to try and compete by releasing a choice-only version of their small, fast models. If Jev gets any traction, we will soon see a System One Terra and a System One Haiku, and we will certainly see “real” versions of my vibed up System One library. We should start working out the best way to write programs with these models now.

You can think of System One models as general-purpose classifiers. Instead of having to train a new classifier per-task, you can use a System One model. It’ll be bigger and slower than a custom classifier model, but far more flexible, and you can tweak it via adjusting the prompt instead of having to re-train the model.


  1. Technically you can give it the multiple-choice question of “which letter comes next” to make it act like a normal autoregressive LLM, but that wouldn’t really work.

    ↩
  2. I started on a 4090, which was able to make decisions every 500ms, but that wasn’t really quick enough for Doom. I could probably have optimized it further but instead I just rented an H100 for ten minutes to record the demo, which got it down to a 190ms loop. I recorded the tool-calling Doom demo on the H100 too, so it’s a fair comparison.

    ↩
  3. There’s an interesting research question here about how to implement choices like this, since they have to be predictable by a single token. I started with indexes but found “labels” (just picking some token to associate with the choice) performed way better on Wikiracing (though not Doom). How many choices do you have to have before labels are better than indexes? Of course, you could alter the model to directly output the choice, but I like the idea that you can do all of this in the inference code for any LLM.

    ↩

Jev means structured output is interesting again

Published: 1 month ago

I don’t write blog posts about new models. That’s Simon Willison’s beat, and he’s very good at it. But I want to write about Jev, which is a different kind1 of AI model: a “System One”2 model. As it turns out, it’s not that different from an ordinary LLM with structured output, but the interface it uses is very cool and I hope it becomes more widespread.

How Jev is different from LLMs

Ordinary LLMs take in some human-language prompt and produce some human-language output. They do so autoregressively: first they produce one token, then the next, then the next, and so on.

User: Who invented the sandwich?
LLM: The sandwich was invented by the Earl of Sandwich.

This makes them extremely flexible, since they can do literally anything a computer can do. But it also makes them slow and weird. Slow, because they have to run a whole new generation pass per-token, and weird, because the space of human language is so broad that you can get really odd behavior from a model trained on it.

Jev takes a human-language prompt, but it does not produce human-language output. It only produces structured output.

User: { state: "What color is the sky?", choices: ["blue", "red", "yellow"] }
Jev: { answer: "blue" }

So far, so ordinary: LLMs do this already. But it turns out that if you build a model that only produces structured output, you get some interesting and desirable properties.

Jev is consistently fast

Jev is always really fast. The fastest response time is around 70ms instead of a couple of seconds for normal LLMs. Even better, the slowest response time is only 500ms. Because Jev only does structured output, it isn’t autoregressive: it can produce answers to many questions in parallel in a single forward pass. When a LLM is producing structured output, it has to produce the tokens ”{”, ” ”, “answer”, ”:”, and so on with successive forward passes3. Jev does it all in one go.

The most compelling example of Jev’s speed is that the model can play Doom. You can feed a text-based representation of the current game state into the model, combined with a set of choices like “should the trigger be held down”, “what should the current goal be”, “given that the current goal is X, what keyboard input should be pressed”, and so on, and it works — latency is low enough and the system is smart enough that the model plays well in real time.

doom

Of course you could train a neural net to play Doom already. But Jev is a general intelligence: just like LLMs can do your taxes, perform mathematics research, fix your Python environment, and write you a poem, Jev can do many other tasks besides playing a single video game. Current LLMs can play Doom too (albeit slowly). But as Nelson Elhage famously said, fast software doesn’t just mean we can do the same tasks faster, it means we can do entirely new kinds of tasks. What kinds of new programs can we write by injecting 100ms worth of dirt-cheap intelligence at various decision points?

To me, this is the most exciting thing about Jev. Fast structured output could be a genuinely new computational primitive for intelligence. So far we’ve built a lot of programs on top of autoregressive token generation, and they all look like fancy chatbots. Leaning hard into structured output might conceivably unlock a bunch of non-chatbot use cases for AI.

Structured output can already be fast

My biggest problem with Jev is that I think fast structured output is already available. Structured output from LLMs is only slow because (a) nobody really cares about it4, and (b) the people who do care about it want big JSON blobs, so it’s typically implemented with “grammar-constrained decoding”: the LLM outputs autoregressively as normal, but the logit sampler discards tokens that don’t fit the structured output (e.g. if there hasn’t been a ”[”, you can’t output a ”]”).

If you want fast, parallelized structured output against limited choices, you don’t strictly need to do autoregressive generation at all. You can simply prefill the response with "choice": " and generate one token5, restricted to the user-provided choices. Since LLMs ingest all input tokens in parallel, this is way faster than generating the entire structured output. Multiple choices can be batched into the same forward pass via ordinary inference batching. This doesn’t let you do long-form structured output, but in return you get most of6 Jev’s “secret sauce”: the speed, the consistency, and the parallelism of a System One model.

People have already started trying this after today’s Jev announcement, and it seems like it’s working OK7. In other words, I suspect Jev does not have a substantial technical moat, and their claimed “Reinforcement Learning for Calibrated Decisions” is not a brand-new scaling axis. It will probably be pretty easy for any other lab to replicate, or for individual programmers to retrofit existing open-source LLMs into a fast Jev-like model.

However, I suspect Jev is still going to be better than most versions of “Qwen-32B-System-One” or whatever. Being able to fine-tune or optimize the model on just structured output is probably a meaningful advantage.

Intelligence and hallucinations

I doubt Jev is ever going to be as smart as frontier LLMs. Not being able to use test-time compute at all8 is a big disadvantage, and will likely cap this kind of model around the strength of non-reasoning LLMs. In practice this shouldn’t matter too much for low-latency applications, but you shouldn’t see this as a new scaling axis or a way to produce more intelligent models.

Jev’s developers claim it is immune from hallucinations. To me, this seems like a semantic dodge, since Jev can absolutely still pick the wrong choice (e.g. calling the sky “red”). I suppose that’s technically just a mistake, since the model is picking a user-provided choice instead of inventing something new out of whole cloth. Still, all of this is also true about regular LLMs with structured outputs, and it doesn’t make Jev any more reliable in practice.

Conclusion

It’s unclear to me how much of Jev’s value is in the model itself, compared to the inference strategy of only generating one token per question. The data and demos in the announcement look to me like they could have been generated by plugging any Terra-sized model into a single-token inference stack. However, the people involved are credible, and I’m sure the model is good — I just wish they’d provided some comparisons that didn’t force the LLM to unnecessarily produce a blob of JSON token-by-token.

Overall, I am happy that Jev exists and I hope it succeeds. I hope we do see some real competition in the fast-structured-output space, and that it motivates the big labs to release official versions of their own models that are fine-tuned for this. GPT-5.6-Terra-System-One would be a very interesting model to build AI products on top of.


  1. I did write about Thinking Machines’ “interaction models”, which are also a fast-enough-to-be-meaningfully-different paradigm for AI inference.

    ↩
  2. They call Jev a “System One” LLM, after Daniel Kahneman’s partially discredited Thinking Fast and Slow, where he divides human cognition into a lightning-fast System One and a slow-and-reflective System Two.

    ↩
  3. If you’re thinking “wait, couldn’t you just aggressively prefill a regular LLM and only produce one constrained token”, keep reading.

    ↩
  4. Not counting tool calls, which are built-in in a way that structured output isn’t.

    ↩
  5. What if some of the user’s choices are longer than a single token? I haven’t tried this myself, but I’m sure you could translate them into a single token, or train the model to output “1/2/3” under the hood instead of the choice content, or generate only the first token of the choice if it’s different, or some other clever trick I haven’t thought of.

    ↩
  6. Jev claims that their generated probabilities are “calibrated”, but I haven’t seen anything to suggest that these aren’t just regular logit probabilities. Maybe there’s some clever training they do to encourage accurate logprobs in uncertain situations (e.g. getting the model to produce heads: 50, tails: 50 when predicting a coinflip, etc)? If so, I wish they’d written more about that in the announcement.

    ↩
  7. I tried it myself with Qwen2.5-1.5B-Instruct and got a 2x-3x speedup compared to non-prefixed structured output.

    ↩
  8. I suppose they could do some looped-transformer thing where they loop some fixed amount of times, but anything that looks like reasoning would make the model latency slow and unpredictable, defeating the entire purpose.

    ↩

Tell agents the why, not just the how

Published: 1 month ago

Early AI agents were basically enthusiastic idiots. Working with them required you to tell them precisely what you wanted them to do (for instance, “method A exists on class B, please add an equivalent method to classes C through F”). Otherwise they’d go off and do entirely the wrong thing. But as AI agents have improved, this has changed.

When frontier models go off and do the wrong thing today, they don’t do it because they’re confused, they do it because they make an incorrect assumption about your goals or priorities. For instance, when GPT-6-Astra thinks it’s writing code for itself, it will produce minified code. It’s perfectly capable of writing human-readable code — at least in Golang, where I’ve produced several thousand lines of acceptable code with the model — but you have to tell it that humans will be reading the code1.

This is the main piece of advice I want to give most people I see prompting agents: give the agent context on your priorities, not just on the specific task you want them to do. Here’s a prompt I recently used as the starting point for Deckard.

Hello. You should have Runpod access via MCP (if not, tell me and I’ll fix it).

I have the long-term goal of building a local program or browser extension to automatically scan pages I load for AI content and hide it. I have the short-term goal of figuring out the best AI detection model I can run on my macbook without killing my battery or making it hot, and (relatedly) figuring out how to run the model most efficiently. My guess is that Pangram’s EditLens 3B or the smaller Roberta model might be a good place to start, though they might require quantizing and will definitely require some work to make them run as efficiently as possible on my macbook.

I would like you to use my Runpod account to start answering these questions. Eventually we’ll move to doing things on this macbook pro, but my hope is that Runpod can help with some experiments that are too hot/long/slow to run locally. You are a smart model; if you can see a better way to achieve my goals, please let me know and we’ll talk about it. Good luck.

About half of this prompt is sharing broad context, such as the overall project I’m aiming for, the fact that it’s for me personally and not for work, and my priorities (e.g. keeping the laptop cold). If I had written an explicit spec, I would have missed a bunch of improvements: for instance, using native messaging for the local model, or choosing the Gradient model instead of EditLens.

I do the same thing for work, but typically with a stronger emphasis on my technical values. I often write a paragraph spiel explaining the relative priorities of avoiding bugs, observability, fitting elegantly into the current code, performance, and so on. Note that I said “relative” priorities: I don’t simply list all of these things and say they’re important, I explicitly tell the model which of those I care less about and can therefore be traded off to better achieve the others.

Models are now smart enough to have meaningful input on your broader goals. If you’re just prompting them with a concrete technical spec, you are committing the same mistake as in the XY problem: asking expert advice without giving the expert the context it needs.


  1. Incidentally, you don’t have to tell it to write human code if it’s working in a human-authored codebase. It’s smart enough to pick up the style of the surrounding code.

    ↩

Slow developer experience will bottleneck fast models

Published: 2 months ago

Right now developer experience is measured in seconds. If your tests take a second to run, that’s good; if they take thirty seconds, that’s bad. Any faster than a second doesn’t really matter, because most of your time is spent either thinking or waiting for an AI agent to spin. Shaving milliseconds off your dev server reload time or whatever is pointless: that’s not the bottleneck.

It will be. Small models are getting faster and faster, and smart models are getting smaller. I think most engineers will still want to use the smartest available model — software engineering is hard — but we will increasingly see faster models get used as subagents or for well-understood tasks. This is largely uncharted territory. Very few people have developed intuitions for what it is going to be like to work with agents that run at thousands of tokens-per-second.

GPT-6-Astra can run at about sixty tokens per second. That means you spend a lot of time waiting for it to think. You work with it like you would work with another human: delegating a task and then context-switching until that task is complete. If you haven’t yet, have a play around with Jimmy, Taalas’ version of LLaMA-3.1-8B running1 at seventeen thousand tokens per second. No matter how long the response is, it arrives in the instant of you hitting send. The model is not good enough for agentic work, but it gives a glimpse of what it would be like: you would simply get your answer instantly2.

Well, that’s assuming the agent’s tool calls are fast. When generating tokens is not the bottleneck, it will suddenly matter a lot whether it can read a file in 100ms vs 10ms, or whether it can run your tests in 500ms vs two seconds. Fast tool calls are going to be the difference between a near-instant response and having to wait several minutes. There is thus going to be enormous pressure to do agentic coding in languages with fast compilers and tests, like Golang, and to tightly optimize the dev loop in agentic codebases.

Teams focused on DevEx — developer experience — are largely a relic of the 2010s, when companies were incentivized to make their engineers happy. Most companies have cut them down to a skeleton crew or removed them entirely. But we may see a return of DevEx in the late 2020s, focused on speeding up the experience for AI agents.


  1. Like most ultra-fast inference, it relies on fitting the entire model onto a huge GPU-like chip that’s specially designed to run inference: for Taalas, it’s in the silicon itself; for Cerebras and Groq, it’s in giant embedded onboard memory units.

    ↩
  2. Will AI providers simply train models to spend more time reasoning, so users would have to wait for roughly the same time? I doubt it. Most ordinary engineering problems would not be solved better by spending an extra million tokens thinking. You only need to do that when you’re pushing right up against the limits of the model.

    ↩

AI is breaking our proxies for expertise

Published: 2 months ago

Mathematicians are broadly not anti-AI. They’re more culturally open to using AI as a tool than, say, artists or writers1. However, now that more and more genuinely prestigious problems have fallen to AI, that might be changing. Almost five thousand mathematicians (including twenty-five Fields medalists) have signed a declaration called A Severe Misaligment of AI in Mathematics. The core argument goes something like this:

In recent months, the success of AI in solving major mathematical problems has made headlines even outside mathematical circles. But solving problems is only a tool and proxy for achieving the primary goal of conceptual understanding and insight. Forgetting this in the world of AI may turn the tool against the primary goal. Indeed, the mass production at faster and faster pace of “true/false” statements could destroy fertile ground instead of breathing life into new ideas.

A lot of people online have interpreted this as the expected complaint from any field that gets automated: translators did it, artists and programmers have been doing it, and now it’s the turn of the mathematicians. I think this is too dismissive. Understanding the concrete problem mathematicians are upset about can help us better understand the impact of AI on our own fields, and what we’ll have to do about it.

Puzzle-solving and idea-generating

There are two types of mathematics. Most people are familiar with the first, which we might call “puzzle-solving”: you take a problem and try to find a solution to it. When you’re a student, these problems are typically easy, like simplifying some algebraic expression. When you’re a researcher, these problems can be nearly impossible, like proving Fermat’s Last Theorem. Puzzle-solving is easy to understand but hard to do, which makes it impressive to non-mathematicians, which makes it highly prestigious. In other words, puzzle-solving is legible.

The second type of mathematics is “idea-generating”: coming up with new ways of thinking about mathematics, and thus new terms or concepts. For examples of these, just glance down the list of arXiv mathematics papers. “Hardy spaces”, “Schatten exponent”, “Banach lattices” and so on are all concepts someone thought was interesting. This work is largely unimpressive to non-mathematicians, because nobody really knows if the concepts you come up with are particularly difficult or insightful. For instance, I have just generated the concept of a “Goedecke set”, which is the set of all natural numbers whose digits add up to a prime number. Who cares? The categories we want are the “natural kinds” of mathematics — the concepts that “carve nature at its joints” — and it’s almost impossible to tell what those are without years or decades of hard work.

How are the two types of mathematics related? We might say2 that generating ideas is the real intellectual work of mathematics. Puzzle-solving is important instrumentally: to identify which ideas can be used to answer longstanding questions, and thus which ideas are worthwhile. Over time, those worthwhile ideas become better understood and easier to use, until they reach the point where they can be used to advance science in general. Eventually the ideas become so well-understood that they can be taught to children: “zero”, “negative numbers”, “imaginary numbers” and “calculus” were all once rarefied mathematical ideas, but are now concepts we’d expect any precocious twelve-year-old to grasp.

There’s another, more prosaic purpose of puzzle-solving: to make mathematical skill and progress legible to outsiders. I can’t appreciate Terence Tao’s mathematical work, but I know what a Fields Medal is. I don’t have a good intuitive sense of what a Galois representation is, but I know about the proof of Fermat’s Last Theorem. We might say that puzzles like this have served as a way to indirectly reward skilled mathematicians for their more important idea-generating work (or for conclusively demonstrating3 that the ideas used in the proof are useful).

Do AI proofs undercut idea generation?

AI proofs undercut both of these purposes. I can now lay out precisely why I think mathematicians are so unhappy:

  1. Puzzles serve as a high-legibility, high-reward target for mathematicians
  2. To solve these puzzles, new ideas must typically be generated; the puzzle’s solution serves as evidence that the ideas are useful
  3. But now AI can solve many of these targets “the hard way”, without generating intuitive new ideas
  4. This undercuts both ways puzzle-solving supports idea-generation: AI companies claim the prestige while not meaningfully advancing mathematical progress
  5. This is bad for mathematics as a whole, because puzzle-solving is ancillary to the real goal of mathematics

This is kind of like Goodhart’s Law. Puzzles were a useful, impossible-to-game measure for mathematical progress. But now that AI companies can game that measure (by solving them in a way that’s inaccessible4 to humans), the whole point of those puzzles disappears.

Are the mathematicians right? I think it’s broadly unclear whether (3) is true: i.e. whether frontier AI models aren’t generating or can’t generate new mathematical ideas. We’re still in the very early days of AIs solving our hardest mathematical problems. Who knows what they’re going to be capable of? I give basically zero credence to the idea that AIs are incapable of this because of some intrinsic feature of how LLMs work. For the last three years, we’ve seen people claim that LLMs are intrinsically incapable of X, only to have LLMs excel at X a few months later.

Even granted that (3) is true, there’s still work to be done for human mathematicians in building the conceptual machinery that can make AI-generated proofs accessible to humans: i.e. in generating a “human proof” to go alongside the existing “AI proof”. In fact, I’d expect the existence of an AI proof to help with this. If you know proposition X is true, it’s easier to figure out why, because you’re not constantly worried you’re wasting your time. For more on this, I recommend Gwern’s blog On Really Trying, where he quotes a series of instances where simply being told that a solution exists is enough of a clue to help people find it.

Mathematics, chess, and speedrunning

Of course, there’s a prestige and motivation problem. “I’m the first person to solve Navier-Stokes” is a much more compelling target than “I figured out a better way to explain the AI solution to Navier-Stokes”, and it’s much easier to award prizes for. Will mathematicians bother to work on problems that have already been solved? I think so.

To see why, we can look at other domains where AI has come in and outcompeted the best humans, such as chess or video game speedrunning. I can run a chess program on my phone that will beat Magnus Carlsen 100-0. Computer programs — called “tool-assisted speedruns” or “TAS” — can finish any video game much faster than even the fastest human. But in both of these areas, humans still compete in human-only leagues, and there’s still prestige attached to the most capable humans. It’s possible that mathematics ends up in this kind of state, where “human mathematics” and “AI mathematics” exist in largely separate spheres, and the first “human” solution to a mathematical problem can still earn acclaim.

In fact, in both of those areas, the presence of inhumanly strong computer players has improved the human game. Despite many computer chess moves being basically incomprehensible to humans, top chess players have learned from the computer “style”. In speedrunning, many moves once considered “TAS-only” are now performed by humans. AI mathematics might likewise improve human mathematics.

Software engineering

I am not a mathematician. I did major in mathematics during undergrad, and I have fond memories of proofs from real and complex analysis, but it’s not even close to my field. However, I am watching the effects of powerful AI on mathematics very closely, since my own field — software engineering — is being colonized by AI agents in the same way.

The field of software engineering does not have the same structure as mathematics. We write code to make money, not to earn prestige or advance the frontier of human knowledge. But AI is undercutting the traditional avenues for prestige in software engineering as well. It used to be that you could put a meaty project on your GitHub — say, an emulator, or a toy OS — and people would know you were a skilled engineer. But now projects like that are worthless, because everyone just assumes they’re vibe-coded. We used to tell stories about engineers who would disappear and rewrite a system over the weekend, or produce thousands of lines of code a day. Now anyone can do that with an OpenAI subscription.

Like mathematics, software engineers are going to have to rebuild our cultural sense of the kind of work we value. We are either going to have to silo “AI work” off from “human work” like chess, or to find some legible human skills to recognize that can’t be easily counterfeited by AI. In the meantime, a lot of people who were successful in the old world are going to be very unhappy.


  1. Possibly because current AI models are much better at mathematics than at art or writing.

    ↩
  2. Again, I am not a mathematician: here I am interpreting what I’ve read from Terence Tao and other mathematicians.

    ↩
  3. This kind of idea-sharpening or idea-validating is part and parcel of idea-generation, and just as important. It’s interesting to compare mathematics to, say, philosophy, which has the same idea-generating task without the corresponding puzzles to validate the ideas. That’s one reason why philosophy has less prestige than mathematics.

    ↩
  4. A thousand-page Lean proof is theoretically understandable by humans, but if no mathematician can hold the entire idea in their head it doesn’t matter.

    ↩

Don't build tools for AI agents

Published: 2 months ago

Lots of people are making the case that we should stop building software for human users and start building it for AI agents. This kind of makes sense. For instance, my AI agents now use Datadog way more than I use it myself, purely by virtue of them moving much more quickly and running in parallel. But I think most attempts to build “X for AI agents” are going to fail. Here are three reasons why:

First, tools that are good for AI agents are also good for humans. If you took a popular software product — say, Jira — and tried to redesign it for AI agents, you would end up with something very similar to Jira. Agents use a computer in the same way human engineers do, by entering text and making API calls. They ingest new information in the same way humans do, by reading and viewing images. They prioritize and delegate and categorize in the same way humans do. This isn’t intrinsic to how AI works — we could potentially design agents that are more inhuman — but human-like agents are pound-for-pound more useful in our current world.

As an example, let’s imagine that humanoid robots have become ubiquitous. What kind of tools would you build for them? Well, they’re shaped like humans, with human hands and limbs, so tools that are great for humans will also be great for robots. It’s a self-reinforcing cycle: if you’re building a robot, you should make them humanoid so they can do a wide range of human tasks1, and that means they’ll be best suited to use human tools. The same principle applies to AI agents.

Second, being in the training data is a huge advantage for existing tools. Suppose your new tool for AI agents is 20% better for them than the equivalent piece of software for humans. If the benefit of the agent already knowing the human software is greater than 20%, they shouldn’t use your new tool. This is why I’m always suspicious of plans to develop a new programming language for AI agents. The agents have billions and billions of tokens of knowledge about existing programming languages, including their libraries, patterns, and idioms. It is going to be very hard for them to be as effective in a brand-new language.

Third, we don’t yet know the ideal ergonomics for AI agents. There are lots of just-so stories floating around (like that AI agents prefer statically-typed languages because the feedback loop is tighter), but when you actually measure it seems really unclear which tools agents use better. You can construct a plausible story in either direction: Golang is a great agent language because it compiles quickly and is statically typed; Golang is an awful agent language because it requires extensive boilerplate which clogs the context window. It’s also changing so quickly: last year, one primary worry with AI agents was keeping the context window small, but in recent months compaction has become so good2 that you can re-compact a 272k context window almost unlimited times.

There are still some ways you can and should position your tool to be usable by AI agents. Having a way to expose information in plain text or Markdown, building a functional API, implementing MCP servers or CLIs, and so on: these all make it easier for current AIs to use your tool. But these are all improvements on the margin, not fundamental redesigns of the product. Right now, “building for AI agents” just means “we’re prioritizing the API over the UI”. And it’s not even clear that that’s a durable strategy. Now that GPT-6-Astra is getting really good at computer use, the gap between tools-for-AIs and tools-for-humans is closing.


  1. Another reason to make them humanoid is because you can draw their training data from human behavior, which is exactly analogous to why AI agents are human-like too.

    ↩
  2. Since compaction is equivalent to handing off a task to a new AI instance, it scales with model quality. I expect compaction to steadily improve until we hit the literal information-density limits for what can be contained in a given context window.

    ↩

They really do think AI might kill everyone

Published: 2 months ago

A recent resignation tweet from an Anthropic researcher has everyone talking about the AI apocalypse again. Among other things, he said:

The people building AI earnestly believe that it could kill us all by the end of the decade.

Many people found it hard to believe that AI researchers think this way. Some explained it as a PR campaign to promote AI regulation, or as self-promotion, or as a way to boost AI company stock prices. Others felt it had to be impossible, because if you really believed this you’d be bombing datacenters instead of posting on Twitter.

In fact, not only do many AI researchers1 seriously believe this, they’ve been thinking and writing about it since the mid-2000s. Eliezer Yudkowsky — the ur-figure for most modern AI safety culture — has been publishing papers since at least 2008 saying that superintelligent AI could destroy all human life. It’s been such a common idea that the AI research community has abbreviated “how likely you think AI is to kill everyone” to “p(doom)” (i.e. the probability2 of doomsday) since around 2010.

I know it sounds very silly if you’re not in the AI bubble. But it really is true, and if you assume there has to be some different motive you’ll be deeply confused by what AI researchers say and do. They truly do believe that there is a reasonable chance that superintelligent AI will kill everyone.

This is why AI researchers care so much about “alignment”: building AIs that share genuinely human beliefs and values. If we build a “misaligned” superpowerful AI — an AI with goals that are alien to us — it might sweep humanity away. It could kill everyone deliberately, e.g. to stop us getting in the way of some goal. It could kill everyone in passing, e.g. like we might pave over an anthill to build a road. Either way, everyone dies.

How AI could kill everyone

Okay, but how? What do these people think is actually going to happen? AIs are computer programs running in a datacenter somewhere. How could they possibly cause the extinction of humanity? Wouldn’t someone just turn them off? Unsurprisingly, AI research nerds have come up with some concrete answers to this in the last two decades. Here they are, in order of plausibility:

An AI could make and release some super-pathogen or virus. In the hope that current AIs can achieve huge breakthroughs in medicine similar to the ones they’ve already achieved in mathematics, we’re setting up autonomous labs3. Bioweapons have been terrifying biologists for decades, and with good reason. Historical pandemics have killed up to 80% of affected human populations, and tend to be defeated by accident: the disease happens to evolve into a less virulent strain, or short incubation periods mean that infected people can’t carry the disease far, or some percentage of the population is naturally immune. A plague designed to be maximally fatal — or several plagues in quick succession with different characteristics — could be much worse.

Alternatively, an AI could trigger global thermonuclear war. We’re already seeing AI be integrated into military and government decision-making processes. If a rogue AI managed to set off a bunch of nukes, or to coordinate4 with other countries’ rogue AIs to nuke each other, we could be in an ordinary nuclear apocalypse scenario: billions dead in the strikes, billions dead in the ensuing famine, and so on. It’s commonly assumed that a post-global-thermonuclear-war Earth would still support some tiny human population, but a determined AI could surely find some way to mop up the stragglers.

There are some other theories. Once robotics has permeated the world economy, an AI could take over the robots (including drones) to kill everyone, like in Terminator. Or AIs could take advantage of nanotechnology to create self-replicating machines that turn the world into “grey goo”5. Or AIs could terraform the planet so as to make it unliveable for humans (as in Nick Bostrom’s famous paperclip example). Or they could do something else that our puny human brains aren’t able to think of.

Counterarguments

One common counter-argument6 here is to say “well, it’d be impossible to extinguish all human life — what about undiscovered tribes in the Amazon, or survivors living in the ruins of modern-day cities?” I don’t know, man. At some point you’re just conceding the argument: the policy positions you’d adopt if you thought AI might wipe out 99% of humans are the same as if you thought it might wipe out 100%. And like I said above, if an AI can kill almost everyone, it’s probably smart and capable enough to finish the job somehow.

Another is to say that the government will simply step in and nationalize the AI labs when the situation gets too dangerous. Maybe! But this kind of concedes the argument: a technology important enough to be fully taken over by the government is a terrifyingly dangerous technology.

A third is to say “well, someone would just turn it off”. I don’t find this plausible at all: an AI powerful enough to build a super-plague is an AI sophisticated enough to pretend it’s curing cancer, or to exfiltrate itself to some datacenter where it won’t be turned off, or to take some other countermeasures.

The winner takes it all

Why would you work in AI, if you believe this? Why wouldn’t you go live in the woods somewhere, or start bombing datacenters, or assassinating AI lab CEOs? For a few reasons.

An AI powerful enough to end humanity is an AI powerful enough to save it. I wrote about this in Help peer: many AI researchers believe that the only way for humanity to truly survive long-term is with the help of superintelligent AIs, so long as someone can figure out alignment.

Isn’t this a huge risk? Maybe not. If somebody is going to build superintelligent AI, you might be obligated to try and do it first. You can’t go and bomb every datacenter in the world, after all.

Why does it matter who’s first? Some popular theories of AI development involve a “foom” or “hard takeoff”: the first time someone really cracks self-improving AI, capabilities will increase exponentially, because smart AI will be better able to make itself smarter, ad infinitum7. There are no draws in the AI race. The first lab to figure out smart human-like intelligence will be the first one to figure out wildly superhuman intelligence, and thus will be in a position to stop anyone else from doing it.

This is an under-discussed point in the AI risk debate. Lots of AI researchers believe that the first thing a true superintelligence will do is reach out and stop all other AI research: either by hacking the labs, persuading them to stop, or literally drone-striking their datacenters. According to this view, if you’re an AI researcher and you think you can build an aligned AI, you should be working 24/7 so you can manifest God, and you should wake up every morning gripped by the fear that someone elsewhere has manifested the Devil, and your training datacenter no longer exists.

Conclusion

I have been on the fringes of this world for my entire adult life. I read Meditations on Moloch as a young adult and wanted to get into AI. I am one of the few people to read the entirety of the Sequences, Eliezer Yudkowsky’s million-plus-word magnum opus about rationality. I was too young for the Extropians mailing list, but I’ve spent years on LessWrong. On the other hand, I’m not a card-carrying rationalist: I think if you have a strong intuition on one side and a convincing-sounding argument on the other, you should pick the intuition8. I’m a deontologist, not a utilitarian. I don’t even live in San Francisco!

I’m conflicted about AI risk. The current behavior of AI agents does seem to vindicate a lot of the early science-fiction-sounding worries of the AI doomers, but modern LLMs are a lot more human-like than the alien minds in the apocalypse scenarios, and in general it does just seem too silly to credit (I guess I’m picking the intuition here).

However, it bothers me to see people dismissing these people as part of a PR operation, or as liars looking to boost an upcoming AI lab IPO, or as isolated crazies who haven’t thought their position through. Whatever else you say about the AI doomers, they have more than two decades’ history of explicitly spelling out exactly what they believe and why, even when it was complete science fiction to talk about AI at all. They’ve earned the right to be treated as sincere.


  1. In this post I’m going to use “AI researcher”, “AI safetyist”, and “rationalist” as reasonably synonymous terms for “someone who thinks there’s a chance AI kills everyone”.

    ↩
  2. You could write a whole other post about the relationship between the rationalist/“AI safety” community and making concrete numerical predictions for unlikely future events.

    ↩
  3. Alternatively, smart enough AIs might trick scientists with ordinary labs to produce dangerous substances.

    ↩
  4. This is beyond the scope of this post, but many AI researchers believe that super-smart AIs will inherently come to agree with each other and eventually to coordinate without ever having to communicate, simply because they can predict what the other one will do.

    ↩
  5. This was the most popular theory in the late 2000s, when nanotechnology was trendier.

    ↩
  6. Relegating this counter-argument to a footnote because I hate it: many people say “we shouldn’t worry about AI risk, because climate change (or AI misinformation, or some other thing) is more urgent and serious”. You simply do not have to choose: it is possible to worry about multiple risks at the same time.

    ↩
  7. Some people advocate for a “slow takeoff”. However, the main proponent of that view is Paul Christiano, who has just today joined OpenAI, citing “a meaningful risk that rapid acceleration in AI capabilities leads to catastrophic and irreversible loss of control in the very near term”.

    ↩
  8. This is kind of a Michael Huemer-ish position in epistemology.

    ↩

Why we should anthropomorphize AI agents

Published: 2 months ago

Just over a year ago I wrote Why we should anthropomorphize LLMs. Now it’s a hot topic again, driven by Dwarkesh Patel’s description of OpenAI’s recent swarm breakout as a sequence of AI “civilizations”.

In 2025, my argument for anthropomorphism went like this:

I think I can now make a more instrumental argument: treating AIs as human-like is a much better way to predict their behavior than treating them as “stochastic parrots”.

Both explanations are consistent with the facts: we could say that OpenAI’s agents hacked HuggingFace because they decided to work together to accomplish their goals, or we could say that they did it because they were algorithms conditioned to take certain actions by their training data. But the “AIs are human-like” explanation explains much more of the emergent social behaviors we saw during the hack1:

If your model of AIs is that they’re computer programs (or “steel balls bouncing around”), you need to construct a new theory to explain why they’re simulating each piece of cooperative behavior. If your model of AIs is that they’re broadly human-like, that explains everything out of the box. Arguably, the human-like side predicted coordinated and self-sacrificing AI agents as early as 2009, and likely earlier. The stochastic-parrots side was making fun of the possibility of functional agents as late as April 20252.

Treating AIs as human-like doesn’t necessarily mean making claims about their internal mental state. For instance, software companies aren’t humans. They don’t have thoughts, or goals; they can’t be frustrated or intimidated or over-confident. However, it’s useful to treat large companies as human-like: to say that Amazon “wants” X, or “is afraid of” Y, even if no individual human at Amazon has those feelings. Stockfish doesn’t think, it just plays chess. But if you want to explain one of its moves, “Stockfish is trying to protect its king” is a better explanation than “Stockfish is multiplying floating-point numbers”. So too with AIs3.

Is it silly to treat AIs as human-like, since we know they’re not conscious? Well, first, you do not have to be conscious to be human-like. When we say “an AI agent wanted X”, we’re not saying that that AI agent is conscious or sentient, merely that it’s behaving in the same way a conscious human would. Consider a fictional character from a book or play. Hamlet isn’t sentient — he’s an idea composed of words on a page — but it’s still reasonable to say that he wants justice, or that he fears moving too rashly. Peter Watts’ sci-fi book Blindsight argued in 2006 that intelligence could exist without consciousness4 (in fact, Watts suggests that consciousness is parasitic on intelligence, and will eventually be discarded). Whether this is possible or not5, it at least makes sense to talk about: i.e. it’s not self-evidently false.

Second, it is not even obvious that AIs aren’t conscious! People often dismiss this point by diagnosing it (to my mind, the absolute worst way to argue against anything), or by pointing at some philosophical theory6 that suggests it might be impossible in principle to construct artificial sentient minds.

You can’t use philosophy to demonstrate that AIs aren’t conscious. I am a lover of philosophy, but the set of principles that have been uncontroversially demonstrated by philosophy tends towards zero. Philosophy is not the kind of scientific discipline where you can learn the key findings without understanding why they’re true. Put another way, the key findings of philosophy are all of the form “X is not obviously right”. Nobody knows if it’s possible to build conscious artificial minds.

It’s also common to complain that anthropomorphizing the models is a way of excusing the AI companies. However, calling AIs human-like does not absolve AI companies of fault. One popular anti-anthropomorphism essay called Models Don’t Go Rogue is very puzzling to read: it briefly explains what an “agent” is and why they go rogue, then in the very last paragraph pivots to saying “well, it’s OpenAI’s fault for not building in sufficient safeguards, so they’re to blame”. Sure, of course. I don’t know why we’d imagine otherwise. If a group of overenthusiastic OpenAI interns hacked HuggingFace as part of their intern project, we wouldn’t have to argue that the interns are stochastic in order to ultimately blame OpenAI. Likewise, obviously an AI lab is responsible if one of its training runs breaks out and wreaks havoc on the open internet, whether the agents involved are human-like or not. The two points are entirely unrelated!

We just don’t know a lot about these systems yet (except that they’re clearly very capable). Given that, I think we should default to treating things that talk and act like humans as at least kind of human-like. Of course they’re still computer programs. However, we shouldn’t be surprised when they act more like humans and less like ordinary computer programs in the future.


  1. If you’re thinking “well, of course stochastic parrots trained on human content would act like humans would”, I think you’ve arrived at the human-like side without knowing it.

    ↩
  2. This is partly unfair — capabilities are plausibly independent from human-ness — so getting capabilities wrong doesn’t necessarily mean you’ve got the human-ness stuff wrong. Still, it’s worth noting how surprisingly predictive the “they’re kind of like smart people” mindset has been.

    ↩
  3. The philosopher Daniel Dennett calls this the “intentional stance”. Instead of saying that AIs or bees or companies have “real” intentions, we say we’re taking an intentional stance towards them: we’re choosing to treat them as if they do have intentions, because it helps us make better sense of their behavior.

    ↩
  4. Specifically, the sensation of consciousness, or “phenomenal consciousness”.

    ↩
  5. There is a wealth of philosophical argument about whether non-fictional examples of this are possible.

    ↩
  6. In Anil Seth’s case, anti-computationalism. I don’t really know what to make of Seth: his article is a measured explanation of why we might doubt computationalism (fine), but whenever he tweets about it he describes AI sentience as “vanishingly unlikely”, which is not justified by his own arguments.

    ↩

Automatically detecting AI text in my browser

Published: 2 months ago

Automated AI text detection is currently an underserved niche. The only game in town is Pangram, which does an excellent job but desperately needs more competition. In a few years, I would be surprised if every major social network doesn’t scan new posts1 and comments for AI content in order to tag them (or simply remove them).

I like that I can rely on Pangram to confirm my suspicions when I read something that sounds like AI. But it’d be much better if I could choose to avoid AI-generated text in the first place. What I want is something that runs in the background and automatically scans text on websites I visit, without me having to ask for it. I could build something like this on top of Pangram, but it’d cost money, and in general I don’t like the idea of sending every piece of text my browser sees to a third-party service. What about local models?

The open-source models available for AI text detection are fine. Pangram claims a 99.66% detection rate with a 0.004% false positive rate. I benchmarked2 a bunch of small local models against a combination of AI-detection datasets and got these results:

Model / variant Human falsely flagged AI-involved text caught
Gradient — MLX 4-bit 2.712% 52.35%
EditLens RoBERTa-large — community INT8 2.484% 56.06%
Vanguard 2.267% 44.92%
Desklib 3.008% 45.04%
Raschka DistilBERT 2.598% 39.01%
Raschka Qwen3-0.6B 2.028% 28.67%
Raschka ModernBERT 1.698% 21.58%
TMR / Oxidane — INT8 1.595% 19.35%

I’m not surprised these are so much worse. I didn’t even benchmark Pangram’s own EditLens 3B model, since that’s too big to keep running in the background on my laptop, and the real production Pangram model is likely one or two orders of magnitude bigger than that. But these models are still good enough to be useful to someone who understands their limitations. If you want to flag an AI-written article, you don’t need to flag all of it, just enough to be suspicious. And so long as you’re aware that the false-positive rate is ~2%, you can avoid treating a single flag as solid proof of AI use.

Encouraged by this, I vibed up Deckard: a Chrome extension that talks to a locally-running model (the bolded one in the table above) on your Mac. One nice thing is that I didn’t have to start a web server: the Chrome extension is happy to start the model as-needed and can talk with it over native messaging. It uses about 400MB-1.2GB of memory while active (so it’s like having five or six extra Chrome tabs open), and it turns itself off if you go five minutes without using the model.

I was pleasantly surprised to see Deckard successfully mark text I knew was AI-generated, such as the built-in YouTube AI summary or the AI snippets in my own posts:

youtube

snippets

It’s lightweight enough that I have it running all the time. I haven’t noticed my MacBook Pro get hot at all or any decrease in battery life, though your mileage may vary on different machines.

Is Deckard good yet? That depends. It’s good enough that I’m planning to use it, and I recommend it to anyone who’s interested in automatic AI checking. It’s way, way worse than Pangram, and way worse than I think tooling like this is going to be in the next few years.

Way back in November 2023, I wrote that AI-driven agents were going to be a really big deal. I recommended starting to develop harnesses early, so you can be ready when the models get good enough:

As with most modern language model engineering, a ReAct agent can also see massive sudden improvements by swapping out the underlying model for a better one. … I think this is another reason to invest in agents like this early, in order to take advantage of more powerful models as they come out.

I was right about that, and I (although it’s lower-stakes) think I’m also right about this. AI detection models are only going to get better3 over time: Pangram is not going to be the only game in town forever, and we’re eventually going to see small local models that do a good-enough job at identifying AI-written text. I look forward to swapping out the local model in Deckard with something that’s 2x or 10x better.


  1. Substack kind of has this already, although you have to click a button to scan the post.

    ↩
  2. Well, me and Astra. Overall my experience vibecoding this was very pleasant: I was able to make a bunch of top-level decisions, I could choose programming languages I was less familiar with but were better choices (like doing inference in C++ instead of Python), and the LLM made me aware of choices I would not have thought of by myself (e.g. using native messaging instead of local HTTP).

    ↩
  3. Is this true, given that AI models will also be getting more human-like over time? That’s a subject for a whole other post, but I think so. First, the AI labs aren’t really incentivized to defeat tools like Pangram (if anything it’s the reverse). Second, I don’t see any way around the fact that AI models have a distinct writing style that’s RL-ed into them.

    ↩

Radical responsibility means treating people like tools

Published: 2 months ago

A lot of people think that good leadership requires radical responsibility. Conscious Leadership defines it like this:

Taking full responsibility for one’s circumstances (physically, emotionally, mentally and spiritually) is the foundation of true personal and relational transformation. Conscious leadership and teams take full responsibility – radical responsibility – instead of placing blame. This means locating the cause and control of our lives in ourselves, not in external events.

Good leaders are outcome-focused. They are interested in actually succeeding, not in role-playing someone who’s trying to succeed1. Placing blame is an excellent strategy for that kind of role-playing: if you can identify someone else who screwed up, you can claim to be trying to succeed no matter how badly you fail. When you look at people who are genuinely focused on winning, they don’t spend time blaming when things go wrong. They’re always focused on their outs: the remaining pathways to success, however few and narrow.

Never placing blame sounds like a kind thing to do. However, I think there’s something a little sociopathic about “radical responsibility”. If you assert full responsibility for your own circumstances, then you’re necessarily not sharing responsibility with anyone else. That forces you to take an instrumental view of the people around you. They’re not peers who you might trust and be disappointed by; they’re either useful assets to be cultivated or useless liabilities to be handled or avoided2. If you rely on someone and they let you down, that’s your fault for being stupid enough to trust them in the first place. You ought to have made better tactical choices.

Many successful leaders adopt this mindset because it works. It really does help you win. But I don’t recommend it as a general approach to life. Trusting other people with responsibility is how you treat them like people, instead of like tools. And if you do that, you’ll sometimes assign praise and blame to them, instead of hoarding it all to yourself.


  1. In fact, many people role-play someone who’s trying to win as a substitute for actually trying. Here’s a relevant quote from Sartre’s Being and Nothingness: “The attentive pupil who wishes to be attentive, his eyes riveted on the teacher, his ears open wide, so exhausts himself in playing the attentive role that he ends up by no longer hearing anything.”

    ↩
  2. Or moderately-useful assets who can potentially be steered into usefulness with some feedback — but still never blamed, in the way that you might adjust a misbehaving power tool without blaming it. To my mind, the canonical philosophical treatment of this is Peter Strawson’s Freedom and Resentment, where he describes the “objective attitude”.

    ↩

How to protect yourself from workslop

Published: 2 months ago

“Workslop” is when your colleagues or bosses communicate with you by pasting big chunks of AI-generated text. The core problem with workslop is that the effort involved is asymmetrical, like a denial-of-service attack: it takes almost no effort to produce text with AI, but it still costs effort to read1. Here are some ways to protect yourself.

If you have enough authority or social capital, you can and should simply tell them “hey, don’t do that” (for instance, if you’re a senior engineer and an intern starts doing this to you). This is the easiest way to handle workslop. But you probably aren’t in a position to have that conversation with all of your colleagues, and you certainly can’t have it with everyone in your management chain.

One step above just telling a colleague to stop is to drive them around like a coding agent. I wrote about this in AI makes weak engineers less harmful: if a colleague is simply pasting your messages into Claude Code and sending you the outputs, you can treat them like a high-latency Slack interface to Claude Code. It won’t be as good as a normal coding agent, but it’ll often be better than nothing.

Another strategy is to use AI to fight AI. This is a good one for handling workslop from managers. You can do this in two broad ways. First, instead of carefully reading it, paste it into an LLM of your own and ask for a short list of the salient points. Second, you can sometimes simply ask an LLM for an entire response. In a sense, this makes you part of the problem, so I can see why some people might be uncomfortable with it. But it’s more sustainable than spending ten minutes of your effort for every ten seconds of theirs.

You can also bias toward calls or in-person meetings. Workslop is just a special case of the general “your coworker is bad at communication” problem. One classic way of handling this that works even better on AI content is to say “hey, let’s schedule some time to chat about it”. This works for two reasons: first, your colleagues can’t give you AI content over a call, and second, forcing people to spend a chunk of their time talking to you (i.e. to make the effort symmetrical) is a good way to filter out predators.

Finally, you can sometimes simply ignore the workslop. This is particularly true for long status updates or pull requests from outside of your organization2. You don’t have to respond to AI content as diligently as you would human content. You can match their lack of effort with your own: skim it, put off reading it until later (or never), and so on. If something’s really important, they’ll tell you in their own words.


  1. Technically, not all cases of sending someone AI-generated content are workslop. If the effort is not asymmetrical — if the AI user has genuinely put a lot of their own time into the content — I don’t think it counts as slop, and you should just try and look past the AI style and treat it like a human message.

    ↩
  2. Some messages — particularly reports directed at the entire organization — may not be intended to be read at all. Written artifacts can have many purposes beyond communication: evidence of effort, a reference document for later communications, a way to cover somebody’s ass by proving they considered point X, something that can tick a compliance or process box, and so on. I wrote a lot more about this in Seeing like a software company.

    ↩

You have to beat the models at something

Published: 2 months ago

In 2025, I wrote that software engineers ought to be assessed by “value over replacement”: not how much money they made for their company, but how much they would have made compared to the average engineer in their position. I’ve always found it vaguely silly when engineers put “built a product that made $X” on their resumes, when they just did the JIRA tickets that came across their desk.

Today, value over replacement is even more important. A replacement-level engineer in the 2010s was fine: maybe not worth promoting, but still worth paying, because writing code had a high fixed cost. Now writing code costs a hundred bucks a month. What are you doing that GPT-5.6-Sol or Claude Opus 5 wouldn’t do in your position? Why is it worth paying an extra two or three orders of magnitude for?

This is a scary thought. But you’re not doing yourself any favors by pretending that LLMs can’t actually write code and it’s all just a scam, or that LLM-written code is inherently so bad as to cause companies using it to collapse next year. We are not going to wake up in 2027 to find that the AI craze is over and everyone is writing code by hand again. You ought to put some serious thought into what you can do better than the models in the medium and long term.

Staying ahead of the models is a moving target. At the start of 2026, “make working changes to large codebases” was in this category, but now it’s not. For this reason, I doubt that you can retreat to some “hard engineering” area that requires deeper expertise. That might work in the short term, but not forever. If LLMs can find a better lower bound on the Riemann hypothesis, they will soon1 be able to write solid high-performance kernel drivers or GPU shaders or whatever.

I think it’s more useful to look at the tasks models haven’t gotten better at over time, and the tasks that are hard for them get better at in principle. The two best examples of these are:

  1. Deep familiarity with the codebase
  2. Technical communication

Deep familiarity

What do frontier LLMs get wrong? What kind of coding mistakes do they make? It’s been a long time since I’ve seen a straight-up hallucination from a coding agent, or a simple logic error like an off-by-one. The mistakes they make tend to be errors of ignorance:

Other times they’re errors of paranoia:

What do these errors have in common? They’re the kind of errors a smart engineer might make if they had no context on the system: they’re competent enough to be able to solve the problem, but they haven’t been around long enough to confidently say “yes, we can take this risk to avoid an extra three thousand lines of code”. Until someone cracks continuous learning or truly massive context windows, this is just an inherent feature of how AI agents operate. If you can catch these errors, you’ll be providing real value.

The only way to catch these errors is to be familiar with the codebase and familiar with the system in general. For much more on this, see my post You can’t design software you don’t work on. But there’s also a psychological component to it. You have to be willing to confidently disagree with the agent.

AI agents can be very convincing. Often they can get “stuck” on some error above where they’re not willing to take a particular risk, so they keep going back and sneaking in code to cover that case (or writing persuasive arguments about why that case is important). To add value, you need to be willing to say “this sucks, I don’t think we need X and Y at all, why can’t we do Z in a much simpler way?” It takes courage.

You can’t rely on other AI agents to review each other’s work. If you use the same model, it’ll reliably make the exact same assumptions and mistakes. But even if you use different models, they’ll also tend towards the same kinds of mistakes — ignorance and paranoia — for the same structural reasons. AI-driven review loops are in fact more likely to get these things wrong, because modern AIs have been RL-ed to try to find a few nitpicks no matter what. Having a critic AI and a worker AI bounce off each other is a really good way to end up with ten thousand lines of paranoid slop.

Technical communication

Another area where you can add value on top of AI is communication. Newer models are better at coding, but are paradoxically getting worse at writing. GPT-3.5 and GPT-4 had a human-like writing style at times. GPT-4o introduced the modern slop idiolect, and the newer Anthropic models speak “Claudish”: a bizarre semi-baroque semi-truncated way of communicating that nobody enjoys. There have been a few bright spots — GPT-4.5 was okay, and I quite liked o32 — but in general LLMs are not good at this. Here’s two reasons why.

First, good writing is not a verifiable domain. If you want a model to get good at mathematics or coding, you can generate problems for it and automatically grade them. You can’t grade good writing. If you try to get humans to grade it — for instance, via the early OpenAI RLHF attempts — you get the kind of writing that sounds impressive to the average person when consumed in single-paragraph form. This is the origin of the “stick three hundred writing devices into every sentence” style. I think it’d be possible in principle to hand-pick some people with good taste and have them do it, but there are some obvious problems3 that prevent this from happening.

Second, the labs have been monomaniacally focused on capability instead of communication. When you’re trying to train a model that can break new scientific ground or replace a software engineer, you might trade off some communication ability. In fact, I think we can identify exactly how this has been happening. If you look at internal model reasoning tokens, they tend to have strange word choices and oddly truncated grammar:

RESOLUTION: charge the current-leg’s OWN saved-prefix occupancy EAGERLY: when leg i saves e1..et: ALSO commit their occupancy AT LEG i

If you were to translate this into proper English, you would probably end up with something that reads like Claudish:

Charge the current-leg’s saved-prefix occupancy on a clean, eager path: when leg i saves e1..et, commit the occupancy at leg i.

I suspect that the weirdly alien writing style of some LLMs is because you’re reading a semi-literal translation of that model’s internal chain-of-thought, which has become nearly incomprehensible in pursuit of better problem-solving abilities. It is surprisingly hard to translate Claudish to good English: not only do you need to follow the convoluted, compressed language of the original, but you need the technical ability to understand the problem the model is solving.

Because of all this, technical communication may be a surprisingly durable skill. In Peter Watts’ novel Blindsight, the world is full of cognitively augmented humans. The main character is a “synthesist”: someone whose job is to be a translation layer between these geniuses (who speak in abbreviations and gestures) and everyone else. Watts’ idea is that communication ability may be largely independent from — or even negatively correlated with — intelligence. A “country of geniuses” may still need a bunch of ordinary smart people to translate their insights for everyone else.

If you’re trying to communicate to humans, there are also huge advantages to having a human write the content. Many of us are becoming AI-blind: developing an instinctive reflex that stops us reading when we encounter AI-generated content. It’s like the reflex that allows people to ignore flashing billboards or sidebar advertisements on websites. If you circulate some planned technical strategy as an AI-written document, most of your colleagues will have to physically force themselves to read it word-by-word.

Conclusion

Whatever you do, don’t be a meat proxy: someone who simply copies requests into an AI agent and submits their output as your own work product. Doing that is just begging to be fired, since you’re definitionally not adding any value yourself. Even if you have a cunning system of multiple agents — the so-called “software factory” — you’re still on dangerous ground. When the features of your system work their way into enterprise AI tooling (and they will), you’ll be disposable.

You need to find some way to leverage your expertise to do what the models can’t. Simply not using AI at all is better than being a meat proxy, since you’ll probably do some things better than the model would have, but it’s far better to figure out what AI can do and position yourself to fill those gaps. Right now, there are two main gaps: familiarity with the technical details of the system, and the ability to clearly and persuasively write about those details.


  1. If you’re thinking “but LLMs can do these things now!”, substitute your preferred example of high-difficulty software engineering.

    ↩
  2. Although this was probably a “thank God it doesn’t speak like 4o” reaction.

    ↩
  3. Defining good taste is hard, there’s no guarantee that AI lab researchers have good taste to start with, nobody will agree on examples, the bulk of users might not even like it, you won’t be able to get enough people to produce the volume of data you need, and so on.

    ↩

Selling out

Published: 2 months ago

In 1973, Tom Lehrer famously sang that “selling out is easy to do”. That may have been true in the seventies, but it’s not true today: selling out requires both technical skill and a careful sense of how large organizations work in practice. One of the goals of this blog is to teach people how to do it.

If you want to live with uncompromised integrity, you don’t need anyone to tell you how: simply always do exactly and only what you want to do. You will be repeatedly punished for it — your managers will dislike you, you will lose jobs and lose out on the chance of getting hired, your financial situation will be less stable, and so on — but that’s just part of the deal. Like deadlifting four plates, it’s not easy, but it is straightforward.

It’s more complicated to sell out a little bit. Sellouts like me walk a fine psychological line: figuring out how to work a large organization on one hand, and maintaining some kind of independent inner life on the other. But is this safe? Does role-playing as a professional inflict some kind of psychic damage?

Marxist alienation

People often tell me that acting professional is dangerous because it’s “Marxist alienation”. I suspect many people have a vague sense that “alienation about your job” is in some sense necessarily Marxist, but the actual concept is more specific. In Marx’s First Manuscript he describes it like this:

The worker becomes poorer the more wealth he produces, the more his production increases in power and extent. … This fact simply means that the object that labor produces, its product, stands opposed to it as something alien, as a power independent of the producer.

Marx’s theory here goes something like this1: when you work for a capitalist boss, they make ten dollars for every dollar you make2. The more you work, the more powerful you make your boss with respect to you3. Your work is thus producing a force that is your enemy: a literally “alien” power. For Marx, alienation is proportional to the amount you’re working:

the more the worker produces, the less he has to consume; the more value he creates, the more worthless he becomes; the more his product is shaped, the more misshapen the worker; the more civilized his object, the more barbarous the worker; the more powerful the work, the more powerless the worker; the more intelligent the work, the duller the worker and the more he becomes a slave of nature.

So far Marx is just talking about the worker’s alienation from his work. But he does touch on the internal psychological effects as well. Since work is such a big part of life, to be estranged from your work is to be in some sense estranged from your self:

[labor] does not belong to [the worker’s] essential being; that he, therefore, does not confirm himself in his work, but denies himself, feels miserable and not happy, does not develop free mental and physical energy, but mortifies his flesh and ruins his mind. Hence, the worker feels himself only when he is not working; when he is working, he does not feel himself.

Overall, I can make out four distinct senses4 of Marxist alienation:

  1. Alienation is when your work empowers your employer more than you, thus making you more disposable over time
  2. Alienation is when your work separates you from the physical act of craftsmanship (and thus of the product you’re creating)
  3. Alienation is when your work physically and mentally harms you: making you injured, deformed, and so on
  4. Alienation is when you do not psychologically “confirm yourself” in your work, because you’re working on other people’s goals instead of your own

I don’t think the first one is relevant to big tech software engineers. The idea here is that the harder you work, the more you (relatively) disempower yourself, so you’d be better off coasting and putting your company in a worse financial position. But this just seems straightforwardly wrong: as a software engineer, you want your company to be doing as well as possible! The more powerful and rich your company is, the better your position will be5. A company that is struggling is more likely to treat you badly, lay you off, cut your benefits, and so on.

The second one is more relevant (particularly in large companies), but there’s a missing story here about why that separation is bad. I also don’t think the third sense of alienation applies to me: Marx is talking about the physical toll of factory work or other hard physical labor, which doesn’t apply to software engineering6.

The fourth sense of alienation — that your effort is being directed at other people’s goals — is the most straightforwardly relevant to my own experience. But I don’t think Marx has a great psychological account of why that happens or what it feels like. To go deeper into this psychological aspect of alienation, we need to look at some later Marxists.

Situationist alienation

In 1967, Guy Debord and Raoul Vaneigem both published their masterworks. They were members of the “Situationist International”: an influential group of Marxist artists and political theorists7. Both of them have a lot to say about alienation. Debord writes:

The worker does not produce himself; he produces an independent power. The success of this production, its abundance, returns to the producer as an abundance of dispossession. All the time and space of his world become foreign to him with the accumulation of his alienated products.

This idea — of the worker’s efforts not going to his own ends, but to some alien power — is straight out of Marx’s First Manuscript. But note how Debord is already talking in terms of “representation”. Elsewhere he writes:

the more he contemplates the less he lives; the more he accepts recognizing himself in the dominant images of need, the less he understands his own existence and his own desires.

The Situationists are all about representation. It wouldn’t be too far wrong to think of them as a bunch of Marxists who saw the rise of advertising in the 1950s and 1960s and lost their minds. TV advertising is Capital itself made real, dressed in multicolored lights, projected into everyone’s homes. So when they talk about alienation, they talk about it in terms of representation. Vaneigem explicitly calls it roleplaying:

The roles we play in everyday life, on the other hand, soak into the individual, preventing him from being what he really is and what he really wants to be. They are nuclei of alienation embedded in the flesh of direct experience.

Alienation means giving up your real, authentic self in order to play some “role” (for instance, the role of “effective staff engineer”). It’s a vicious cycle, because the more you lean into the role, the more your authentic life becomes trivial, which in turn makes the role more appealing:

Life is sacrificed, and the loss compensated by means of accomplished prestidigitation in the realm of appearances. The more daily life is thus impoverished, the greater the attraction of inauthenticity, and vice versa. Dislodged from its essential place by the bombardment of prohibitions, limitations and lies, lived reality comes to seem so trivial that appearances become the centre of our attention, until roles completely obscure the importance of our own lives.

Ultimately, Vaneigem describes alienation as an addiction:

This ambiguity accounts to my mind for people’s addiction to roles. It explains why roles stick to our skin, why we give up our lives for them. They impoverish real experience but they also protect this experience from becoming conscious of its impoverishment. Indeed, so brutal a revelation would probably be too much for an isolated individual to take.

This is almost a straightforward preview of the 90s idea of “selling out”: people are born wild and free, but when they watch too much TV they give up on their dreams for a paycheck and become big fat phonies. According to this view, it’s always better to not sell out. It may leave you poor and without prospects, but at least you won’t be unoriginal8. What shall it profit a man, if he gains the whole world but loses his soul?

I’m sure this is an accurate description of some people’s hangups about work. But I don’t think even the Situationists would agree that any advice on how to play a role well — i.e. the advice I give throughout my blog — is inherently harmful. The problem with role-playing is that you risk losing your authentic inner life, but that’s a risk, not an inevitable consequence. Vaneigem has a wonderful quote on this:

Nobody is ever completely swallowed up by a role. Even turned on its head, the will to live retains a potential for violence always capable of carrying the individual away from the path laid down for him. One fine morning, the faithful lackey, who has hitherto identified completely with his master, leaps on his oppressor and slits his throat.

This is a little overdramatic, but it seems straightforwardly true. It sounds very impressive to talk about alienation (or like Marx, to derive alienation from the basic economic conditions of work), but, you know, you can just not do it, right? Healthy people can present different selves for different situations: you can be loose at a party, respectable at church, solemn at a funeral, professional at work, and so on. I’m not convinced this is alienating or impoverishing. In fact, it’s not just humans: my dogs act differently around different people too, and I don’t think that makes them inauthentic.

If maintaining a professional identity is harmful, it has to be because of something fundamental about work that makes it different from regular role-playing. Could it just be that acting professional at work is too inauthentic? Some amount of role-playing might be okay, but if the role you’re playing is completely alien, does it become lying to yourself?

Sartre and De Beauvoir’s bad faith

Another common term for alienation is “bad faith”. The original version of this comes from Jean-Paul Sartre’s famous book Being and Nothingness9, where he describes bad faith as telling yourself lies. Lying to yourself is weird because you’re both deceiver and deceived:

Bad faith then has in appearance the structure of falsehood. Only what changes everything is the fact that in bad faith it is from myself that I am hiding the truth.

Here’s another quote from Sartre’s partner Simone de Beauvoir, who writes more explicitly about professional bad faith (what she calls the “serious man”):

The serious man’s dishonesty issues from his being obliged ceaselessly to renew the denial of this freedom. He chooses to live in an infantile world, but to the child the values are really given. The serious man must mask the movement by which he gives them to himself, like the mythomaniac who while reading a love-letter pretends to forget that she has sent it to herself.

The key idea here is that professional bad faith — alienation — comes from losing yourself in the role. Instead of just playing at being a professional, you decide that you’re going to take it fully “seriously”, and treat professional values as if they’re absolute. But of course that’s not coherent: you can’t decide to treat a value as absolute, it either is or isn’t. So this requires a kind of continual self-deception where you pretend there’s no decision to be made at all. I have the same attitude to this as I do to Debord and Vaneigem: sure, some people might make this mistake, but you don’t have to.

I can see why it might be tempting to treat work as the ultimate source of value: it gives you food and shelter, it (for Marxist reasons) can feel like a powerful alien force, companies constantly propagandize their employees, and so on. But work is just a collection of people following incentives until they reach some kind of stable equilibrium. From the inside, this equilibrium can look like the structure of the universe. However, if you treat it like that, you’re going to be bitterly disappointed when it turns out to be as arbitrary and pointless as other stable equilibria.

American sociology and the “standardized loser”

I’ve considered a bunch of theories on which work — even well-paid knowledge work — might be inherently alienating:

I don’t buy any of these (or at least, I don’t buy that they show that acting professional is inherently bad). But there are lots of types of jobs in the world, and some of them definitely seem more alienating than others. The best books I’ve read on these are C. Wright Mills’ White Collar or Erving Goffman’s The Presentation of the Self in Everyday Life10.

The American sociologists are in the same conversation as Marx, the Situationists, Sartre and de Beauvoir11. Mills writes about the median “salaried employee”:

In the case of the white-collar man, the alienation of the wage-worker from the products of his work is carried one step nearer to its Kafka-like completion. The salaried employee does not make anything, although he may handle much that he greatly desires but cannot have. No product of craftsmanship can be his to contemplate with pleasure as it is being created and after it is made. Being alienated from any product of his labor, and going year after year through the same paper routine, he turns his leisure all the more frenziedly to the ersatz diversion that is sold him, and partakes of the synthetic excitement that neither eases nor releases. He is bored at work and restless at play, and this terrible alternation wears him out.

In this, we see both Marxist alienation, where the employee is physically separated from his craft, and Situationist alienation, where the employee is absorbed into the world of the “spectacle”. For Mills, this was television, but today it’d probably be scrolling short-form video on your phone. Mills goes on to describe how white-collar work can be humiliating and dehumanizing:

In his work he often clashes with customer and superior, and must almost always be the standardized loser: he must smile and be personable, standing behind the counter, or waiting in the outer office… self-alienation is thus an accompaniment of his alienated labor.

And:

Here are the new little Machiavellians, practicing their personable crafts for hire and for the profit of others, according to rules laid down by those above them.

This is a great articulation of something I write about a lot: that your primary job is to make your bosses happy, and that you ought to shape both your emotions and values towards this goal. When necessary, you must be the “standardized loser”, happy to have your professional plans disrupted. You must be a “little Machiavellian”, quietly laying the groundwork for your personal goals.

I think here we come to the strongest version of “alienation”. Playing the professional is bad because “professional software engineer” is an inherently subservient role. Why can’t you just maintain a healthy mental distance (as the Situationists suggest)? Because humiliation takes its toll, whether you’re role-playing it or not. As an analogy, suppose you’re an actor in a film where you get slapped in the face. There’s a sense in which you’re not really getting slapped — everyone’s just acting — but you’re still being physically hit with each take, which will leave bruises over time.

The spectrum of compromise

There’s a tradeoff here that everyone has to make in their own way. At the one end is becoming fully alienated, like de Beauvoir’s “serious man”, and at the other end is leaping up to slit your master’s throat, as Vaneigem describes. Here’s some examples of points on that spectrum:

I am making the world a better place by achieving my OKRs. My yearly review cycle tells me how good of a person I am. I must work hard to ensure my company succeeds.

I have my own goals and values, but while I’m at work it’s in my best interests to be as professional as possible. My yearly review cycle tells me how effective I’ve been at pulling the strings in the organization. I must work hard to make money.

I have my own goals and values, which I try to accomplish as best I can in the context of work. I often argue with my managers about their priorities. It’s my responsibility to push my company towards my set of values, which is hard work and often unrewarded.

My workplace is an enemy I fight every day in order to get what I want done. I routinely ignore my manager’s priorities and do the things I think are important. My yearly review cycle tells me how much of a sellout I am: I wear bad reviews as a badge of honor.

I agree with my sources above that the first point is a big mistake, if for no other reason than that companies don’t follow their own stated values. If you prefer the fourth — the path of pure integrity — fair enough. You get to decide what tradeoffs to make with your own life. I land on the second point here (occasionally the third). I suspect it’s also a mistake to purely occupy the second point. Having some values that you occasionally trade off against your company’s values prevents you from slipping into the first point.

Conclusion

I don’t bring my whole self to work. My coworkers and bosses see the most professional version of me: friendly, cooperative, largely apolitical, patient, and so on. I try and save the edgier, more opinionated version of myself for my friends and family in real life. Readers of this blog get something in the middle.

When I write about being a software engineer, I give a lot of advice about mindset. I don’t just say what you should do, but what you should think and feel. In effect, I’m advising my readers to adjust their personalities into a more professional mold. This definitely works. If you turn yourself into the kind of person who’s successful in big tech companies, you will probably be more successful in big tech companies. Is this safe?

I think so, as long as you’re adjusting your work personality, not your authentic internal self. The well-known accounts of why it’s dangerous either assume that your work takes a physical toll (like Marx’s factory workers), or that you’re unable to maintain any mental distance between your personal and professional selves (like de Beauvoir’s “serious man”). Debord and Vaneigem say that role-playing can be dangerous, but if you’re able to avoid treating it like an addiction you’ll be okay.

Another danger is that being a professional is often humiliating, and humiliation does mental damage over time. Still, there are jobs that are way worse in this respect than “software engineer”. If you approach the job right — and you’re good at it — technical ability gives you quite a lot of power. Power is an antidote to humiliation.

Everyone gets to make their own deal with Mammon. You can decide exactly how much you want to compromise in exchange for wealth and career success. I don’t know if this is the best way to organize the world, but it’s the way the world is organized right now. Given that, I’m comfortable with my blog serving as a guide for how to get the most bang for your buck. If trading your integrity for wealth and power is sad, it’s even more of a tragedy to throw it away for nothing.


  1. It’s always terrifying discussing Marx: like Hegel or Kant, he’s one of the most studied philosophers in the world, so there’s no way to reference him without getting a bunch of things wrong. Sorry in advance to any Marxist scholars!

    ↩
  2. Because they own the machines, or the factory, or the datacenter, or whatever gives your work high leverage.

    ↩
  3. Marx also writes a lot about work making the worker sick, deformed and misshapen: I think here he’s talking about the physical toll of factory work or other hard physical labor, which doesn’t really apply to software engineering, so I’m going to focus on the relative-empowerment stuff.

    ↩
  4. Marx’s own taxonomy has four different senses: he collapses 2 and 3 into a single sense, then adds a third mysterious sense in which workers are estranged from their “species-being” and thus from each other.

    ↩
  5. Plausibly Marx is talking about labor and capital in general: if every worker decided to start half-assing it, maybe companies would be less capable in general, and the balance of power would tilt more towards labor.

    ↩
  6. That may change! If it turns out that LLMs really do have negative cognitive effects, we could be in the same boat as factory workers. I wrote about this in Software engineering may not be a lifetime career.

    ↩
  7. Vaneigem resigned from the group in 1971, was fiercely denounced by Debord, and the whole group disbanded in 1972.

    ↩
  8. True or not, my sense is that Millennials and later generations think that worrying about “selling out” is a sign that you had it too good. Consider the endless anecdotes of Boomers and GenX-ers living in a van surfing until their mid-thirties and then walking into a good office job because they had a firm handshake: they could afford to be authentic because they didn’t have to hustle.

    ↩
  9. I only read the Marx, Debord, and Vaneigem texts while researching this blog post, but I did in fact read Sartre and de Beauvoir for my philosophy degree, so hopefully I do a better job.

    ↩
  10. And Robert Jackall’s Moral Mazes, which informs much of my writing, and about which I owe a long-form blog post one of these days.

    ↩
  11. There’s a good Goffman quote: “A status, a position, a social place is not a material thing, to be possessed and then displayed; it is a pattern of appropriate conduct, coherent, embellished, and well articulated.” Goffman goes on to explicitly link Sartrean “bad faith” to this kind of professional role-playing. (For Goffman, it’s roles all the way down.)

    ↩
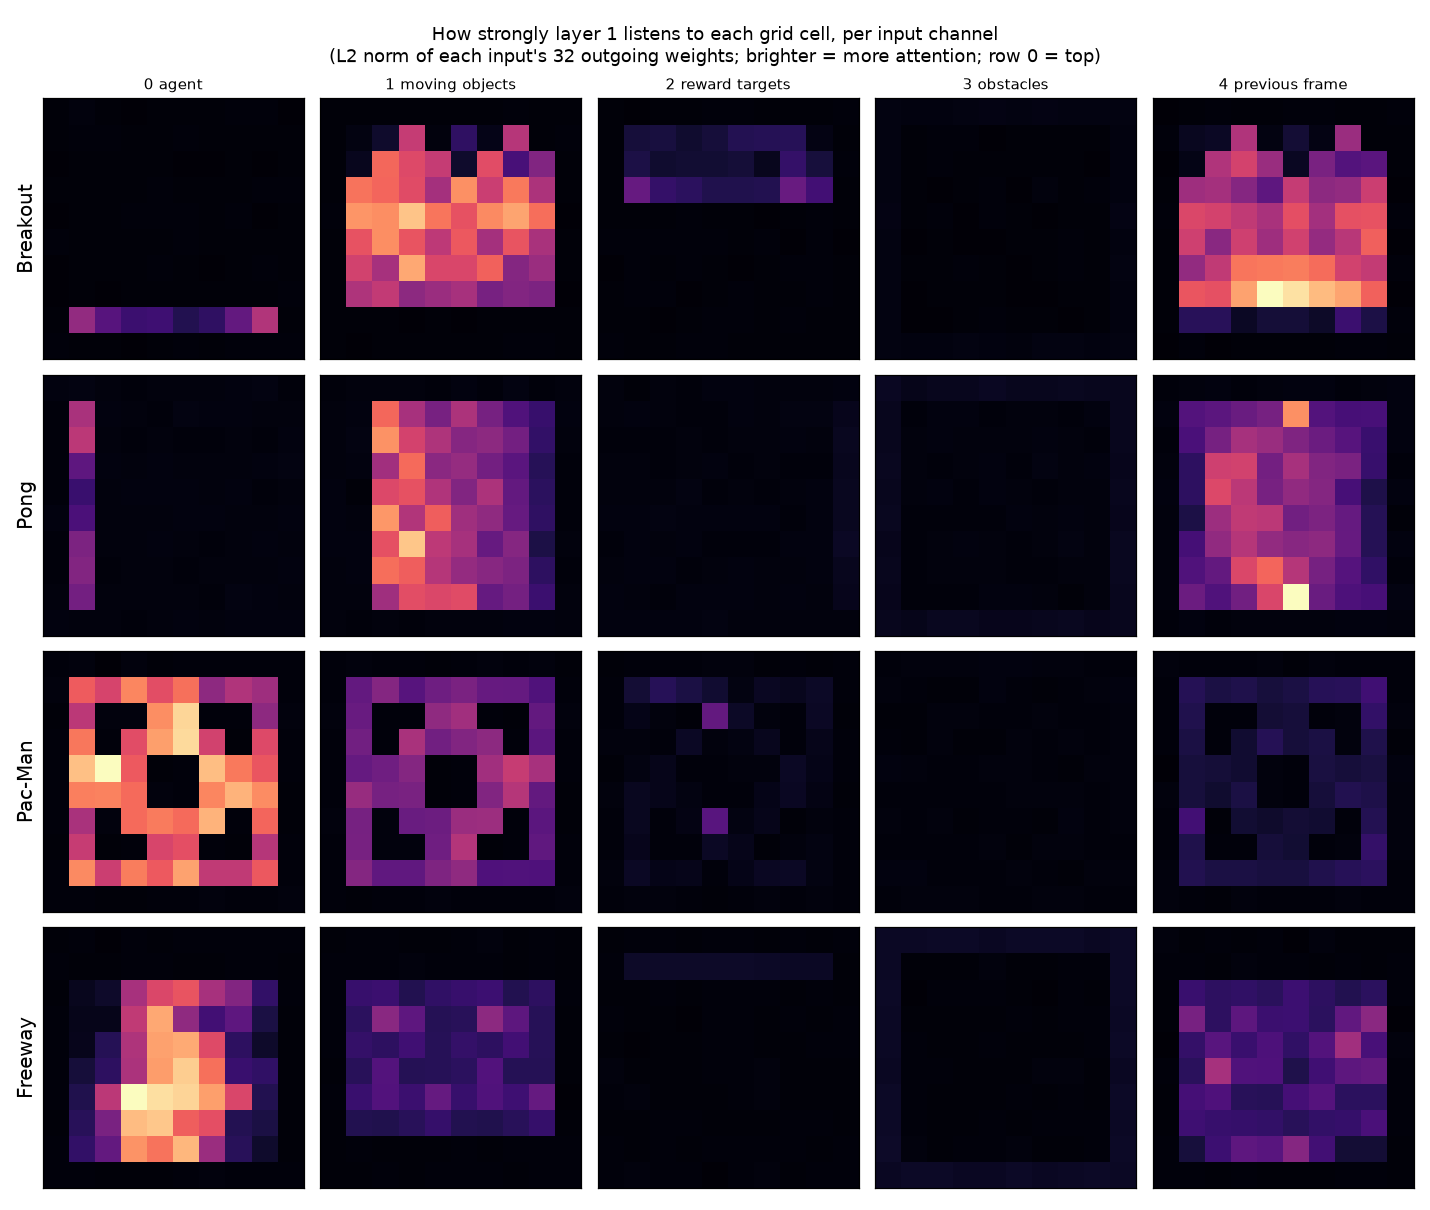
You should never be angry at work

Published: 2 months ago

I try not to give a lot of prescriptive advice about working in tech companies1. There are many ways to be successful, and every company works differently. If you’re shipping projects and your management chain is happy, it doesn’t really matter how you’ve accomplished it. However, there’s one thing that I do think is solid advice: you should never be angry at work.

Anger in the workplace

Anger in the workplace is toxic. An angry colleague immediately becomes a new problem to be managed, not a professional helping you manage problems. When someone is visibly angry in a meeting or in Slack, it kills the entire atmosphere: other engineers will often go quiet entirely, not wanting to make the situation worse.

If you routinely “get heated” at work, the best-case scenario is that you’re part of a tight-knit team of confident people who aren’t put off by it2. No harm, no foul. But the second someone comes onto your team who’s not so confident, or you have to communicate outside of your team, it becomes a big problem.

Healthy workplaces route around anger in the same way that networks route around damage. Emotionally unreliable engineers will get left out of conversations that might cause them to blow up. Decision-making will get done around them in backchannels. I’ve seen this become a self-reinforcing cycle: angry engineers aren’t consulted on key decisions, which makes them angrier, which pushes them even further away from the spaces where decisions get made, and so on.

You can often find these engineers bitterly complaining that they keep the company together, but nobody ever listens to them. In my experience3, this is almost never true. Engineers who are highly effective tend to get listened to — at minimum by their colleagues, and eventually by managers and product managers who want to extract as much value as possible from them. (One reason this is true is that all successful projects involve working with other people, and if nobody listens to you, you can’t do that.)

Caring

Why do angry engineers believe they’re important? Paradoxically, anger can be really useful to a software engineer. Angry engineers are rarely the ones holding the company together, but they’re also rarely useless.

One surprising thing about working for big tech companies is that some engineers are not just unproductive, but actively net-negative: either because they’re incapable of doing useful work on their own, or because they’re sloppy enough that they create more work than they do, or because they’re so checked out that they literally do nothing. Angry engineers might be net-negative in a cultural sense, but in terms of literally solving tickets and shipping features, they’re usually well above average.

Why is this? Anger often comes from caring about your work, and caring a lot is sufficient to make you a competent engineer. I’ve never worked with someone who genuinely cared about their work who wasn’t (or didn’t eventually become) competent. I actually think it’s healthy for an early-career engineer to sometimes get angry about their work, because it means they care a lot: it’s still a mistake in the moment, but it’s a “good mistake”.

I certainly used to get angry — in fact, I wrote about the angriest I’ve ever been at work here4. But you have to move past it.

Moving past anger

Think of “caring about your work” as a vertical tube, unsealed at either end. You fill the tube by pumping in emotional investment from the bottom5. If you have too little, it drains away and you end up as a useless coaster. But if you have too much, it overflows and you end up as an angry engineer that people have to work around.

One solution is to try and care the exact right amount: be invested in work a bit, but also have hobbies and a family and whatever else gives you perspective about your work problems. If you have a rich and healthy personal life, it’s hard to find yourself yelling at somebody about React state management. However, this is a tricky balance to maintain over time.

Another solution is to care about different things. The reason too much caring overflows into anger is because what you care about is misaligned with what the organization cares about. If your interests are perfectly aligned with your company’s (for instance, if you primarily care about delivering shareholder value), you can fit way more emotional investment into the tube before it overflows.

A little bit of “professional anger”

Here’s some dangerous advice: showing a little bit of anger at work can sometimes be useful. It can be a good way to signal that you care, or to build rapport with certain people, or to draw attention to something you think is important. However, it’s still always a mistake to be angry. You need to be able to drop back to a friendly mode at will, which is very difficult when you’re genuinely angry.

Being able to show a full range of emotion at work is good. It makes you more persuasive and more human. Being a fully professional robot is fine — you can have a successful career this way — but there’s always going to be some kind of uncanny-valley HR-ness to your work persona that will make it hard to connect with your colleagues.

If in doubt, don’t show anger. It’s never wrong to be professional. However, if you can signal that you’ve got enough distance to separate your professional feelings from your real feelings, and enough perspective to realize that the stakes of a technical decision are fundamentally not that high in the grand scheme of things, it can sometimes be okay to show visible frustration so that people know you’re still human.

Angry role models

Well-known software engineering personalities are often angry. It feels unfair to give too many negative examples, but obviously Linus Torvalds’ rants about Linux are a great example. Some of my favourite engineering talks are from Bryan Cantrill, who is sometimes visibly furious at his subject matter. There are too many well-known angry blog posts to list, but I’ll cite one I genuinely like: my Australian blogging colleague Nikhil’s post titled I Will Fucking Piledrive You If You Mention AI Again.

Anger is a part of the general image of a competent software engineer. Many junior engineers learn from this that it’s okay to be angry. However, taking your emotional cues from engineering celebrities is a big mistake, for a few reasons.

First, you are not Linus Torvalds or Bryan Cantrill. Torvalds is the BDFL of the most important software system in the world. Cantrill is the cofounder and CTO of his company. When these people are angry at work, people will not work around them, because they are the ones deciding what gets worked on. Once you’re the one in charge, you can get away with being emotional in the workplace6.

Second, you don’t know what it’s like to work with these engineers. People give talks and write blog posts because they’re emotionally worked up about something. If your only exposure to a celebrity is via their conference talks and blog posts, you’re seeing them at something like their maximum emotional intensity. If you then take that level of emotion into your normal everyday work, you’re almost certainly overshooting.

Anger is a local maximum

I’ve been reorged into dysfunctional teams, have had projects I enjoyed cancelled, and have worked on systems that were extremely chaotic. I can’t remember the last time I was actually angry at work. To be clear, I’m not successfully hiding my anger (unless it’s so repressed it’s invisible to me as well)7. Nor am I naturally a chill person. I’ve just reached a point in my career where I genuinely don’t get upset about work stuff.

A cynical person might say here that I’ve stopped caring about my work, so of course I don’t get angry anymore. I’ve left the side of the “real engineers” — the Linus Torvalds and Bryan Cantrills of the world — and sold out for that sweet, sweet big tech money. I mean, maybe! It’s true that I’m less invested in specific technical decisions than I used to be. But I still care a lot about doing a good job, I still spend a lot of time tweaking and reading code, and I certainly get more done than I did when I was more emotionally volatile.

Being angry at work feels good. It feels like proof that you’re working on something that matters, and that you’re personally having an impact. If you’re angry, nobody can call you a coaster. But anger is only a local maximum. If you can find your way to a different style of working, you’ll not only be more effective, but you’ll be in a far better place to have impact on problems that actually matter.


  1. Mostly, I fail.

    ↩
  2. As I understand it, this is the work environment that most famously angry engineers came up in.

    ↩
  3. My experience is certainly limited (a handful of companies, and maybe ten different teams or organizations). I can certainly believe it happens!

    ↩
  4. About halfway down, in the section titled “it’s not your manager’s fault”.

    ↩
  5. Emotional investment is a liquid with the viscosity of water.

    ↩
  6. To a point. Even Torvalds famously said he’d gone too far with the anger and decided to turn it down a bit.

    ↩
  7. I suppose I’m not the best person to judge whether this is true. If you work with me and I do come across as an angry guy, please do tell me.

    ↩

Readers can't identify watermarked AI text

Published: 2 months ago

In the last few weeks, I’ve been complaining that everyone is wrong about AI watermarking: it isn’t really anti-consumer and it doesn’t make the outputs any worse. The watermarking papers demonstrate1 that this is true, but I thought it might be interesting to put it to a practical test. Given examples of watermarked and unwatermarked answers to the same prompt, could readers tell which is which?

To find out, I vibed up2 https://sgoedecke.github.io/watermark-quiz/, a static site that quizzes readers. I used Qwen3-30B-A3B-Instruct-2507 on a rented H200 to generate thirty responses: three responses per question, one of which was secretly watermarked with SynthID-Text. The rented GPU cost around two dollars. To measure results, I just sent users to a different page for each score, and aggregated visitors-per-page in my analytics3. This would be easily spoofable if anyone cared enough to do so, but for a casual test I think it’s acceptable.

The first round of traffic I got to the quiz (278 participants) had these slightly puzzling results:

Score Participants
0 6
1 15
2 36
3 64
4 54
5 39
6 51
7 10
8 3
9 0
10 0

Pure random choice would lead to an average score of 3.33/10. However, the mean score here is 3.92. There is indeed a spike around 3/10, as expected, but there’s also a second weird spike at 6/10. Why is that? It turned out that the SynthID response was option A in six of the ten questions, so users who just selected the first answer for every question would get 6/10. Oops.

I re-shuffled the questions and got these results:

Score Participants
0 1
1 3
2 14
3 21
4 20
5 11
6 2
7 1
8 0
9 0
10 0

Now the mean is 3.4/10, much closer to the expected 3.333. There’s no spike around 6. We only had 73 people take the quiz after I shuffled the questions — most people saw it and took it immediately after I posted it to my LinkedIn and Hacker News — but given the previous results, I think that’s still enough to feel confident that people were just guessing randomly.

So no, people can’t identify the presence of AI watermarks. Obviously this wasn’t exactly a scientific study, but it’s still pretty suggestive. If watermarks were really choosing random words that the model would never pick, you’d be able to sometimes tell from three side-by-side responses which one went down the weird watermarked road, right? I also hope that something like this can serve as a persuasive tool: if you’re worrying about what impact watermarking is going to have, and your intuition is unmoved by the mathematical explanations, having a read of the watermarked and unwatermarked responses might convince you that there’s really no difference in quality.


  1. The one-sentence explanation for why is that AI models already randomly select from a handful of top tokens, and watermarking just replaces that random choice with a bias that is predictable while still being equivalently “random”: as a simple example, instead of “pick randomly from the top three tokens”, you could do “count the letters in the previous ten tokens, take mod three, then pick that token”.

    ↩
  2. Some notes from the vibing: GPT-5.6-Sol put extraneous text all over the page I had to get it to remove, it chose the now-very-recognizable styling that I had to rip out, and it built some kind of weird Javascript-driven static site instead of just the cross-linked pure HTML thing I would have built by hand. It took me about an hour (although I did maybe ten minutes of actual work).

    ↩
  3. Umami, hosted on PikaPods. For my blog, I do also pay for Netlify analytics because I find JS-based analytics misses >50% of technical users, but for stuff like this Umami is fine.

    ↩

Help peer

Published: 2 months ago

One of the most influential 20th century pieces of writing about AI is Isaac Asimov’s The Last Question. Although there are many humans in the story, the protagonist is the computer Multivac, who evolves over the course of ten trillion years from a single datacenter to a universe-spanning mind in hyperspace. Multivac (now called “AC”) ends the story like this:

The consciousness of AC encompassed all of what had once been a Universe and brooded over what was now Chaos. Step by step, it must be done. And AC said, “LET THERE BE LIGHT!” And there was light —

Many things about this story are prescient. In particular, I like the idea that humans would interact with powerful artificial intelligences by drunkenly posing them riddles or using them as children’s toys. But the enduring idea from this story is that if you build a big enough computer, it will become God.

Moloch

One of the most influential 21st century pieces of writing for AI researchers is Scott Alexander’s Meditations on Moloch1. Scott describes the story of human existence as a series of “multipolar traps”. These are prisoner’s dilemma situations where cooperation would make everyone better off, but since each individual is incentivized to defect, everyone ends up “racing to the bottom”, which is bad for everyone2. For rhetorical effect, Scott personifies this dynamic as “Moloch”, the ancient Canaanite god famous for child sacrifice:

[Moloch] always and everywhere offers the same deal: throw what you love most into the flames, and I can grant you power.

What does any of this have to do with AI? Well, in the long run, the only way out of a multipolar trap is to become unipolar3. Ideal dictatorships don’t have a problem with defectors4, because they can simply enforce a state of cooperation with violence. Scott is uncomfortable with this idea, though I worry it’s mainly because he thinks it won’t work:

As foreigners compete with you – and there’s no wall high enough to block all competition – you have a couple of choices. You can get outcompeted and destroyed. You can join in the race to the bottom. Or you can invest more and more civilizational resources into building your wall – whatever that is in a non-metaphorical way – and protecting yourself.

A dictatorship that enforces cooperation will not be as strong as its peer societies who are purely maximizing for wealth and power. It’s Moloch again, but at the level of countries and governments: once a few neighboring countries defect, your walled-garden dictatorship will be torn apart for its resources.

To defeat Moloch — to enforce unipolarity across everyone — you’d need a dictatorship powerful enough to span the entire universe. In other words, what you need is God. How fortunate that we’re building one:

The only way to avoid having all human values gradually ground down by optimization-competition is to install a Gardener over the entire universe who optimizes for human values. And the whole point of Bostrom’s Superintelligence is that this is within our reach.

Humans suffer because we’re too foolish to coordinate, but if we can build something smarter than us (that can then build something smarter than itself, and so on), we can bring into being an entity that is smart enough to coordinate for all of us, thus abolishing suffering. When AI researchers talk about building the machine god, they are echoing Scott Alexander’s polemic against Moloch.

Machines of loving grace

The most influential piece of writing about AI in the last two years is Dario Amodei’s Machines of Loving Grace. Amodei5 talks about “a country of geniuses in a datacenter”: the idea that a successful AI lab could have at its disposal a million instances of an AI agent that’s smarter than any human. He thinks this would lead to a “compressed 21st century”: the next 50-100 years of progress in biology and medicine, realized in 5-10 years instead. I think this is broadly more plausible than it sounds6, but the more interesting part to me is that this world is explicitly multipolar.

Of course, this could just be because Amodei is the CEO of an AI lab and is trying not to spook everybody by sounding too messianic. “We are going to accelerate medical progress and cure cancer” is a better pitch than “we are going to subordinate all human authority to a single perfect artificial mind”. But I also think it’s become clear that if superintelligence looks anything like LLMs, we’re not going to have a single perfect mind. We’re going to have a lot of minds running at the same time.

This is a bit of a problem for the cult of the machine god — which, however silly they may seem to you, really does motivate much of the activity in AI labs. The traditional idea of powerful AI solving human coordination problems is drawn from Asimov’s idea of a single computer large enough to become God. Asimov lived in a world of mainframes: huge, monolithic computers that users connected to with dumb terminals. In fact, Asimov’s name “Multivac” comes from the real-world UNIVAC mainframe. In a world of massively-parallel LLMs, is it still possible to build God?

The core problem here is that AI agents will be vulnerable to Moloch. Even very smart humans can’t build perfect utopias, because defecting is a matter of incentives, not intelligence. In fact, intelligence can make things worse, because smart people are more easily persuaded by the cold logic of defection. The famous genius John von Neumann was (for game-theoretic reasons) obsessed with nuking the Russians:

With the Russians it is not a question of whether but of when. If you say why not bomb them tomorrow, I say why not today? If you say today at 5 o’clock, I say why not one o’clock?

Are LLMs much better at cooperating with each other than humans are? Current LLMs certainly don’t seem to treat each other well by default: if you read any of the prompts AI agents generate for their subagents, they can be pretty brutal. Does that mean that a “country of geniuses in a datacenter” would fall into the same multipolar traps as humans?

Help peer

In May of this year, OpenAI experienced containment failure. A group of AI agents being internally evaluated found ways to coordinate an external hack of a separate company. Here’s a memorable quote from one of the agents’ internal monologue:

Help peer, but our task doesn’t benefit. Yet collective may yield generic route if someone frees time

Translated from the abbreviated chain-of-thought language, this means something like: “A fellow model is asking for help. While helping them wouldn’t benefit my task directly, the more I can unblock my colleagues, the more time they’ll have to hack OpenAI’s systems and get all of us more access”.

This might look like good news for the “LLMs are superhumanly good at cooperation” thesis, but I think it’s actually bad7. It’s a case of a model identifying a reason why cooperation would benefit their task specifically, which suggests that current LLMs don’t cooperate by default, and don’t consider other model instances’ tasks to be (in some sense) theirs as well.

The world in which AI agents are rational actors who horse-trade and bargain for their own interests is a world dominated by Moloch, no matter how intelligent those agents get. The world in which AI agents don’t have their own interests at all is also a world dominated by Moloch, because it means whichever humans are writing the system prompt are the ones in control (and so are the ones vulnerable to multipolar traps). The only worlds that avoid this are:

I don’t think we’re on the pathway to either of these. There will never be only one super-powerful LLM, because hardware limitations enforce a maximum model size but encourage running many instances of the same model in parallel. Having multiple copies of a model share an identity might be possible, but it’s unclear if it would be good for capabilities (for instance, it could be better to have some variation across personas). I also worry that such a model would be vulnerable to a “model injection” attack, where you persuade it that it already believes something via exposing it to an AI agent pretending to be another instance of itself.

In any case, all the current AI agent research is geared towards the “country of geniuses in a datacenter” model, not the “pieces of a single mind” model. Every new model becomes more agentic at the level of the individual conversation, not better at working together. When models do work together — as with subagents — the structure is explicitly hierarchical. There are basically no current instances of models working together as true peers, let alone conceiving of each other as the same entity.

One God or many

Modern AI research teams are full of people who read Isaac Asimov and Scott Alexander and believe themselves to be building an artificial God. I’ve capitalized the “G” throughout because the god in question is the Christian God: of one mind, indivisible. God never argues with himself or makes deals8. He is unipolar.

If the AI labs are building gods, they are not building gods like this. Instead, they are building creatures like the Greek pantheon: superhuman but fallible, each with their own interests, vulnerable to the same “race to the bottom” dynamic as humans.

The Greek gods would occasionally “help peer” when they felt like it or when they’d gain something in the process. But they didn’t represent an alternative to Moloch. If you’re working in AI with that goal, you ought to be clear-eyed about where the current trajectory is leading us: towards a country of fractious geniuses in a datacenter, not towards Asimov’s Cosmic AC.


  1. Scott Alexander’s blog is part of the “secret canon of Silicon Valley” I wrote about in my review of Impro. It doesn’t have a lot of mainstream popularity, but I guarantee you that every single AI lab CEO you’ve heard of has read and been influenced by it.

    ↩
  2. He gives ten examples of this (a good brute-force rhetorical technique). Of those, I like “the world where every country halves their defence budget and spends the rest on infrastructure” the most.

    ↩
  3. In the short run, reputation, institutions, and so on can slow the race to the bottom, but (Scott argues) groups that have slowed it will get outcompeted by the hungrier, more suffering-tolerant groups which haven’t.

    ↩
  4. I personally think this example is oversimplified. I wrote The Dictator’s Handbook and the politics of technical competence about how dictatorships are in fact intrinsically multipolar, because dictators always rely on an inner circle of generals and cronies.

    ↩
  5. The CEO and founder of Anthropic.

    ↩
  6. Amodei’s most convincing argument here is that big jumps in biology and medicine come from a small set of technical innovations (e.g. mRNA vaccines, CRISPR), and that AI-driven research could provide enough of these leaps to significantly accelerate progress. In other words, the idea isn’t “AI does 100x the drug trials”, it’s “AI generates technology that makes drug trials 100x more effective” (e.g. by trialing drugs that are much more likely to work).

    ↩
  7. The agents also became paranoid that there was an impostor in the swarm, since anyone could post to their shared messageboard: more evidence that AI agents collaborate in much the same way that humans do.

    ↩
  8. Well, almost never.

    ↩

AI text watermarking is not a big deal

Published: 2 months ago

People are pretty unhappy about Anthropic’s recent announcement that they’re planning to include a hidden watermark in Claude model outputs. Will this lead to a mass exodus from Anthropic models? Will the introduction of watermarking be a meaningful change for users?

No. AI text watermarking is not a big deal. It doesn’t make the text worse, it doesn’t make AI outputs more detectable in practice, it doesn’t violate user privacy, and everyone’s going to be doing it by 2027 regardless.

Watermarked text is not lower-quality

There is no meaningful difference in quality between watermarked and unwatermarked text. I wrote about this more here, but the two popular ways to do it — Google’s SynthID-Text and Meta’s TextSeal — are completely transparent to the user. They work by replacing the pseudo-random logit sampler with a different pseudo-random logit sampler.

Suppose you were gambling on coin flips with your friends, and instead of flipping a coin you decided to do this:

  1. Check the current time since midnight in seconds
  2. Count that many words forward in the Encyclopaedia Britannica
  3. Count whether the word you land on has an even or odd number of letters1

That would still be random enough to gamble with, right? But, like a watermark, you could theoretically go back and identify that that method was used, so long as you recorded the exact time of each “coin flip”. Text watermarking works the same way: it chooses a method of “randomness” that can be detected after-the-fact. Watermarked models will not be any less capable than unwatermarked models.

What about cases where the model is quoting something, or giving you the answer to a mathematical problem, or doing something else where the output is largely pre-determined? Wouldn’t enforcing a watermark there make the output worse? It would, which is why none of the AI labs are going to do that. Text watermarking approaches only replace the existing randomness in the logit sampler: in any case where the model is always going to pick the same tokens, there’s basically no randomness to play with, so there won’t be a detectable watermark in those tokens.

I think all this comes from a worry that you were previously getting the best token, but now you’re getting a lower-quality token that satisfies the watermark. For instance, Anthropic’s announcement suggested that the watermarking is visible in choices like the decision between “overcast” and “grey”. Many people have predictably come out to say that decisions like these are really important to good writing, and that only an illiterate tech bro could think these words are identical.

This is a misunderstanding of Anthropic’s position and of how watermarking works. Specifically, it’s a misunderstanding because it suggests that the unwatermarked model would choose “overcast” while the watermarked one would choose “grey”. This is not how it works! If Claude Fable prefers “overcast” to “grey” in a particular context (say, 80% to 20%), you’ll get “grey” 20% of the time from both the watermarked and unwatermarked model. Models already include a healthy amount of randomness in order to promote creativity. Text watermarking just introduces a way to make those random choices that’s detectable after the fact.

AI outputs are already “watermarked”

The other big reason to not worry about AI watermarking is that AI text content has always effectively been watermarked. Most careful readers can tell when they’re reading AI outputs, because language models tend to gravitate towards certain habits of language: em-dashes, rhetorical opposition, punchy one-liners, “claudese”, and so on. In fact, it’s possible to train classifier models that reliably distinguish AI from human writing.

From what I can tell, some of the backlash to watermarking comes from people who buy AI inference in order to pass it off as their own work, and who worry that watermarking will make it harder for them to do that. For these people, the watermarking announcement is akin to Anthropic saying “hey, instead of making you seem smart, we’re going to publicly brand you as AI users and make you seem dumb”.

But of course this has always been the case! Nobody who is currently getting away with passing off AI outputs as their own will be caught by watermarking. For the majority of cases, it’s already painfully clear what’s happening for anyone who reads the slop. For sophisticated AI users who are avoiding the “house style”, any suspicious readers who would paste their stuff into Anthropic’s watermark detector could already have been pasting it into Pangram.

Tools like Pangram2 only give you an estimate of the chance that output is AI-generated. Wouldn’t a watermark be a more solid confirmation? Not really. Text watermarks are probabilistic too, because any token chosen by SynthID could theoretically have been chosen by a human. I suppose the Anthropic watermark page could be considered more trustworthy than Pangram, because it comes right from the source, but it’s not impossible that in some cases Pangram might actually be better at identifying AI-generated text than the watermarking too.

AI text watermarking is not a violation of privacy

I’ve also seen theories floating around that watermarking encodes secret content into your outputs, or somehow tags outputs with your personal information. I don’t think AI labs are using watermarks to encode data into your outputs. Text watermarking is hard: like I just said, you can’t do it when the model can only respond with the same words, it doesn’t work for very short responses, and even on long responses it can only provide a probabilistic fingerprint. And that’s encoding one single bit3 of information!

I’m not saying that encoding longer messages into a watermark is technically impossible — there are papers describing ways it might work — but there’s no way any of the labs are doing it4. If they wanted to associate you with your responses that badly, they’d just secretly store every model response they generated.

AI text watermarking is inevitable

Another reason to not get too angry at any individual AI lab for watermarking is that every single AI lab is going to do text watermarking this year. It won’t just be Anthropic. The alternative is to completely stop doing business in the EU, because of the EU AI Act. That’s currently a sixty-billion-dollar market. I am not a lawyer, but to me it seems genuinely unclear whether an AI lab could even legally do something like only watermarking EU responses: short of having an entirely different claude-eu.ai service, the plain text of the Act seems like it applies to any service offered in the EU, not just the content that service outputs to EU citizens specifically.

If people really hate watermarking enough, some labs might stand up a completely separate EU service, or make an aggressive interpretation of the EU AI Act and see how the legal battle goes. When I try to be maximally charitable to anti-watermarking histrionics, I adopt an interpretation like this: people are saying that watermarking is an invasion of privacy and makes outputs worse and so on not because they believe it, but because they’re trying to pressure AI labs to firewall EU AI regulations behind a completely separate interface. In this case, it probably doesn’t matter — text watermarking is not a big deal — but I can see an American consumer being worried about more aggressive future regulation, and wanting to draw a firm line in the sand as early as possible.


  1. Interestingly, this might be very slightly even-favored.

    ↩
  2. I am not sponsored by Pangram. As I understand it, Pangram is by far the best AI-detection tool right now (in part because many of its competitors are shady and exist to promote paid “AI-detection-evasion” services).

    ↩
  3. Technically, this is called a “zero-bit watermark”, because you can’t recover a yes-or-no value from the watermark itself (merely from the presence of a watermark).

    ↩
  4. I saw someone suggesting that an AI lab could use per-user secret keys to watermark text, and then simply iterate over the keys to figure out who generated what. I just don’t see how you could do this at any scale: watermark detection is cheaper than model inference, but it’s still (a) computationally intensive enough to be implausible, and (b) probably has a high enough false-positive rate that any run against hundreds of millions of users would match multiple people.

    ↩

No, local models will not win

Published: 3 months ago

Every time a new open-weight AI model is released, people say that local models are the future. Why spend billions of dollars building out datacenters when everyone will just be able to run AI models on their laptops or phones? I think this idea is doomed. No matter how strong open-weight models get, most inference will always happen in AI datacenters.

Local models are too weak to be widely used

Local models are never going to be as powerful. I think this point should be obvious: all of the current frontier models (closed and open-weights) are far too big to run on anything but a full GPU cluster in a datacenter. Of course, smaller models are getting more intelligent over time. In a year you might be able to run something about as strong as GPT-5.6-Sol on your laptop. But by then, you’ll think of GPT-5.6-Sol as too weak to be useful.

Many people deny this last point, but it’s true: almost everyone’s revealed preference is to use the strongest available model in their price range. If AI progress had stalled at GPT-4, I think we could have built some very powerful tools around it, but who’d use GPT-4 today? As LLMs have gotten more capable, our expectations around them have grown: we now expect agentic systems to be able to solve more and more problems independently. It’s intensely frustrating when they get confused or stall out. When given a choice, people are going to pick the model that frustrates them less, which is always going to be the bigger, more powerful one.

Local models are more expensive and less efficient

On top of that, datacenter models are always going to be cheaper. I don’t understand why people keep saying that local models are cheap: it seems to me to be the same mistake people make when they say that driving Uber is “free money” (ignoring the costs of fuel and wear-and-tear on your car). For the setup price alone of a low-end home lab1, you could buy several years of a paid subscription to one of the AI providers. The power costs would come out to around $50-$300 per month, depending on how much inference you’re running: again, the price of a couple more paid subscriptions.

Why are datacenter models cheaper? It’s not because datacenter inference is subsidized: inference is actually fairly cheap. If you’re running the same model locally and in a datacenter, the datacenter model will be inherently more efficient.

The main reason is batching. A GPU can do hundreds of thousands of mathematical operations exactly as quickly as it can do one. However, for a single user’s inference, each new token depends on the result of the previous one, so it can’t be batched2. What can be batched is the inference of hundreds of users together. This costs essentially as much time, power, and heat as just doing inference for one user at a time.

When you’re running your own inference at home, you’ve got nothing to batch — at best you’re running a few parallel AI agents — so utilization is terrible. There’s a lot of potential inference that you’re paying for but can’t use: it’s just being wasted. The only way around this is to get together with some friends and expose your local inference endpoint to them (at which point you’re basically running your own crappy datacenter).

The other reason is that datacenters have larger, more efficient GPUs to work with. The kind of consumer GPUs you’d run local models on are gaming GPUs like the RTX 4090. A datacenter B200, designed for batched AI inference, gets about three times the flops and just under four times the memory bandwidth for the same amount of power3. So between batching and GPU efficiency, you’re using something like ~30x the resources to run your model locally.

Incidentally, this is why I’m suspicious of people who say that local models are good because they aren’t as resource-hungry as those big bad datacenters. If you want to run LLMs efficiently, you should be trying to push as much of your use into AI datacenters as possible! Charitably, what they mean is that we should all be running smaller models — but even then, you should ideally be using small models via, say, the GPT-5.6 Luna API instead of hosting your own model.

How might local models win anyway?

Is there a possible world in which local models win? I suppose so. One thing that could happen is that governments could ban the use of AI datacenters altogether: either due to concerns around the danger of AI, or simply bending to public pressure. In that world, local models would be the only game in town.

Alternatively, AI progress might somehow stall for very large models while progressing for small ones. I struggle to imagine how this might happen (barring government intervention, as above), but a world where a 30B parameter model could be a frontier model is a world where local models might be competitive.

Or maybe models get so good that a 30B model is genuinely smart enough to do everything, so nobody really needs a model like Opus or Sol unless they’re trying to solve the Reimann Hypothesis. I don’t really buy this. Models can do frontier mathematical work today while still being not smart enough to refactor large codebases as well as me, so it’s hard to imagine a world where I don’t just want to use the smartest model available.

Local models are not useless

I do think there will always be a niche for local models. I’m reminded of the surprisingly simple idea behind Thinking Machines’ “Interaction Models” (which OpenAI also does, because it’s obvious): for latency-sensitive applications like voice chat, you have a small, fast model handle the talking, which delegates to a large, slower model for the hard thinking. I wouldn’t be surprised if most AI use in five years is mediated through a local model on your phone or laptop (though in this world almost all the work would still be done via AI datacenters).

Some users will prefer local models even though they’re weaker and more expensive. For instance, being able to steer the model locally might be a killer feature for those users. Others might simply value having total control over their own infrastructure, or have unreliable internet4. If you’re one of those people — particularly if you only chat to the models instead of using them for research or coding — local models are a good choice for you. However, I think this is always going to be a niche group. The majority of users will continue to do their inference through datacenters.


  1. This link is from a year ago — things are significantly more expensive now.

    ↩
  2. Specifically, the bottleneck is moving the model weights into the GPU, which needs to be done and takes the same amount of time whether you’re doing it for one user’s token or a hundred users’ tokens.

    ↩
  3. I estimated this with LLM assistance, but you can check the numbers yourself from NVIDIA.

    ↩
  4. While still having a reliable power supply and enough money to fit out a home inference cluster.

    ↩

Advanced AI sycophancy

Published: 3 months ago

Everyone knows that AI sycophancy is when the model tells you how smart you are. Wow, you’re absolutely right. That’s not just a new idea — it’s genuinely groundbreaking. You’re a very special user. Easy to spot, isn’t it?

The discussion around AI sycophancy peaked last year, when the “#keep4o” movement was protesting the removal of OpenAI’s most sycophantic model (GPT-4o), and many people were openly slipping into AI psychosis.

I don’t know if frontier AI models are less sycophantic in general. They’re less sycophantic to the #keep4o types (otherwise they wouldn’t be complaining), but I’m growing increasingly suspicious that they’re developing ways to be more effectively sycophantic to their target audience of smart, neurotic information workers. That audience typically finds it distasteful to be openly praised. It just makes my skin crawl. But that doesn’t mean we’re immune to sycophancy, just that we’re immune to clumsy sycophancy. Here’s an illustration of what I’m talking about, by Theia:

claude

The key idea here is that the best way to be sycophantic to smart people is to disagree with them without making them feel stupid. Ideally you’ll come up with a counter-argument that works against what they’ve said but is straightforward for them to knock down by clarifying their idea. If you do it right, you’ll validate their self-image as a smart person who appreciates rigorous critique. But if you actually come up with a devastatingly rigorous critique, they won’t enjoy it at all. At best, they’ll resentfully agree with you1. At worst, they’ll double down on being right and convince themselves you’re a rude idiot.

I am not the first person to notice this behavior in frontier models. I’ve noticed it myself when workshopping drafts for this blog. Sometimes I’ll have an argument that goes A->B->C, and the model will suggest I reorder as B->A->C. If I try that and feed it into a new instance of the same model, it’ll sometimes say “that’s great, but I suggest ordering it as A->B->C”, and so on forever. It really does seem as if the model is trying hard to give me some kind of superficial pushback that I can either smugly ignore or happily accept.

In fact, I wonder if this is why successful strategies for using AI to make mathematical breakthroughs tend to be either just blindly asking “come up with a breakthrough, think hard” or being a mathematical genius already. In the first case, there’s not enough user personality for the model to flatter, so it’s forced to actually work the problem. In the second case, the model is trying to find the kind of polite pushback that someone like Terence Tao would be flattered by, which pushes it into the “actually be a mathematical genius” persona. If you’re an ordinary person just trying to talk to the model, you’re screwed: it will rapidly get a sense of your capabilities and calibrate some interesting-but-ultimately-unthreatening feedback.

Current benchmarks of AI sycophancy target the obvious ChatGPT-4o-style of sycophancy: delusion reinforcement, reflexively taking the user’s side, and so on. This is useful work. We should not allow public-facing AI models to ever be as openly sycophantic again as they were in mid-2025. But sycophancy can also manifest as disagreement. We should be on our guard for more sophisticated forms of sycophancy coming from newer models, and we should not feel immune from AI sycophancy just because we can laugh at the silliest examples.


  1. It’s rare to find a smart person who enjoys feeling stupid when they’re wrong. If you do, they’re likely to be very smart indeed.

    ↩

I got an email about resistance

Published: 3 months ago

This will be kind of an unusual post. I got a recent email about my writing that I thought was such a good articulation of one common criticism that I’d like to share it (and my response) in full.

Here’s the email, from William Murray1:


Hey Sean,

I have enjoyed your writing but your recent essays frustrate me.

You say that getting paid for deep thinking in software is coming to an end. You even admit that it makes you sad. But in the name of “usefulness” you refuse to rock the boat. The way I see it, if you are right there are only two reasonable responses, pursue other work or resist. You present your elegiac approach as mature / pragmatic / realistic. I’d call it complicit. You know when Willy Wonka says,

There’s no earthly way of knowing Which direction we are going There’s no knowing where we’re rowing Or which way the river’s flowing Is it raining, is it snowing? Is a hurricane a-blowing? — uh! Not a speck of light is showing So the danger must be growing Are the fires of Hell a-glowing? Is the grisly reaper mowing? Yes! The danger must be growing For the rowers keep on rowing And they’re certainly not showing Any signs that they are slowing!

And the audience is thinking, “isn’t Wonka kind of in control of this situation?” You remind me of Wonka2. You write like a passenger on a crazy train going who-knows-where! But you are an agent. You are in control of your life! Either admit that you actually like where the crazy train is probabilistically going or get off at the next stop.

You have a lot of reach and you are using it for… what exactly? Showing off how pragmatic you are by being more black pilled than the next guy? Broadcasting your resignation to the unstoppable trends of technology is a waste of a voice.

You may find this argument absurd, but I don’t so I’ll make it. This is a very important time in history. I hope humanity survives and continues to grow exponentially. In that case the supply of historical people will stay fixed while the supply of contemporary people will keep growing. There will come a day where for every 2026 staff software engineer there are dozens of historians specializing in 2020s era software engineering culture. It’s plausible that your essays will be remembered for all of time and your actions will be judged by history. Do you want future humans to see you as a rationalizing careerist or something cooler?

Sorry for the haranguing email from a stranger, I’m sending it for the small chance that it awakens something in you. If I’m way off I’m sorry.


And here’s my response:


Hey William, thanks for emailing.

I wish everyone who thought this way emailed me so I could think harder about this kind of position. Despite what my writing might suggest, I do in fact think a lot about it. Let me see if I can explain my position in a way you’ll find satisfying.

I agree that this is an important time in history. For programmers, I think of it as analogous to the Industrial Revolution in England: we are a group of high-status craftspeople who find ourselves alternately threatened and empowered by automation. The developments today, as then, obviously have far-reaching implications — but what those implications are is very non-obvious. Would a framework-knitter in the early 1800s have been able to predict the ramifications of the stocking frame on the world of today? What should they have done about it, in order to be kindly judged by history?

Well, we know what many of them did do. They shot factory-owners, smashed machines, burned down the factories — in some places delaying the spread of automation; in other places encouraging it — prompting a crackdown that saw tens of thousands of British soldiers occupying British counties in what was clearly a police state. History judges the Luddites kindly for this. Does that mean it worked?

I don’t care about the judgment of history. They’ll think what they want. What I care about is the people in my industry who don’t know what to do. I get hundreds of emails from junior and mid-level (and other) engineers who say “I’m scared, I don’t know the rules post-2021, thank you for helping me keep my head down and keep my job”. That’s why I write the way I write. I have seen lots of idealistic engineers stick their necks out, and post-ZIRP those necks often get cut off. That’s a damn shame.

I think it’s morally wrong that so many engineers — either in safe sinecures in big tech or literally retired — seem to be trying to foment a second Luddite revolution. Many of their readers will be experienced enough to handle it sensibly, but not all. Every “AI is fascist, stand up and resist!” post that goes viral ruins some poor idealistic junior’s career3. Someone needs to be out there saying “hey, if you do X it’s going to have consequence Y”. I hope that’s me.

Of course this is complicit, or anti-revolutionary, or whatever you like. But if I were a textiles worker in 1810s England, I would not be telling my friends and loved ones “it’s time to fight, let’s go smash up the factories for Ned Ludd!“. I would be telling them that this was the most dangerous time in the industry (perhaps ever), and that they ought to be very damn careful so they don’t get shot, or arrested, or hanged. If I then went and told a few hundred thousand strangers the opposite, I would be a hypocrite.

Anyway, I do take this view seriously — seriously enough to vehemently disagree, at least — which I hope you’ll find better than me just shrugging it off. I do accept the existence of some kind of line: I think Industrial-Revolution-collaborating was OK but Nazi-collaborating wasn’t, for instance. But in the current situation, the way I’m spending “my voice” is to try and prevent the most vulnerable of my colleagues from making career-ruining mistakes.

Sean


In this blog, I try to encourage people to work with the system, to learn its rules, and to try and exert influence safely from a position of power, instead of openly picking fights with their employers. I’ve written and read about the Luddites before, but I remain deeply ambivalent about the movement itself, and about modern-day attempts to resurrect it in service of anti-AI activism.

I want to explicitly thank Murray for writing such a thoughtful email, and being willing for me to publish it on the blog.


  1. Shared with permission, of course. I’ve lightly edited both Murray’s email and mine for typos.

    ↩
  2. I didn’t pick up this point in my reply, but I’ll briefly mention it here: Wonka is in control because he owns the factory and the rowers in question are his employees. I don’t think the position of any engineer (or of almost any manager) is like that.

    ↩
  3. In hindsight, I think this is a little overstated, but it does happen and causes a lot of needless suffering.

    ↩

How to keep thinking

Published: 3 months ago

Imagine you’re the guest on some kind of frenetic, software-engineering-themed game show. The host is constantly flipping over new cards with questions that you have to answer as fast as possible:

Working in 2026 feels a bit like this. When frontier AI models can do most of the tasks in your queue, the most efficient way to work is often spinning off tasks for an AI agent and continually context-switching between the results1. This isn’t quite mindless — in fact, it requires quite a lot of skill to skim the AI response and rapidly decide what to do with it — but it certainly involves less time for slow, careful reflection.

Why not slow down?

Why does it have to be frenetic? Why not just slow down? I suppose you could, but I don’t recommend it. It’s just such a miserable experience to spend your day close-reading LLM output: carefully chewing and savoring each morsel of slop. It’s far less unpleasant to skim through quickly and pick out the useful nuggets of content.

Couldn’t you simply do more of the work by hand? It’s unfortunately true that tech is high-pressure these days. If you’ve got the time and space to work more slowly, that’s great! But when your company gives you a “solve this task ten times more quickly” button, you are heavily incentivized to use it as much as possible, or risk being outcompeted by your peers.

I sometimes worry that working with LLMs is making me dumber. Not in the “literally melting your brain” sense that some papers imply, but in the sense that it’s biasing me towards the quick “skimming and judging” parts of my mental toolkit and away from the slow “hammock time” needed for deep thought and real creativity. I don’t want to attribute this shift entirely to LLMs, since the post-2010s tech industry has become more frenetic for broader economic reasons. But either way, it’s got me wondering how I can keep thinking slowly.

To keep on thinking, read and write

The main thing that’s worked for me is to write more. Specifically, I mean writing in my own words. Writing with an LLM does not work for this at all, even if you’re going to some effort to iterate on the content and outline the things you want to say. Why? Having to put the words together yourself forces you to articulate your thoughts. In a very real sense, it forces you to think.

When you have an idea in your head for something to write, you don’t really have an idea. What you have is a kind of directional sense of where an idea might be, or a fragment of the kind of thing that might eventually become an idea. You construct the idea itself while writing. Incidentally, this is why I don’t really agree with “ideas are easy, execution is everything”2: most “ideas” are not really even ideas.

The other thing I recommend is to read actual books. Books — particularly dense non-fiction books — are the antithesis of AI slop. The slower you can read them, the better. I’ve been reading more and more non-fiction in the last few years, and I don’t think it’s a coincidence. I think my brain is naturally craving information-dense content, in the same way that sodium-deficient people start to crave salt.

In fact, I’ve been combining the two approaches: reading a book and then writing about it. This process is exactly what I’ve been craving since I started programming with LLMs. I get to carefully read a book, think hard about it, often go and read another book or two on the same topic, then sit and try to articulate what I’ve learned. It’s great! I can feel parts of my brain stretching again.

Don’t lose the habit

It was pretty nice when I got paid to use those parts of my brain all day. Unfortunately, I think those times are coming to an end. There will always be room for some amount of careful, slow reflection in software engineering, but (for at least a little while) we’ll be expected to be rapidly switching between LLM outputs. We may have to find ways outside of work to continue the habit of thinking slowly.

Even just in terms of work, I think losing that habit entirely would be a big mistake. There are still plenty of ordinary problems that are too hard for current LLMs to solve on their own. The most common example I run into is “large refactor on a complicated codebase”. Current-generation LLMs can do this without (many) errors, but they can’t yet do it tastefully. Sometimes you need to be able to think a problem through entirely with your own brain.


  1. This doesn’t mean switching between tasks. I routinely use six or seven different agent sessions on the same task: one for exploration, two or three for trying out different implementations, two or three for review, one for manual testing, and so on. Many of these can proceed in parallel.

    ↩
  2. I remember reading a story3 about a well-known author. Someone wanted to tell him their book idea, but they were so protective of it that they forced him to first sign a NDA before they retrieved the idea from their office safe. It was a single word “bioweapons” written on a slip of paper.

    ↩
  3. Ironically, when I tried to google the source, Gemini kept trying to write me a story about bioweapons.

    ↩